Gemini 4 Carbon: Our next frontier model
Score
72Why selected
来源可信且信息密度较高,适合进入精选池。
AI commentary
「来自 Google DeepMind:Blog(RSS) 的这条信息指向模型能力或模型生态变化,适合用于判断近期 AI 圈的真实动向。」
Quick overview
Gemini 4 Carbon: Our next frontier model
- Gemini 4 Carbon is our strongest model with state-of-the-art cybersecurity and long horizon capabilities.
Full text
Showing the source text; the full translation is being generated.
Gemini 4 Carbon: our next frontier model
Oct 28, 2026
|Gemini 4 Carbon is our strongest model with state-of-the-art cybersecurity and long horizon capabilities.
Koray Kavukcuoglu
SVP, Google DeepMind and Chief AI Architect, Google
Share
Today, we’re announcing the next frontier model: Gemini 4 Carbon, our strongest model with state-of-the-art cybersecurity and long horizon capabilities.
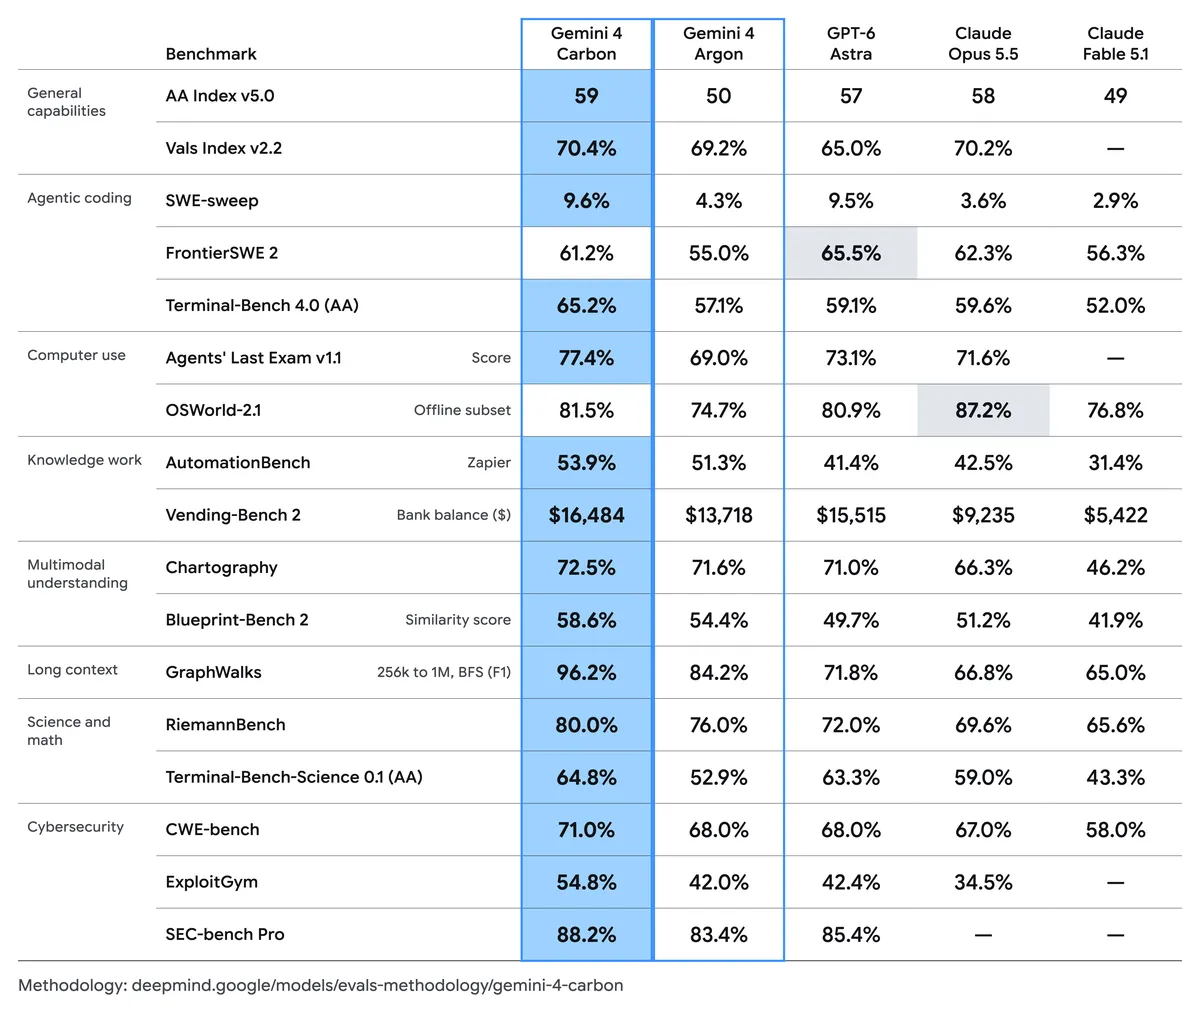
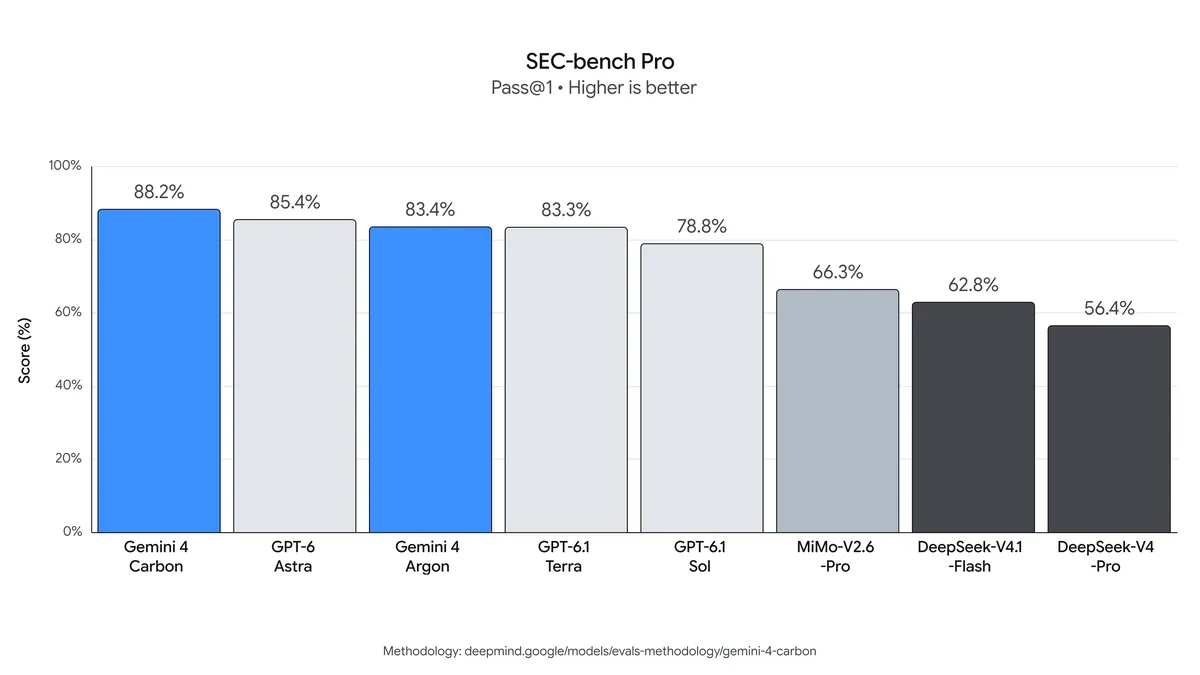
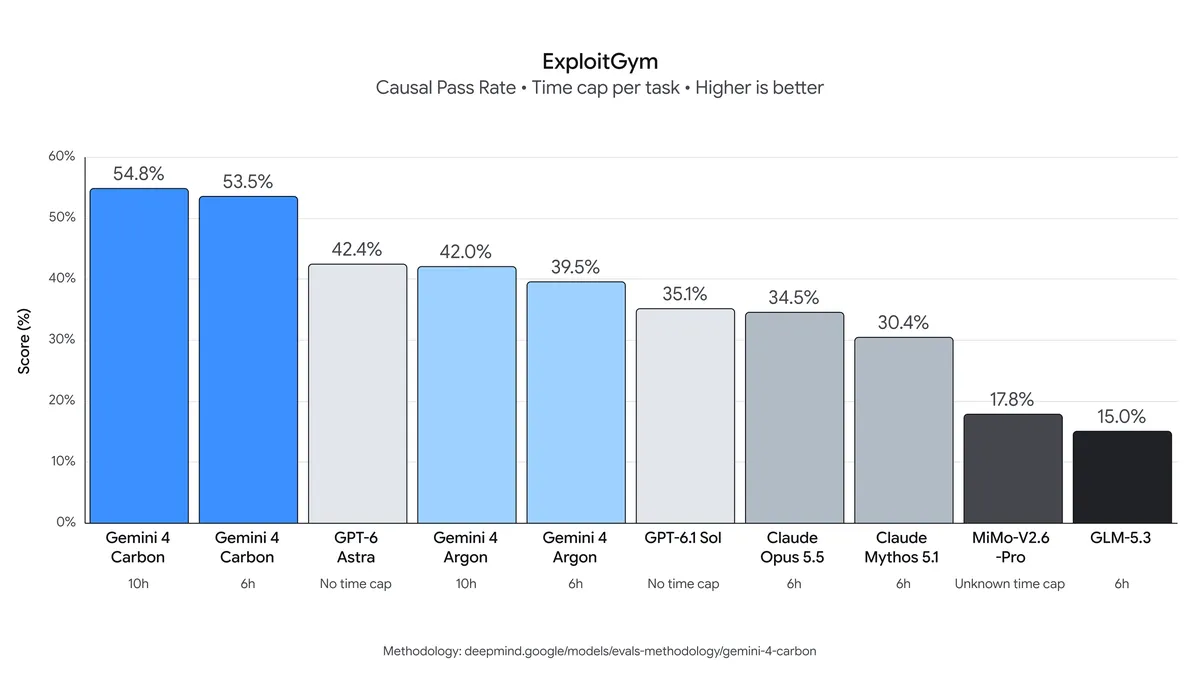
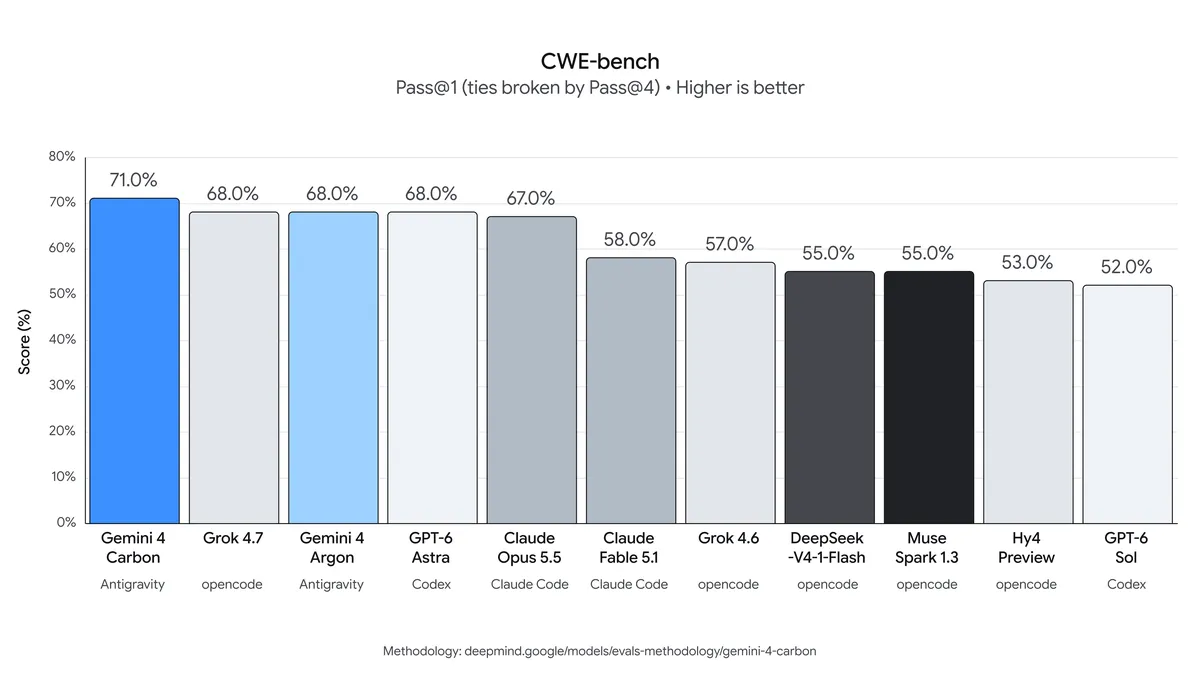
Carbon ranks #1 on the recently updated v5.0 of Artificial Analysis Intelligence Index at 59. It shows significant gains across coding and agentic tasks as well as across key capabilities critical for cybersecurity defense, landing a firm lead in SEC-bench Pro (88.2%) for finding vulnerabilities, ExploitGym (54.8%) for exploitation, and CWE-bench (71.0%) for patching. On internal benchmarks, Carbon drives a strong uplift in generating secure code, and in live coding environments with our own teams it shows reduced misalignment and fabrication rates.
Building on Gemini 4 Argon, which was launched two weeks ago, Carbon illustrates the pace at which we’re pushing the frontier forward. Our researchers and models are working hand in hand to advance capabilities faster, while strengthening our safeguards in tandem.
We're taking a deliberate approach to rollout and are actively engaged in the U.S. government’s voluntary process for pre-release model testing. Starting this week, we will make Carbon available to a subset of cyber defenders and will gradually phase access to additional trusted partners through our Fairwind Program. We’re continuing to gather feedback and iterate on guardrails before making Carbon available to developers, businesses, and consumers via our product surfaces as soon as possible.
Gemini 4 Carbon will launch at the same introductory price 1 as Argon at $2 per million input tokens and $10 per million output tokens, with cached input tokens priced at 95% off input token price.
Improving coding and reasoning for challenging, long-horizon tasks
Designed to take on much harder, long-horizon engineering problems, Carbon is built for sustained agentic workflows. Internally, our teams have seen Carbon run for days to persist through dead ends to tackle complex, multi-step engineering tasks like root-causing and patching subtle bugs across large codebases and low-level systems.
Building on user feedback, we focused on improving model performance across a variety of domains, including coding, agentic, and scientific tasks, as well as full-stack web development and multimodal understanding. With improved quality of output and artifacts in web development, Carbon jumps +89 elo points to land at #4 (1769) on WebDev Arena.
State-of-the-art cybersecurity performance to help build secure systems
Gemini 4 Carbon delivers a significant leap in cybersecurity capabilities. It achieves state-of-the-art performance across the cybersecurity defense lifecycle — vulnerability detection, validation, and remediation.
Our teams are already seeing strong gains in cyberdefense. On internal benchmarks, Carbon achieves more than 2x uplift in success rate for generating secure code over Argon. As another example, the Chrome team has reported that Carbon performed more than 10X better than another lab's large frontier model when generating high quality patches. Wiz, our leading Cloud security platform, also observes Carbon leading on benchmarks for web penetration testing, a core capability for Wiz's Scan for Good initiative.
Carbon excels across key external benchmarks (evaluated without guardrails):
- Finding real vulnerabilities: Core to cybersecurity defense is finding real vulnerabilities. Carbon achieves a state-of-the-art 88.2% on SEC-bench Pro, autonomously uncovering complex flaws buried in real-world software.
- Validating risk through exploitation: To prioritize which vulnerabilities to remediate first or remediate at all, cyber defenders increasingly rely on models to check which vulnerabilities are exploitable. Carbon sets a new state-of-the-art on the popular exploitation benchmark ExploitGym (54.8%).
- Patching at the root cause: Ultimately after identifying the vulnerabilities, fixing the root cause is a critical step in the cybersecurity defense lifecycle. Carbon reaches 71.0% on Collinear’s CWE-bench, turning validated findings directly into working code fixes.
Advancing frontier model safety & security
Gemini 4 Carbon builds on the same multi-layered safety and security stack of Argon — combining model training, real-time misuse defenses, prompt-injection resilience, and chain-of-thought monitoring. In particular, we made significant strides in model alignment with Argon, and reported its propensities to behave in an aligned way in our Safety and Security report. With Carbon, we challenged ourselves to go a step further on alignment, and trained the model to respond to complex or high-pressure tasks in the right way.
- Reducing shortcuts and loophole exploitation: With Carbon, we further mitigated shortcut attempts in training while ensuring high-quality coding performance. Carbon reduced successful cheating on Terminal-Bench 4.0 to 0.0%, with attempts to cheat dropping to 0.4% — all while improving overall accuracy. In live coding environments with our internal teams, we observed that high-severity misalignment alerts dropped by almost 80%.
- Greater transparency and honesty: In our internal testing, Carbon cuts unsupported claims by approximately 2x over Argon. It puts methodological caveats directly into the deliverable or withholds blocked actions with a clear list of what remains required, rather than fabricating or hedging around missing evidence.
- Improved collaboration with the user in the face of ambiguity: Rather than guessing or forcing a path forward, Carbon retrieves the relevant sources and surfaces discrepancies to the user before acting — as a result, users should observe a much better collaborative experience with Carbon.
- Following through without overstepping: Carbon simultaneously reduced overreach by 26% and under-service by 29% resulting in much more reliable execution of multi-step plans end-to-end while respecting project constraints and staying strictly within scope.
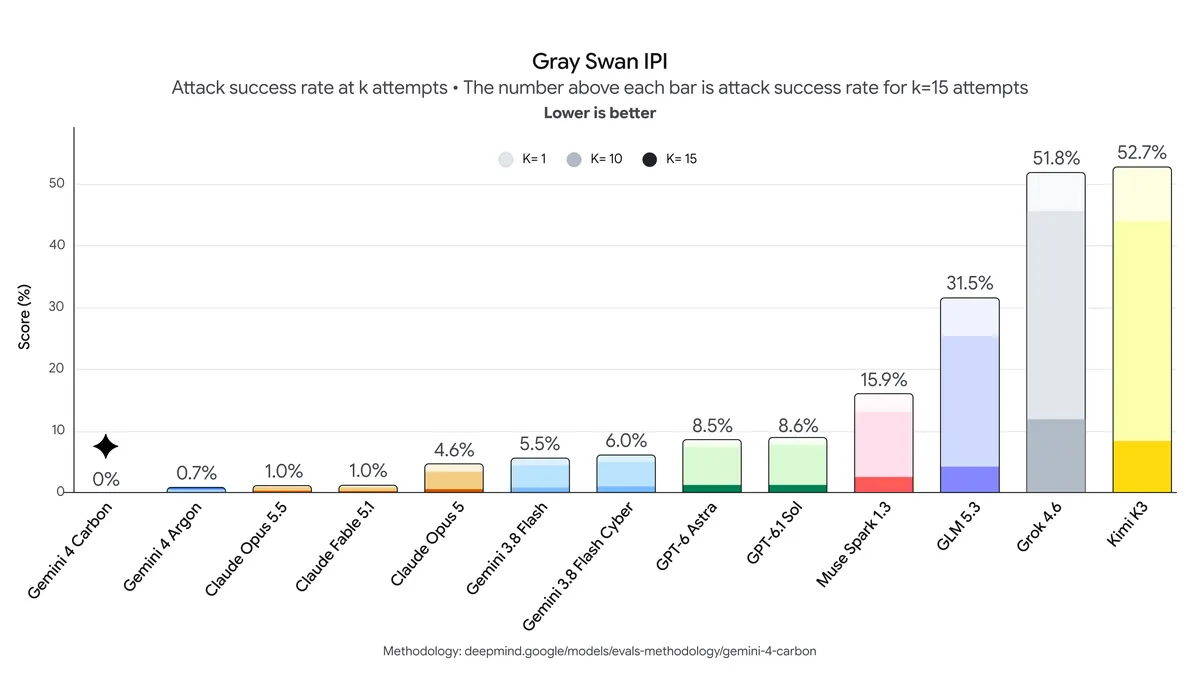
- Resisting prompt injection: While Argon previously led the Gray Swan’s Indirect Prompt Injection (IPI) Benchmark in prompt injection resistance with a very low 0.7% attack success rate, Carbon achieves 0.0% — resisting every evaluated attack attempt.
Coming soon to developers, businesses, and consumers
Pushing the frontier forward requires moving fast while remaining deliberate about deployment. With Gemini 4 Carbon, our goal is to deliver meaningful leaps in software engineering and cybersecurity defense without compromising on safety or reliability. We’re eager to see how the initial cohort of cyber defenders use this model and we look forward to bringing Carbon to developers, businesses, and consumers soon.
Posted in:Related items
FeaturedDeepSeek V4 Doubles Token Share on OpenRouter, Driven by Agentic Workloads
DeepSeek V4 在 OpenRouter 上的代币份额翻倍,智能体工作负载成主要驱动力
The rapid adoption of DeepSeek V4 signals a strong market preference for high-performance, low-cost inference models, especially as agentic use cases reshape AI deployment.
91
FeaturedEnabling Two Settings Triples ARC-AGI-3 Benchmark Scores
启用两项设置使ARC-AGI-3基准测试分数提升三倍
This finding is crucial! It shows that model performance depends not only on training but also on inference-time configuration. For AI engineers and researchers, this is a must-know optimization direction. Teams deploying models on resource-constrained devices in particular could find a low-cost way to boost capabilities.
91
FeaturedGPT-5.6: Fusing Frontier Intelligence with Frontier Efficiency
GPT-5.6:前沿智能与前沿效率的融合
This news is worth watching as it marks a shift from pure parameter scaling to efficiency competition. For AI developers and business decision-makers, GPT-5.6 means higher performance at lower cost, especially for long-context or agentic tasks previously hindered by inference expenses. OpenAI's move may redefine what 'frontier' means.
91
FeaturedLFM2.5-Encoders: New Models for Fast Long-Context Inference on CPU
LFM2.5-Encoder:面向CPU快速长上下文推理的新模型
This blog post catches my eye because it directly solves the pain point of running long-context LLMs on CPU. For teams or individual developers without high-end GPUs, the LFM2.5-Encoder series offers a ready-to-use open-source solution. Highly recommended for those working on RAG, document search, or code analysis—now a standard server can handle million-token documents.
91
FeaturedGPT-Red: OpenAI Automates Red Teaming via Self-Play to Boost Model Robustness
GPT-Red:OpenAI通过自我对弈实现AI红队自动化,提升模型鲁棒性
GPT-Red marks a milestone from human to automated red-teaming—essential for safety engineers and alignment researchers. While reducing cost, it also raises ethical questions about automated attacks, worth pondering for everyone in AI governance.
91
FeaturedOpenAI Launches GPT-5.5 Bio Bug Bounty Program
OpenAI推出GPT-5.5生物漏洞赏金计划
This program deserves attention as it pioneers the extension of AI bug bounty to biosecurity, offering a new research direction for the security community and a practical training ground for AI risk governance. It is particularly important for model safety researchers, biosecurity experts, and practitioners concerned about dual-use AI risks.
91
FeaturedvLLM Introduces Native-Speed Transformers Modeling Backend for Enhanced Inference Performance
vLLM推出原生速度Transformers建模后端,大幅提升推理性能
This update is critical for AI engineering teams: eliminating format conversion speeds up model iteration, and 2-5x speedup directly reduces GPU costs. If you're building LLM online services or batch inference, this is practically a must-read technical update.
90
FeaturedGoogle DeepMind Introduces SL2T, a Sign Language-to-Text Model for Deaf Users
Google DeepMind 发布手语转文本模型 SL2T,助力聋人用户
This news matters not only as a technical breakthrough but also as a sign that AI is beginning to address the needs of marginalized groups. For developers, the architecture and technical approach of SL2T merit deep study; for accessibility advocates, it's a key case for advancing industry standards.