DeepSeek V4 Doubles Token Share on OpenRouter, Driven by Agentic Workloads
Score
92Why selected
Token share doubling driven by emerging agentic workloads shows significant industry impact; slight deduction due to platform-specific data limitation.
AI commentary
「The rapid adoption of DeepSeek V4 signals a strong market preference for high-performance, low-cost inference models, especially as agentic use cases reshape AI deployment.」
Quick overview
DeepSeek's token share on OpenRouter has doubled over six months, with V4 Flash leading the growth. Agentic workloads are the primary driver, highlighting strong demand for efficient, low-cost inference models.
- DeepSeek's token share on OpenRouter doubled in six months.
- V4 Flash is the key model, ideal for agentic use cases.
- Agentic workloads (autonomous loops, multi-step reasoning) drive adoption.
Full text
Showing the source text; the full translation is being generated.
DeepSeek V4 Is Earning Agentic Token Share
OpenRouter ·6/30/2026
 On this page
- Model authors driving token usage today
- V4 is the first DeepSeek model sufficient for agentic workloads
- DeepSeek and the rise of Chinese models
- Methodology Notes
DeepSeek, the company that for many is still synonymous with open source LLMs, released its new flagship V4 models on April 24th.
V4 reset the trajectory. In six months DeepSeek roughly doubled its share of tokens on OpenRouter, and agentic workloads drove most of that gain.
Model authors driving token usage today
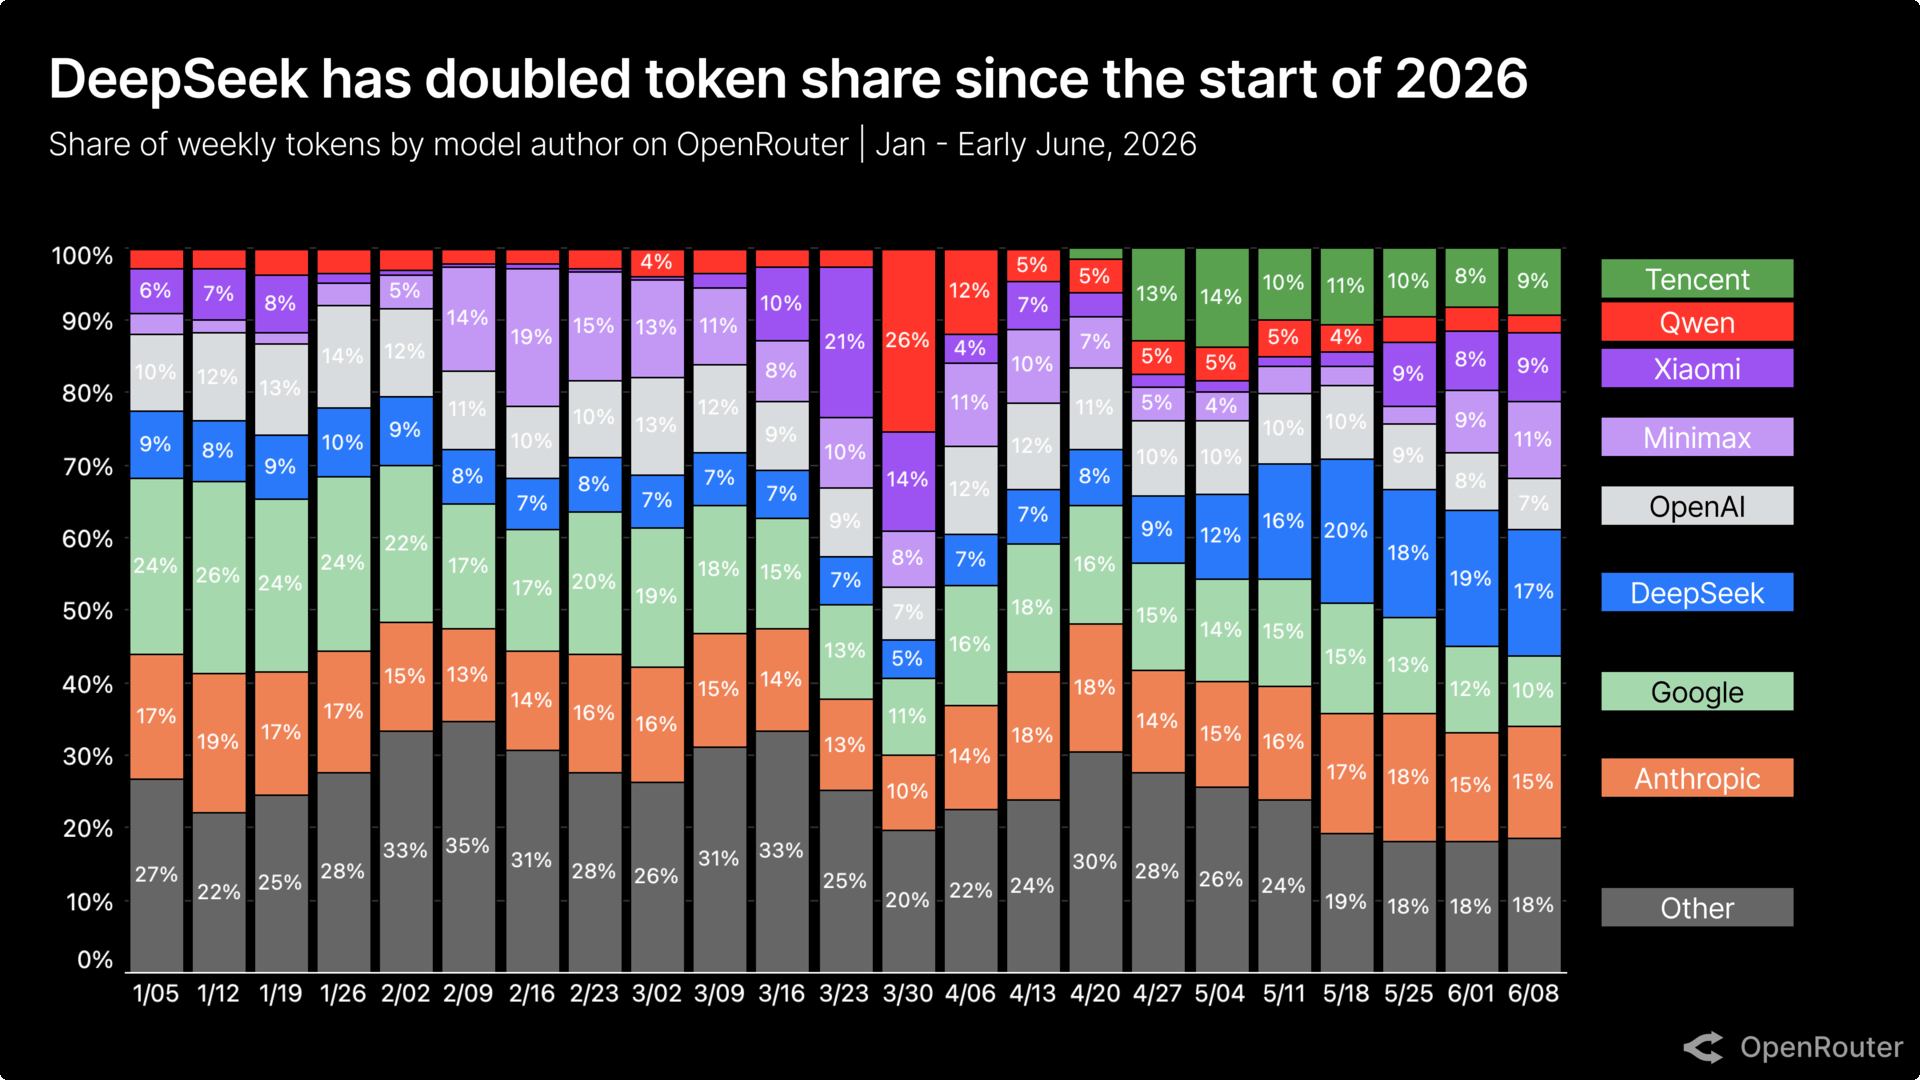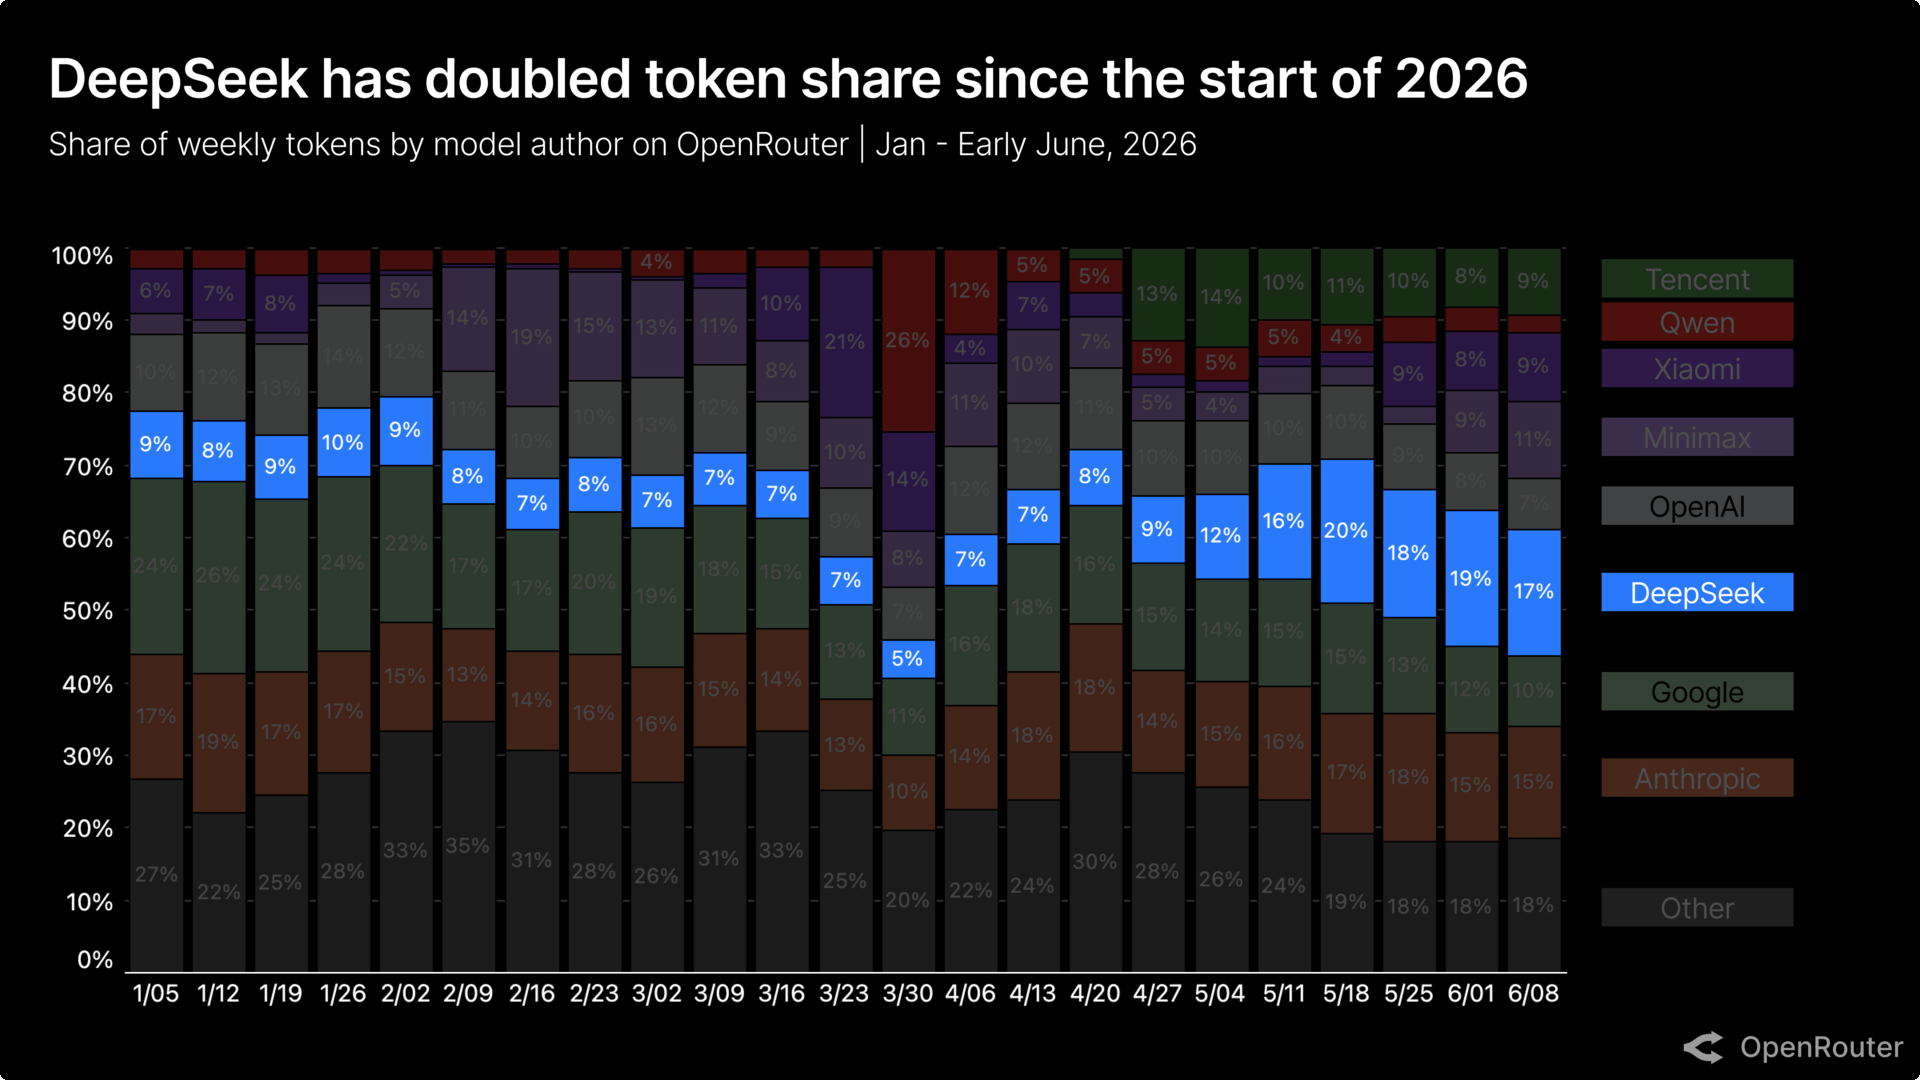
DeepSeek began the year holding just under 10% of the token flow weekly across OpenRouter. As agentic work began to take hold in February and March, driving up token usage at unprecedented rates, DeepSeek actually fell to 5% of total tokens. The company was being squeezed from above by proprietary models and below from a wave of other open source LLMs.
The release of the V4 model family had an immediate positive impact. By the start of June, DeepSeek had earned nearly 20% of token share and has been the top model on OpenRouter since mid-May.
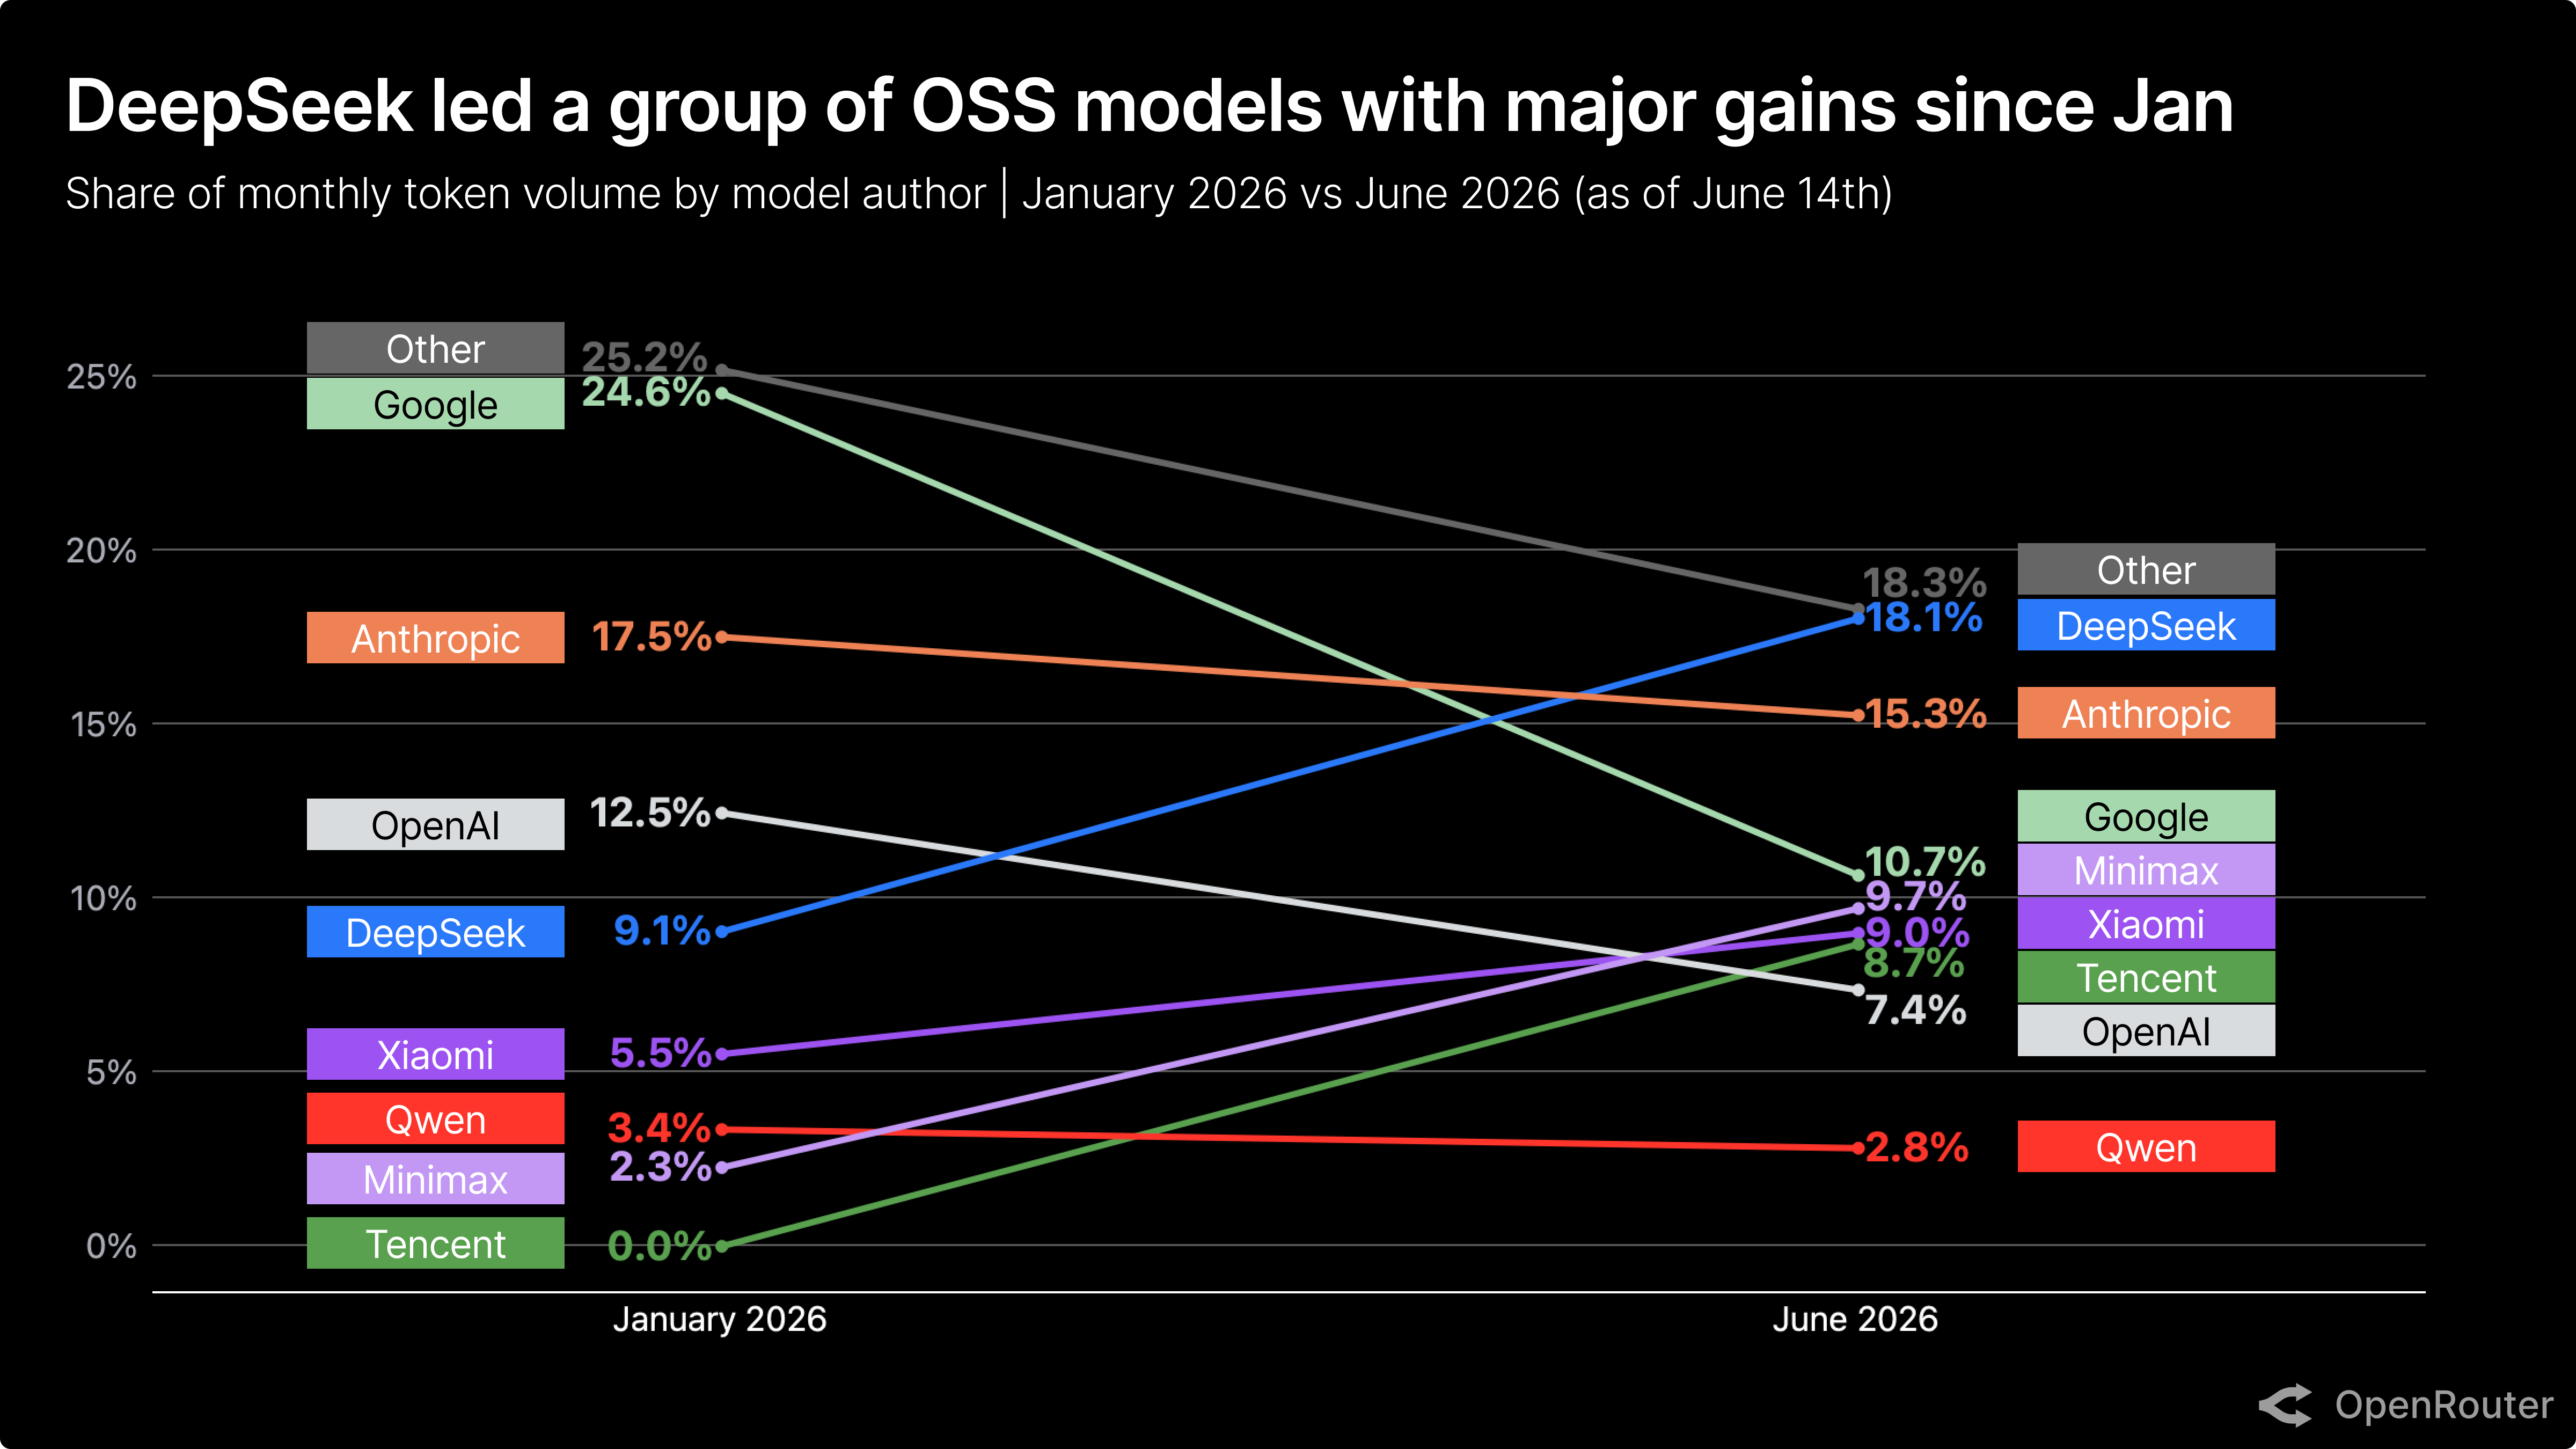
A direct comparison between January and June 2026 shows just how quickly preferences can shift between model authors. DeepSeek effectively doubled its token share over the period (from 9% to 18%) but many other model providers experienced major swings in fortune.
A group of Chinese open source models, including Xiaomi, Minimax, and Tencent, all saw their share of tokens rise over the past 6 months. This seems to have come at the expense of a couple of the leading American model companies, specifically Google and OpenAI.
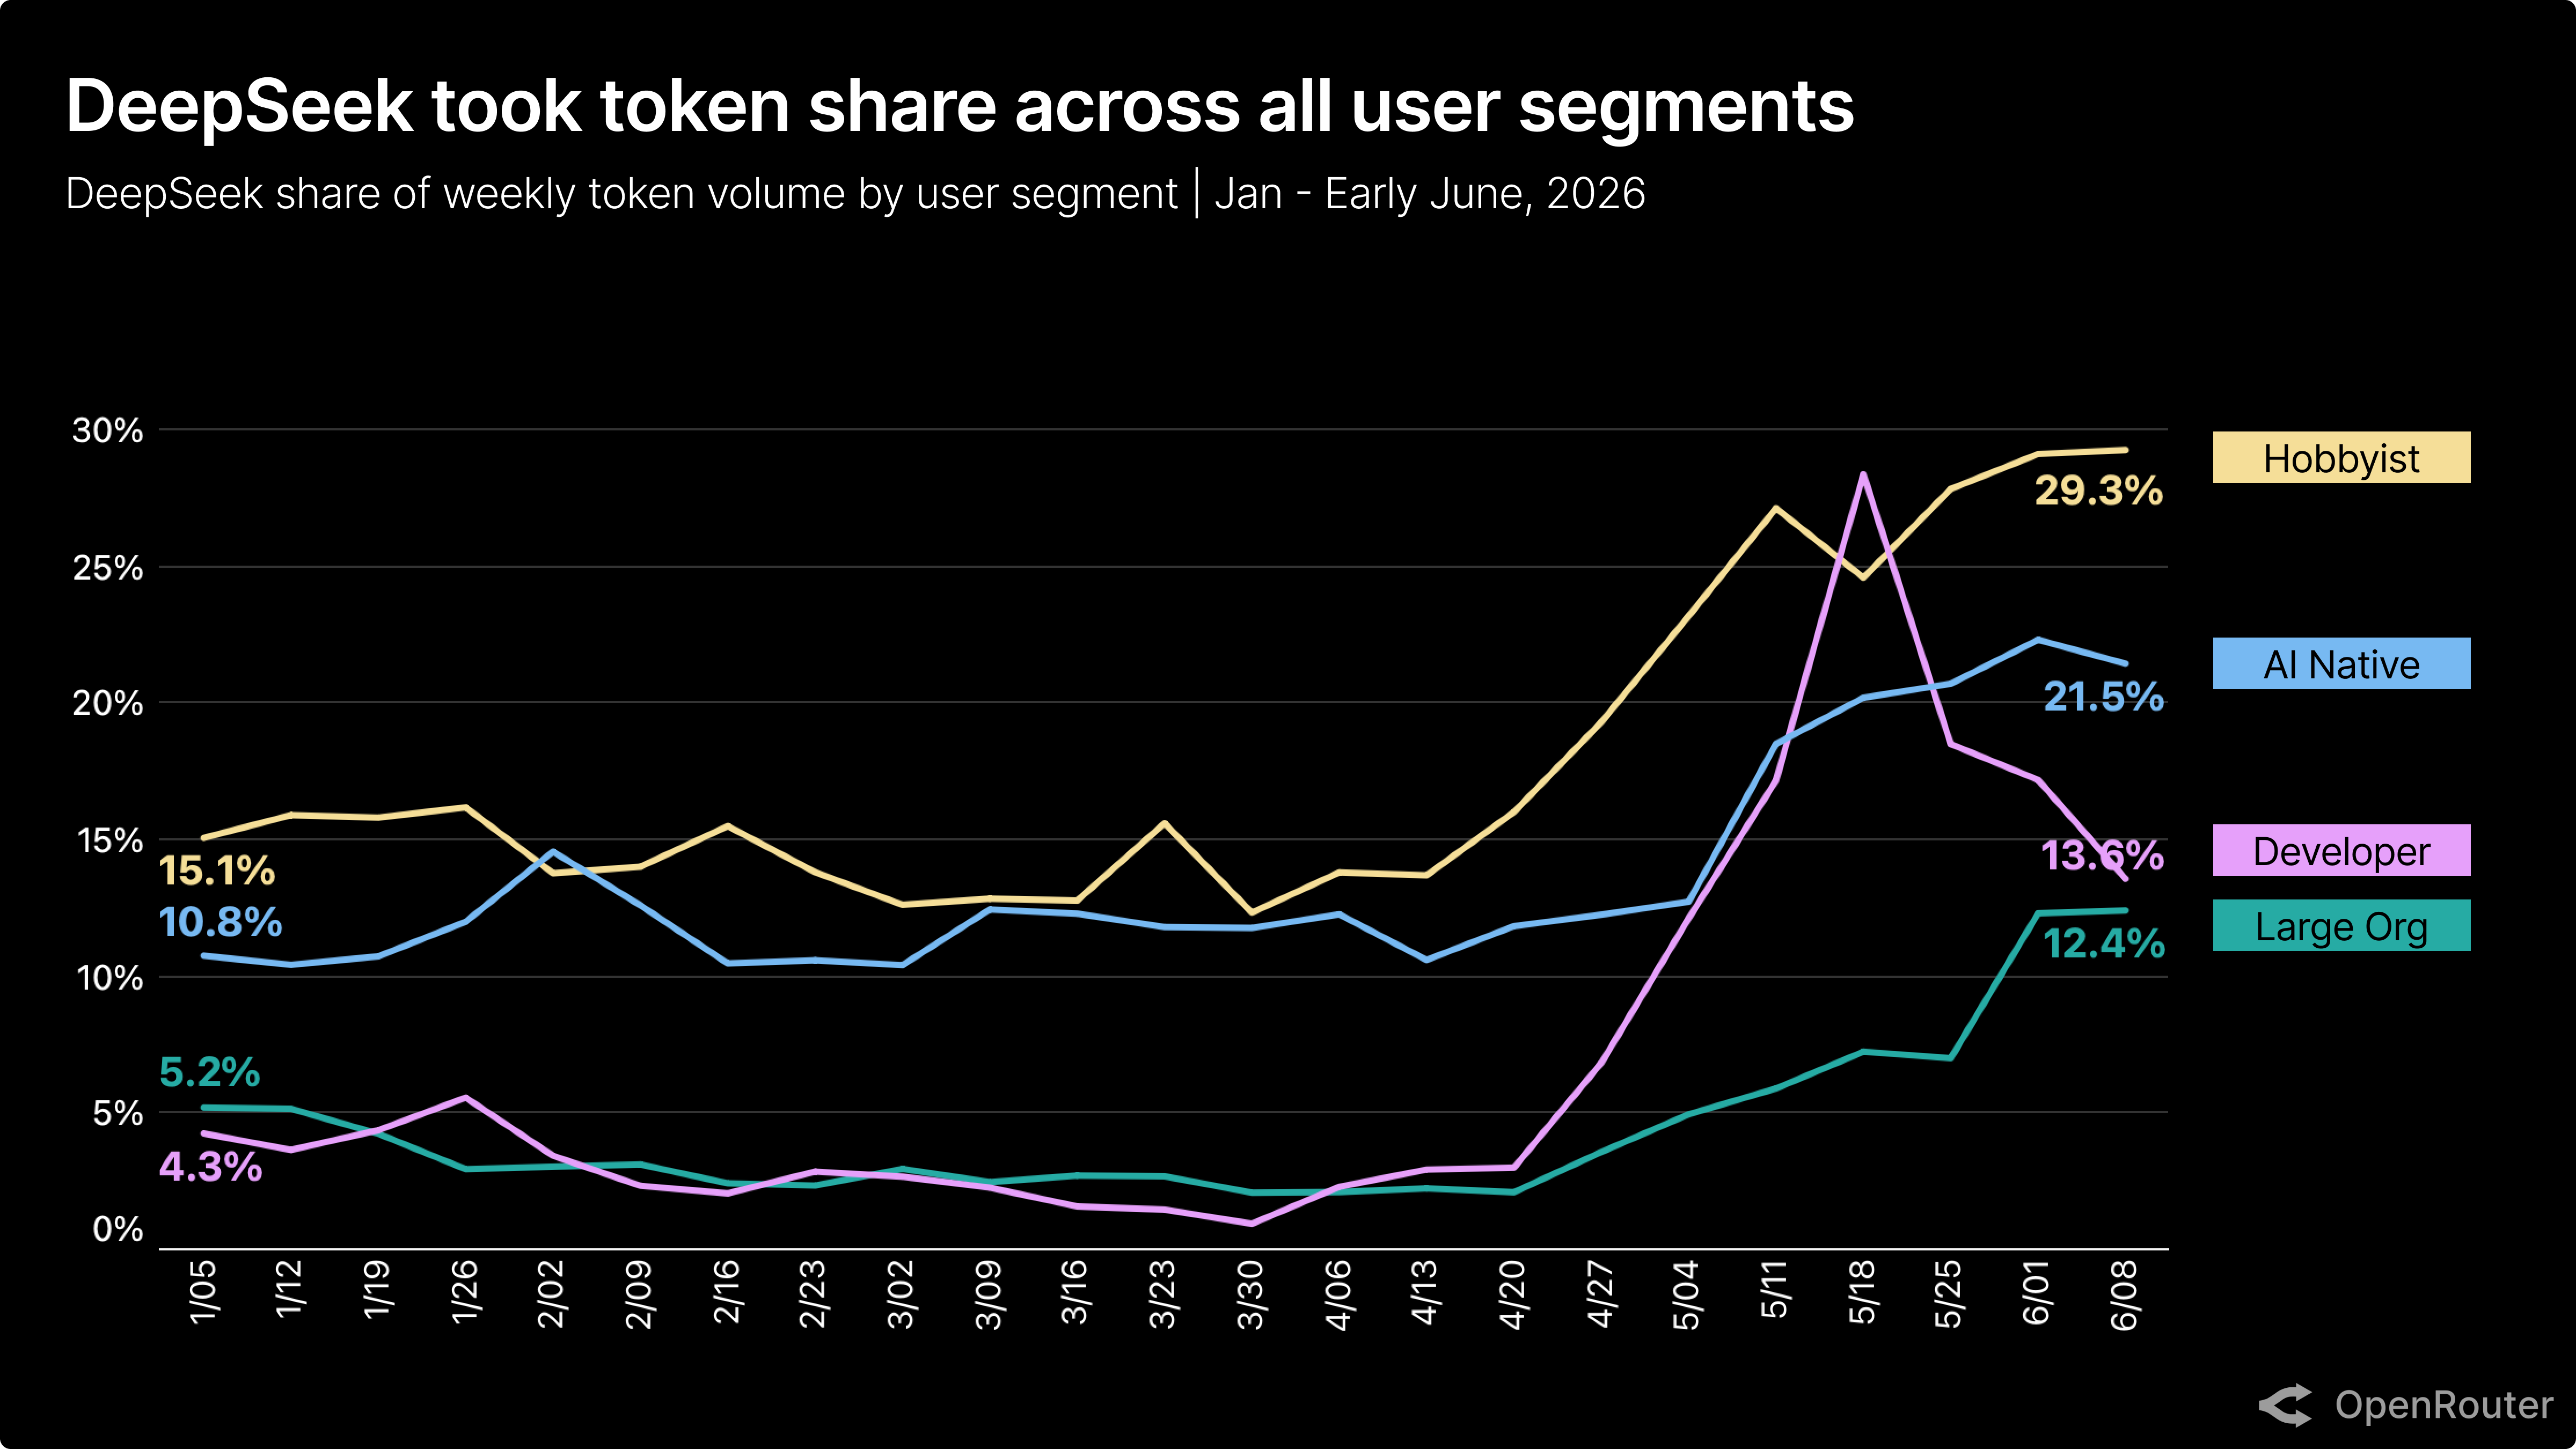
The DeepSeek doubling was not restricted to a single user type. Companies and individuals of all stripes were using more and more DeepSeek tokens by the start of June. Hobbyist users (who typically have significant usage through consumer-oriented app categories like roleplay, general chat, personal agents, etc) now route nearly a third of all their tokens to DeepSeek models.
Even amongst users at AI native companies or large organizations, both of whom may have been expected to prioritize frontier closed models, sent DeepSeek much more token traffic in early June than they did to start the year.
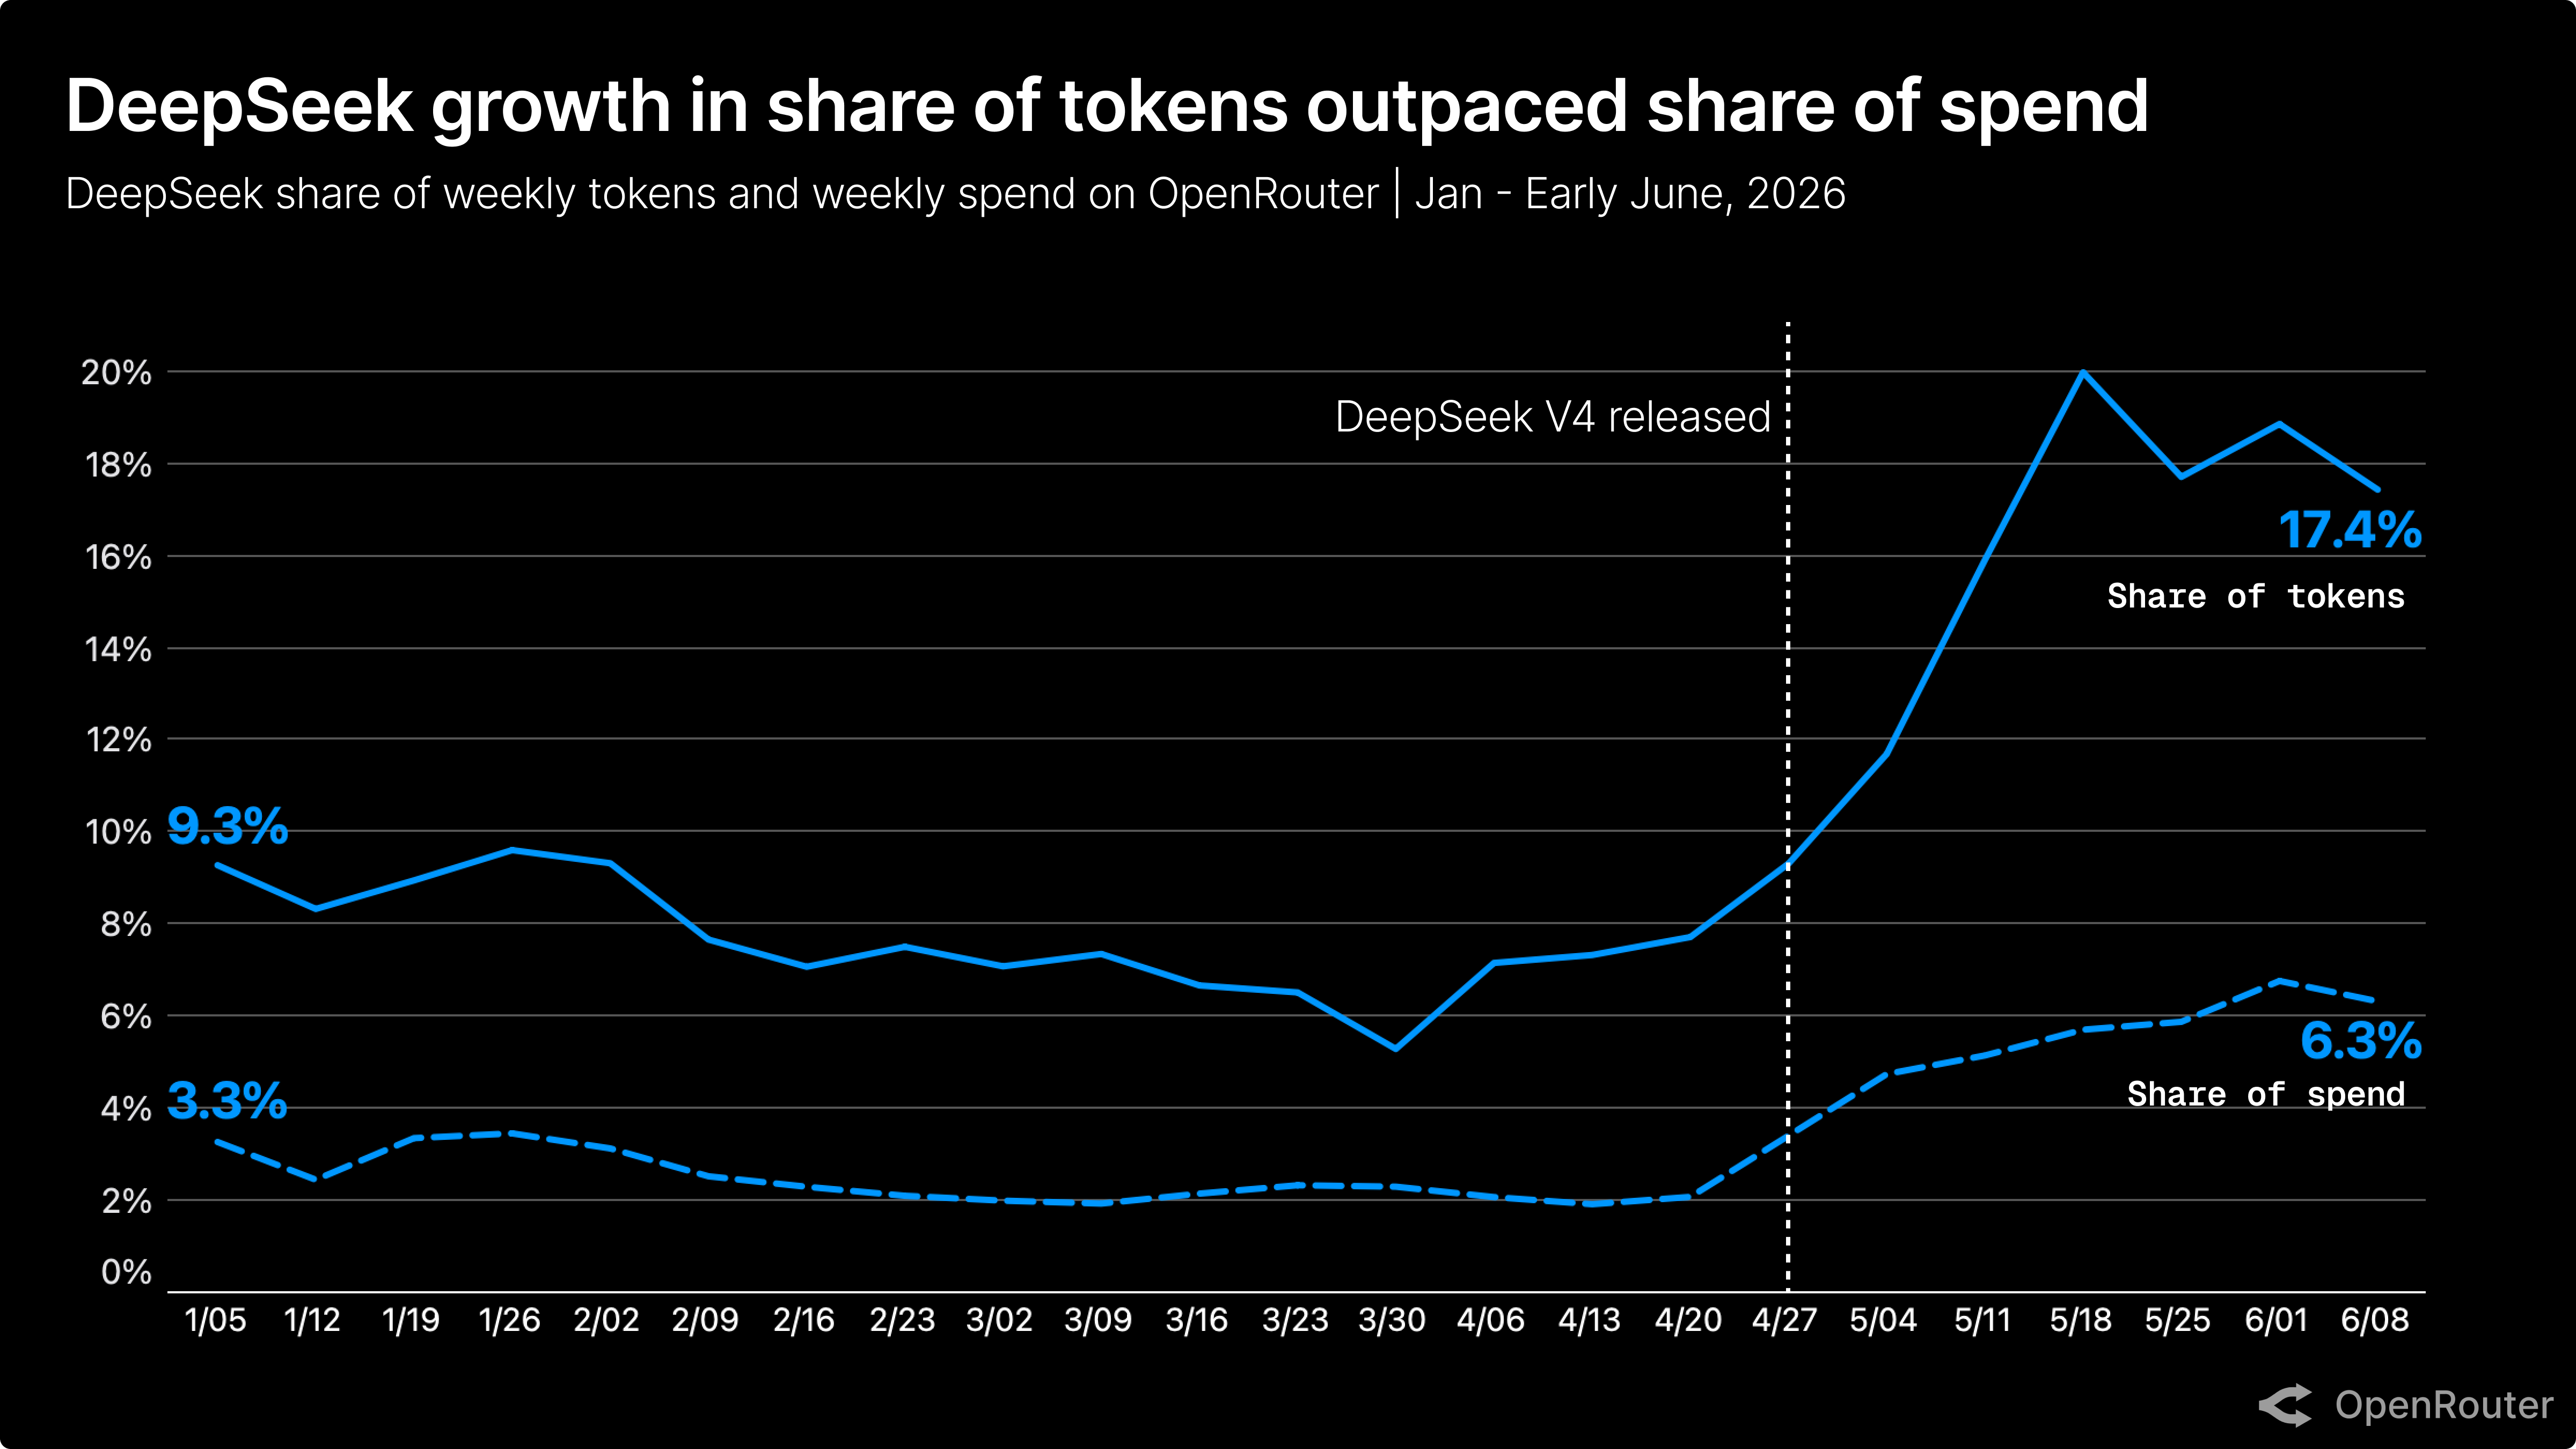
DeepSeek V4 Flash, on the cheapest endpoint, costs $0.09 input / $0.18 output per million tokens. For comparison, GPT-5.5 is currently priced at $5 input / $30 output per million tokens.
So it’s not a shock to see this sudden upsurge in token volume for V4 has not resulted in an identical spike in share of spend. The cost effectiveness to output quality ratio for V4 is best in class - it is good enough, in fact, that organizations of all sizes have begun trusting DeepSeek with real agentic work.
V4 is the first DeepSeek model sufficient for agentic workloads
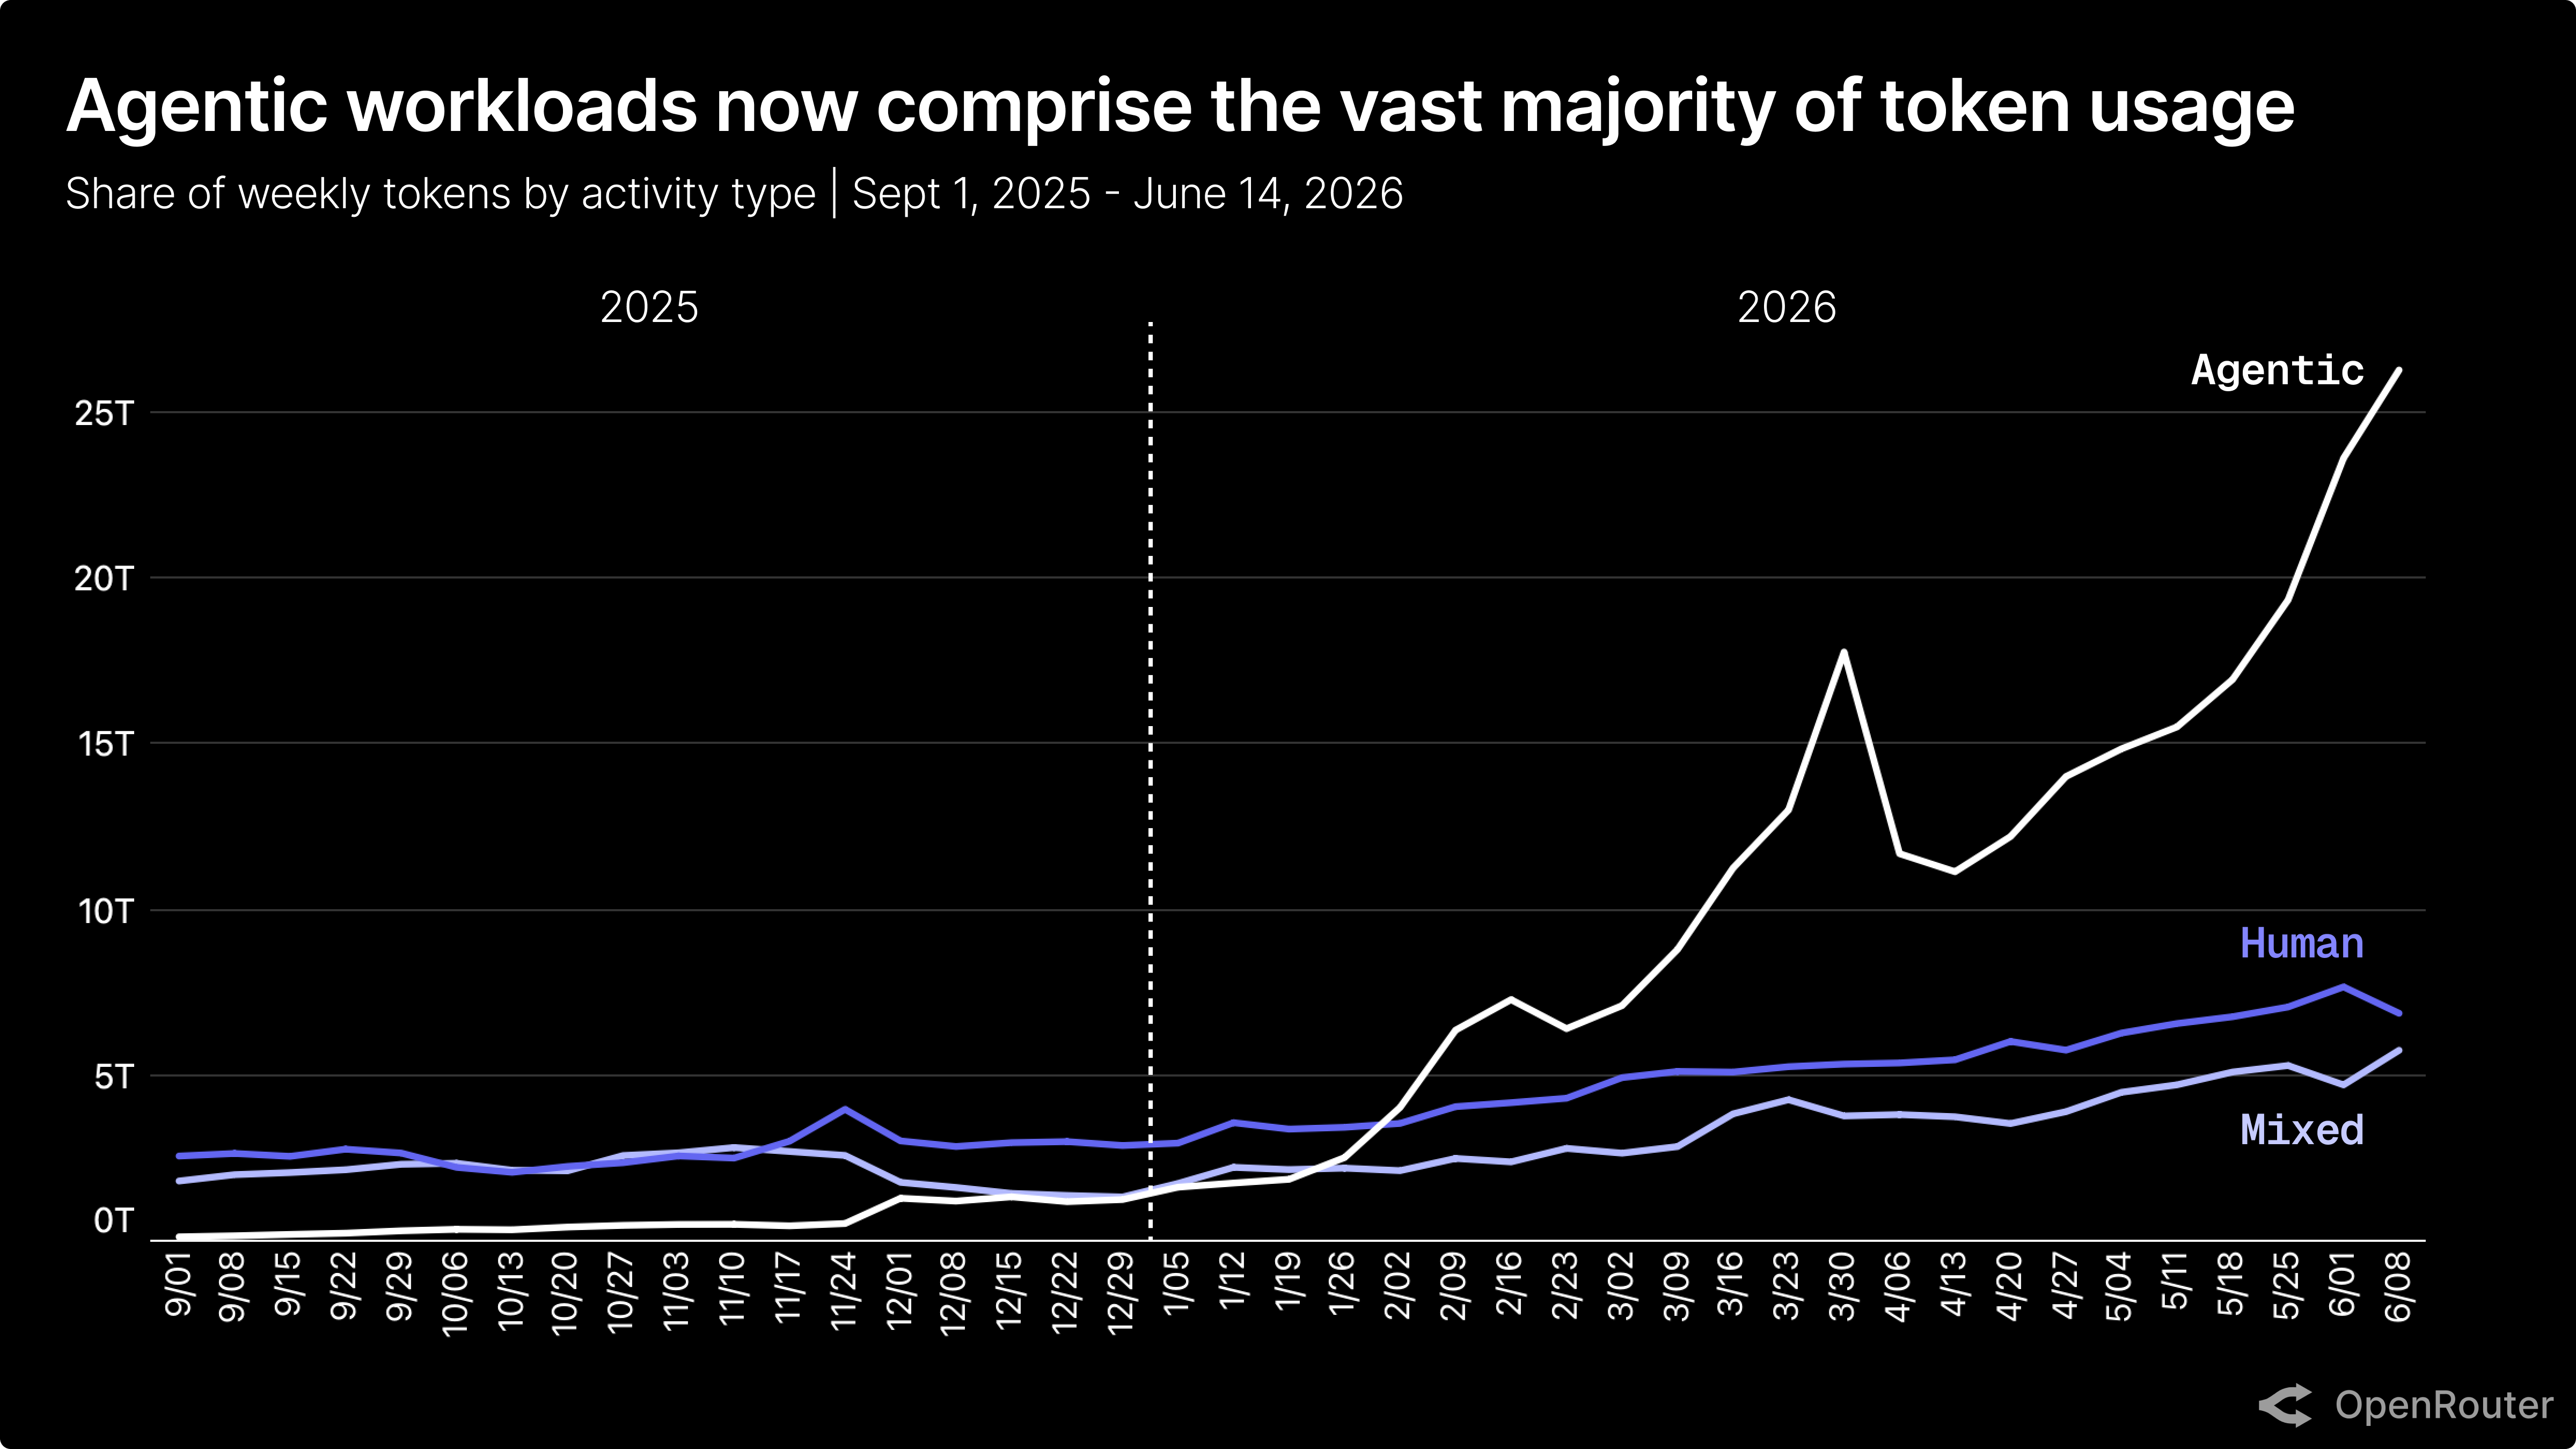
We segment token traffic at the API key level into three main categories (Agentic, Mixed, and Human). These are assigned according to a 7-signal weighted composite score that includes inputs such as tool call rate, turn count, gap timing, and others.
Everyone knows that agentic work burns more tokens than normal human AI usage (about 15x more per request, according to OpenRouter data). But it bears remembering that this explosion in agentic tokens is a 2026 phenomenon and really didn’t kick off in earnest until early February of this year.
Except even that is an overstatement for some model authors.
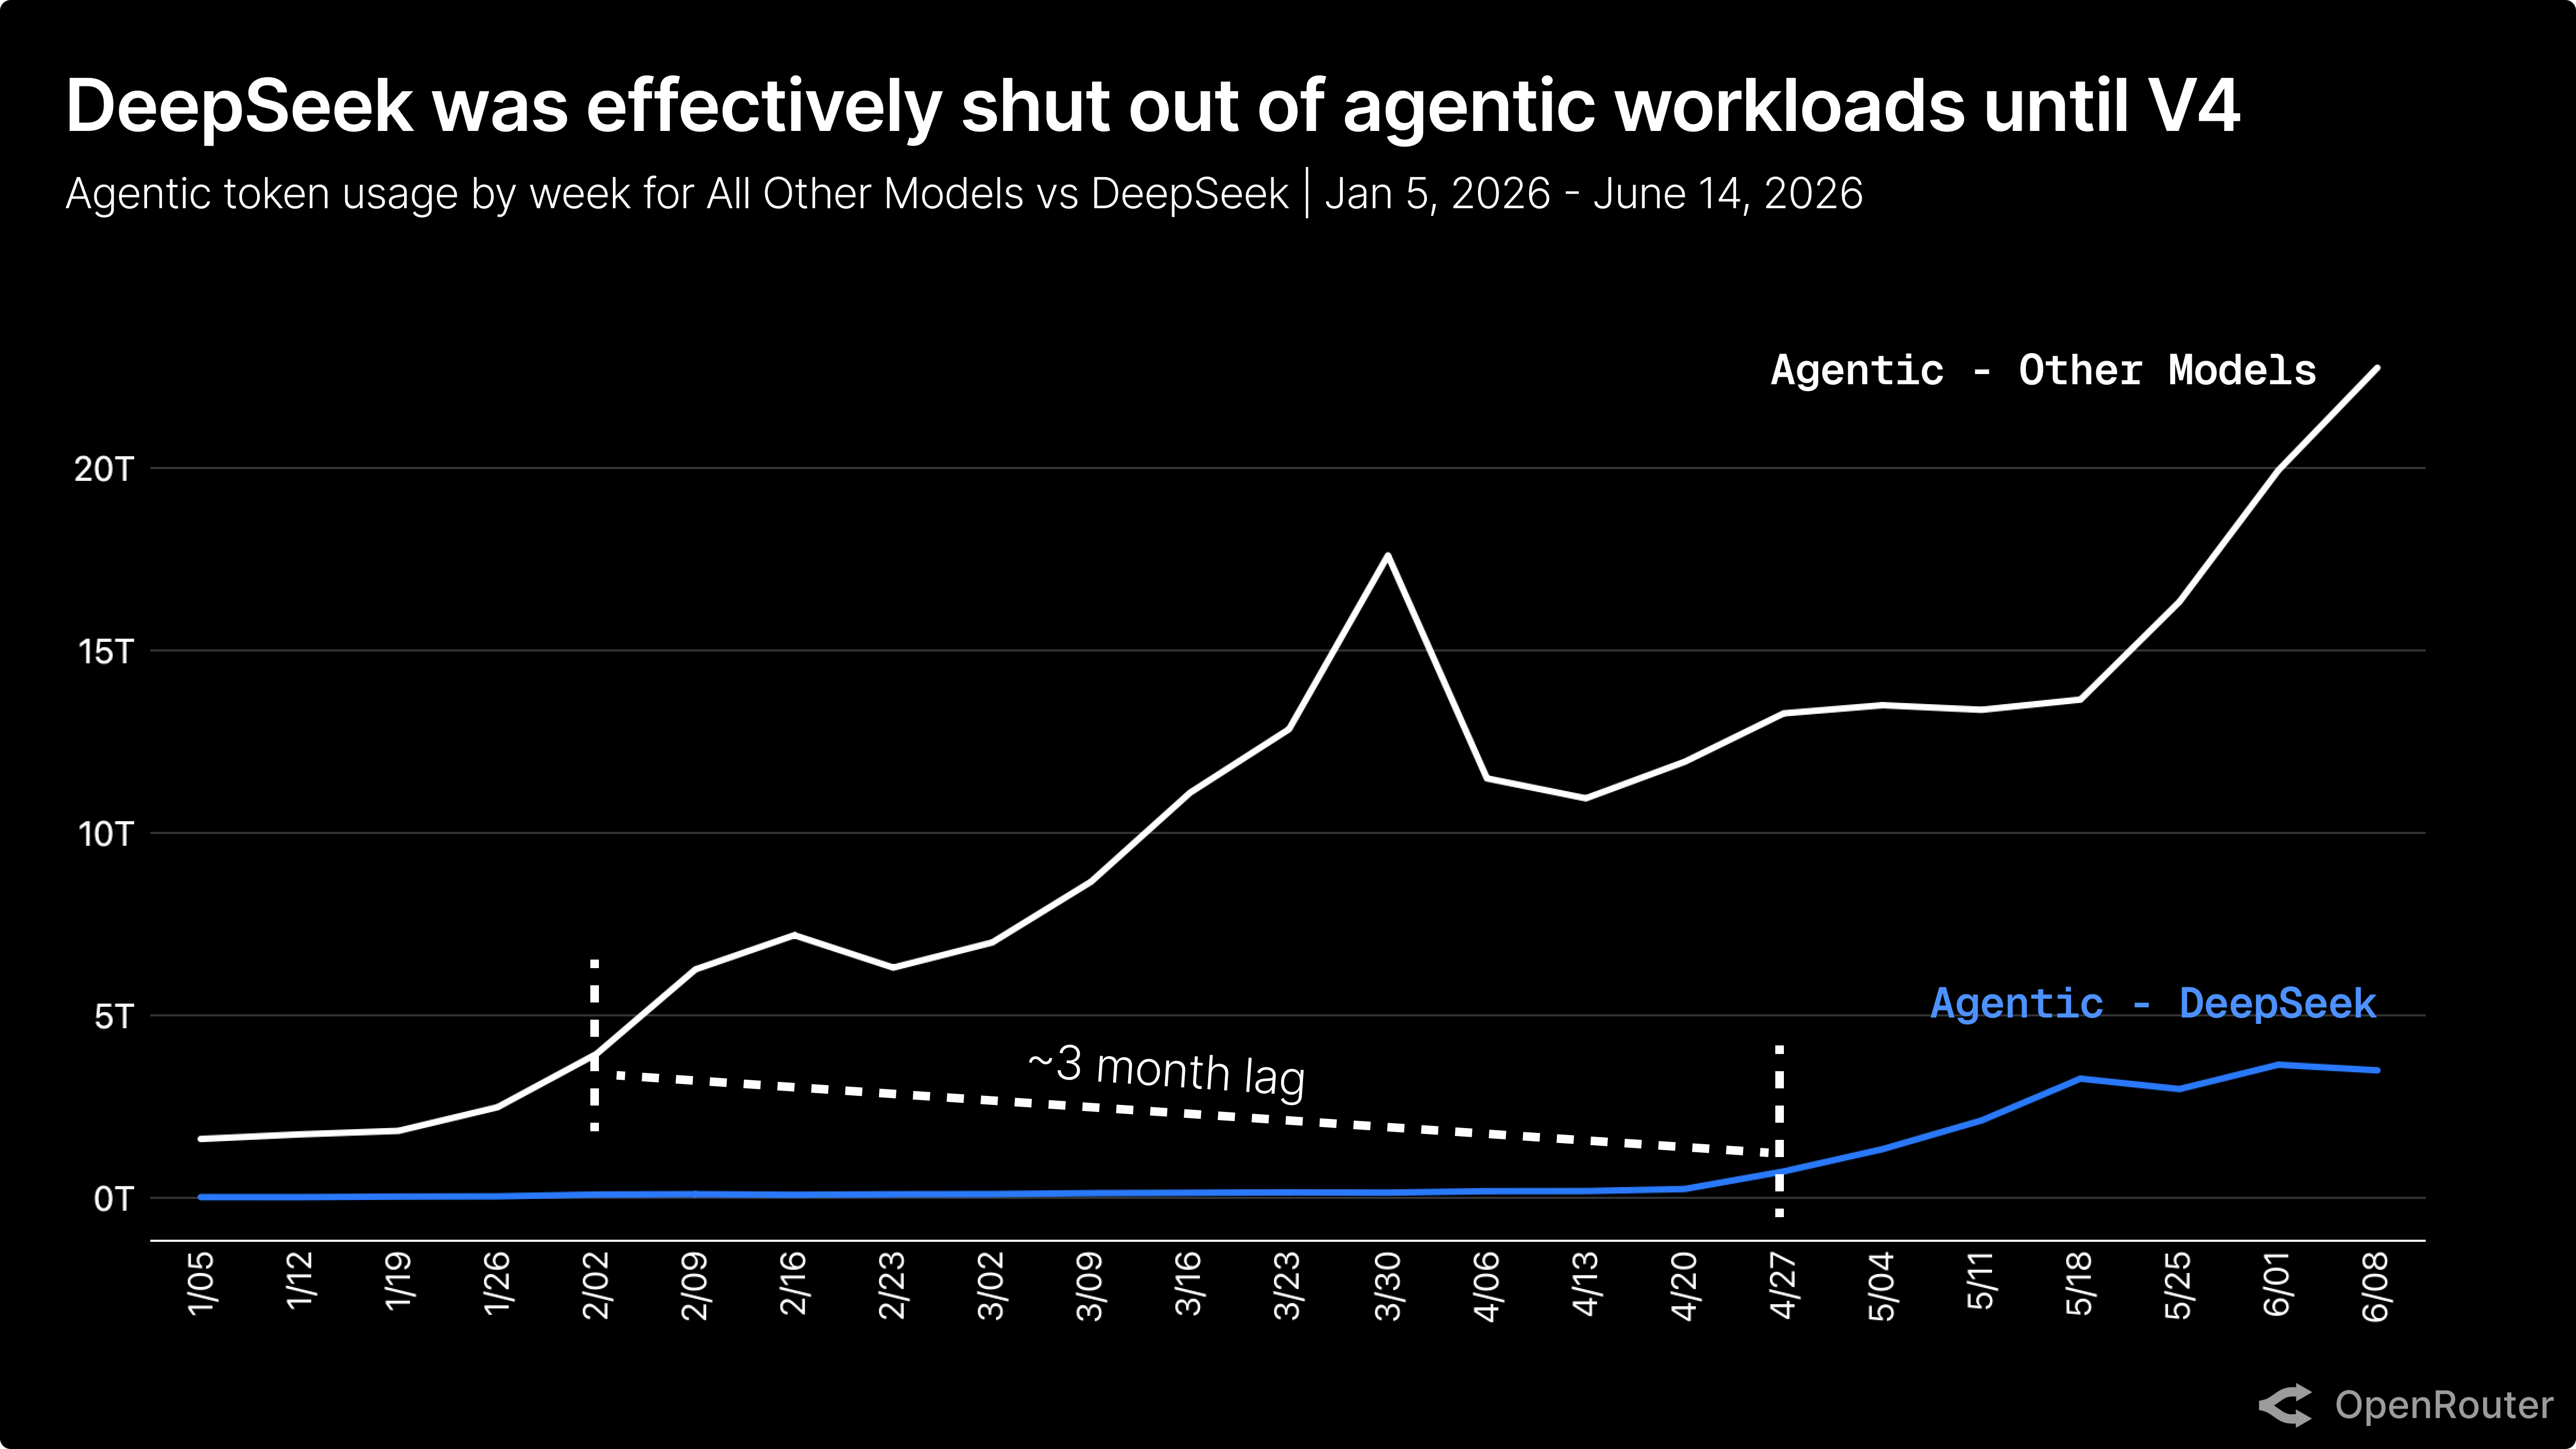
The tokens used by agentic workloads surpassed those used by humans right around February 1st. At first, agentic work was concentrated in only a few model authors and that select group did not include DeepSeek.
The release of V4 marked DeepSeek’s entrance into the agentic workflow race in earnest.
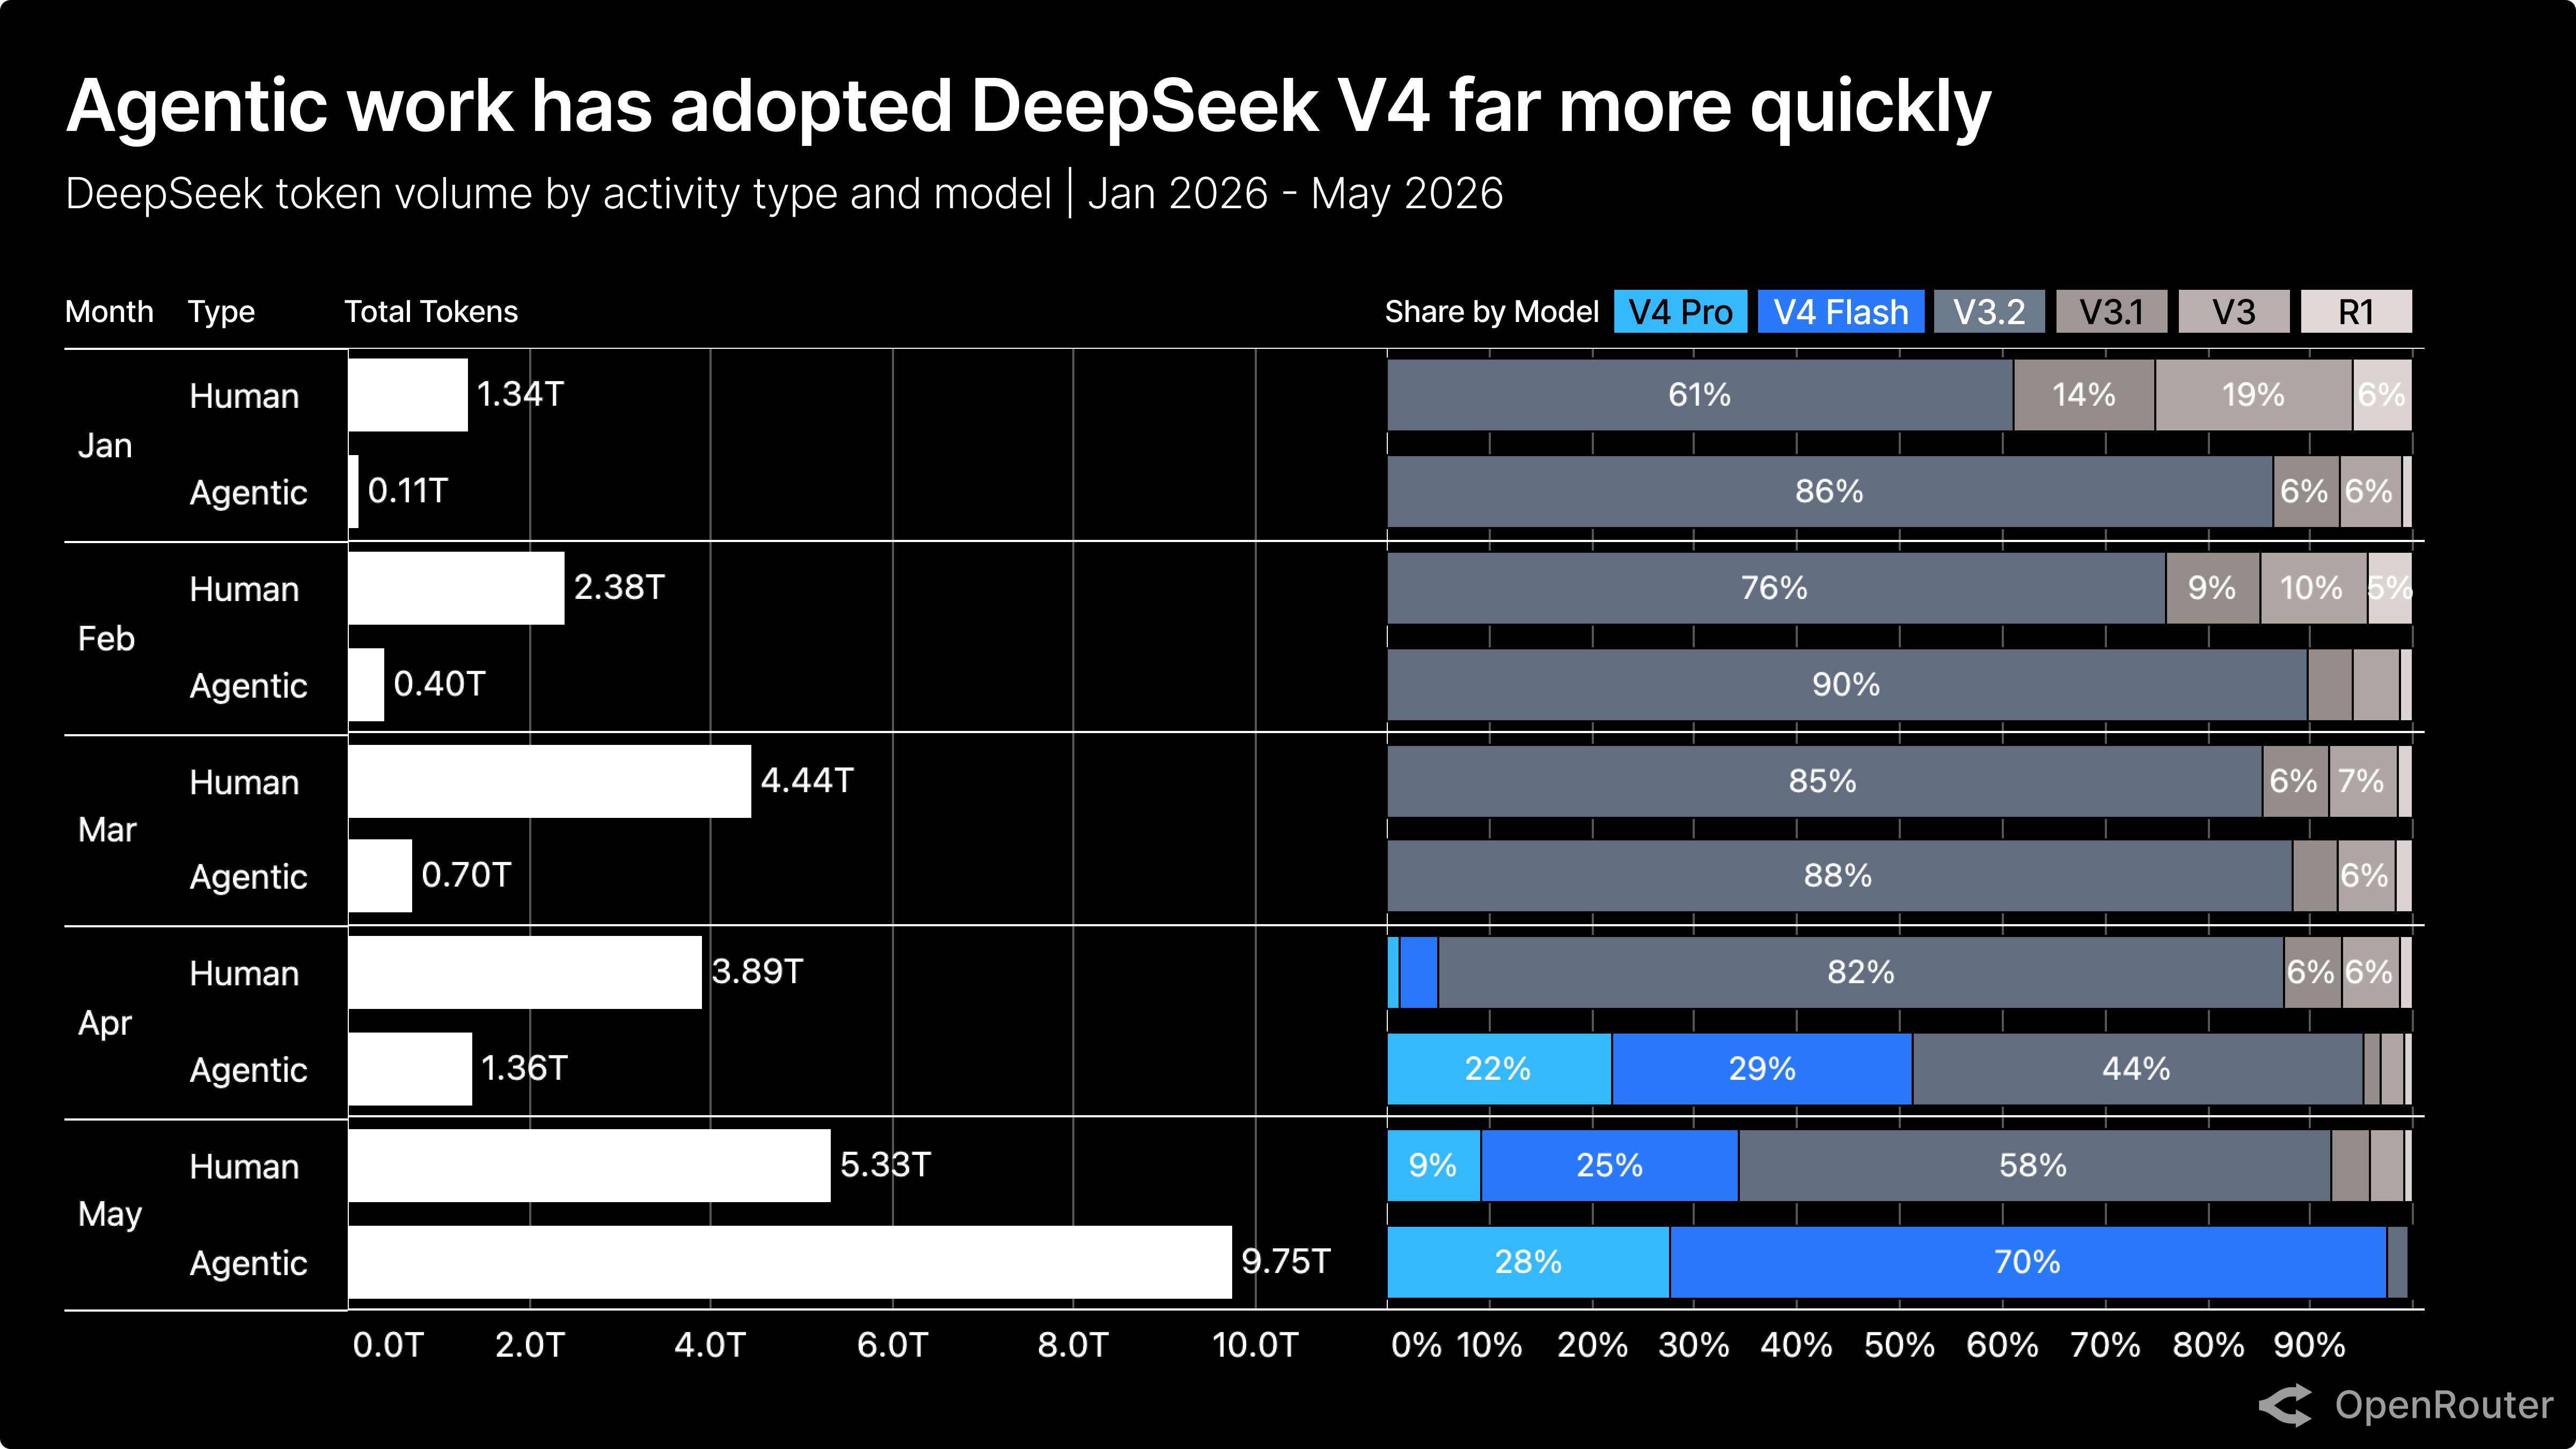
Not all workloads switch to the latest model at the same time. The chart above illustrates how human activity within DeepSeek token usage has remained tied to DeepSeek V3.2 through the first 5 months of the year.
Agentic workloads, however, have made V4 their model of choice. By the end of May, a mere month after release, V4-Flash comprised 70% of agentic token flow for DeepSeek usage.
DeepSeek and the rise of Chinese models
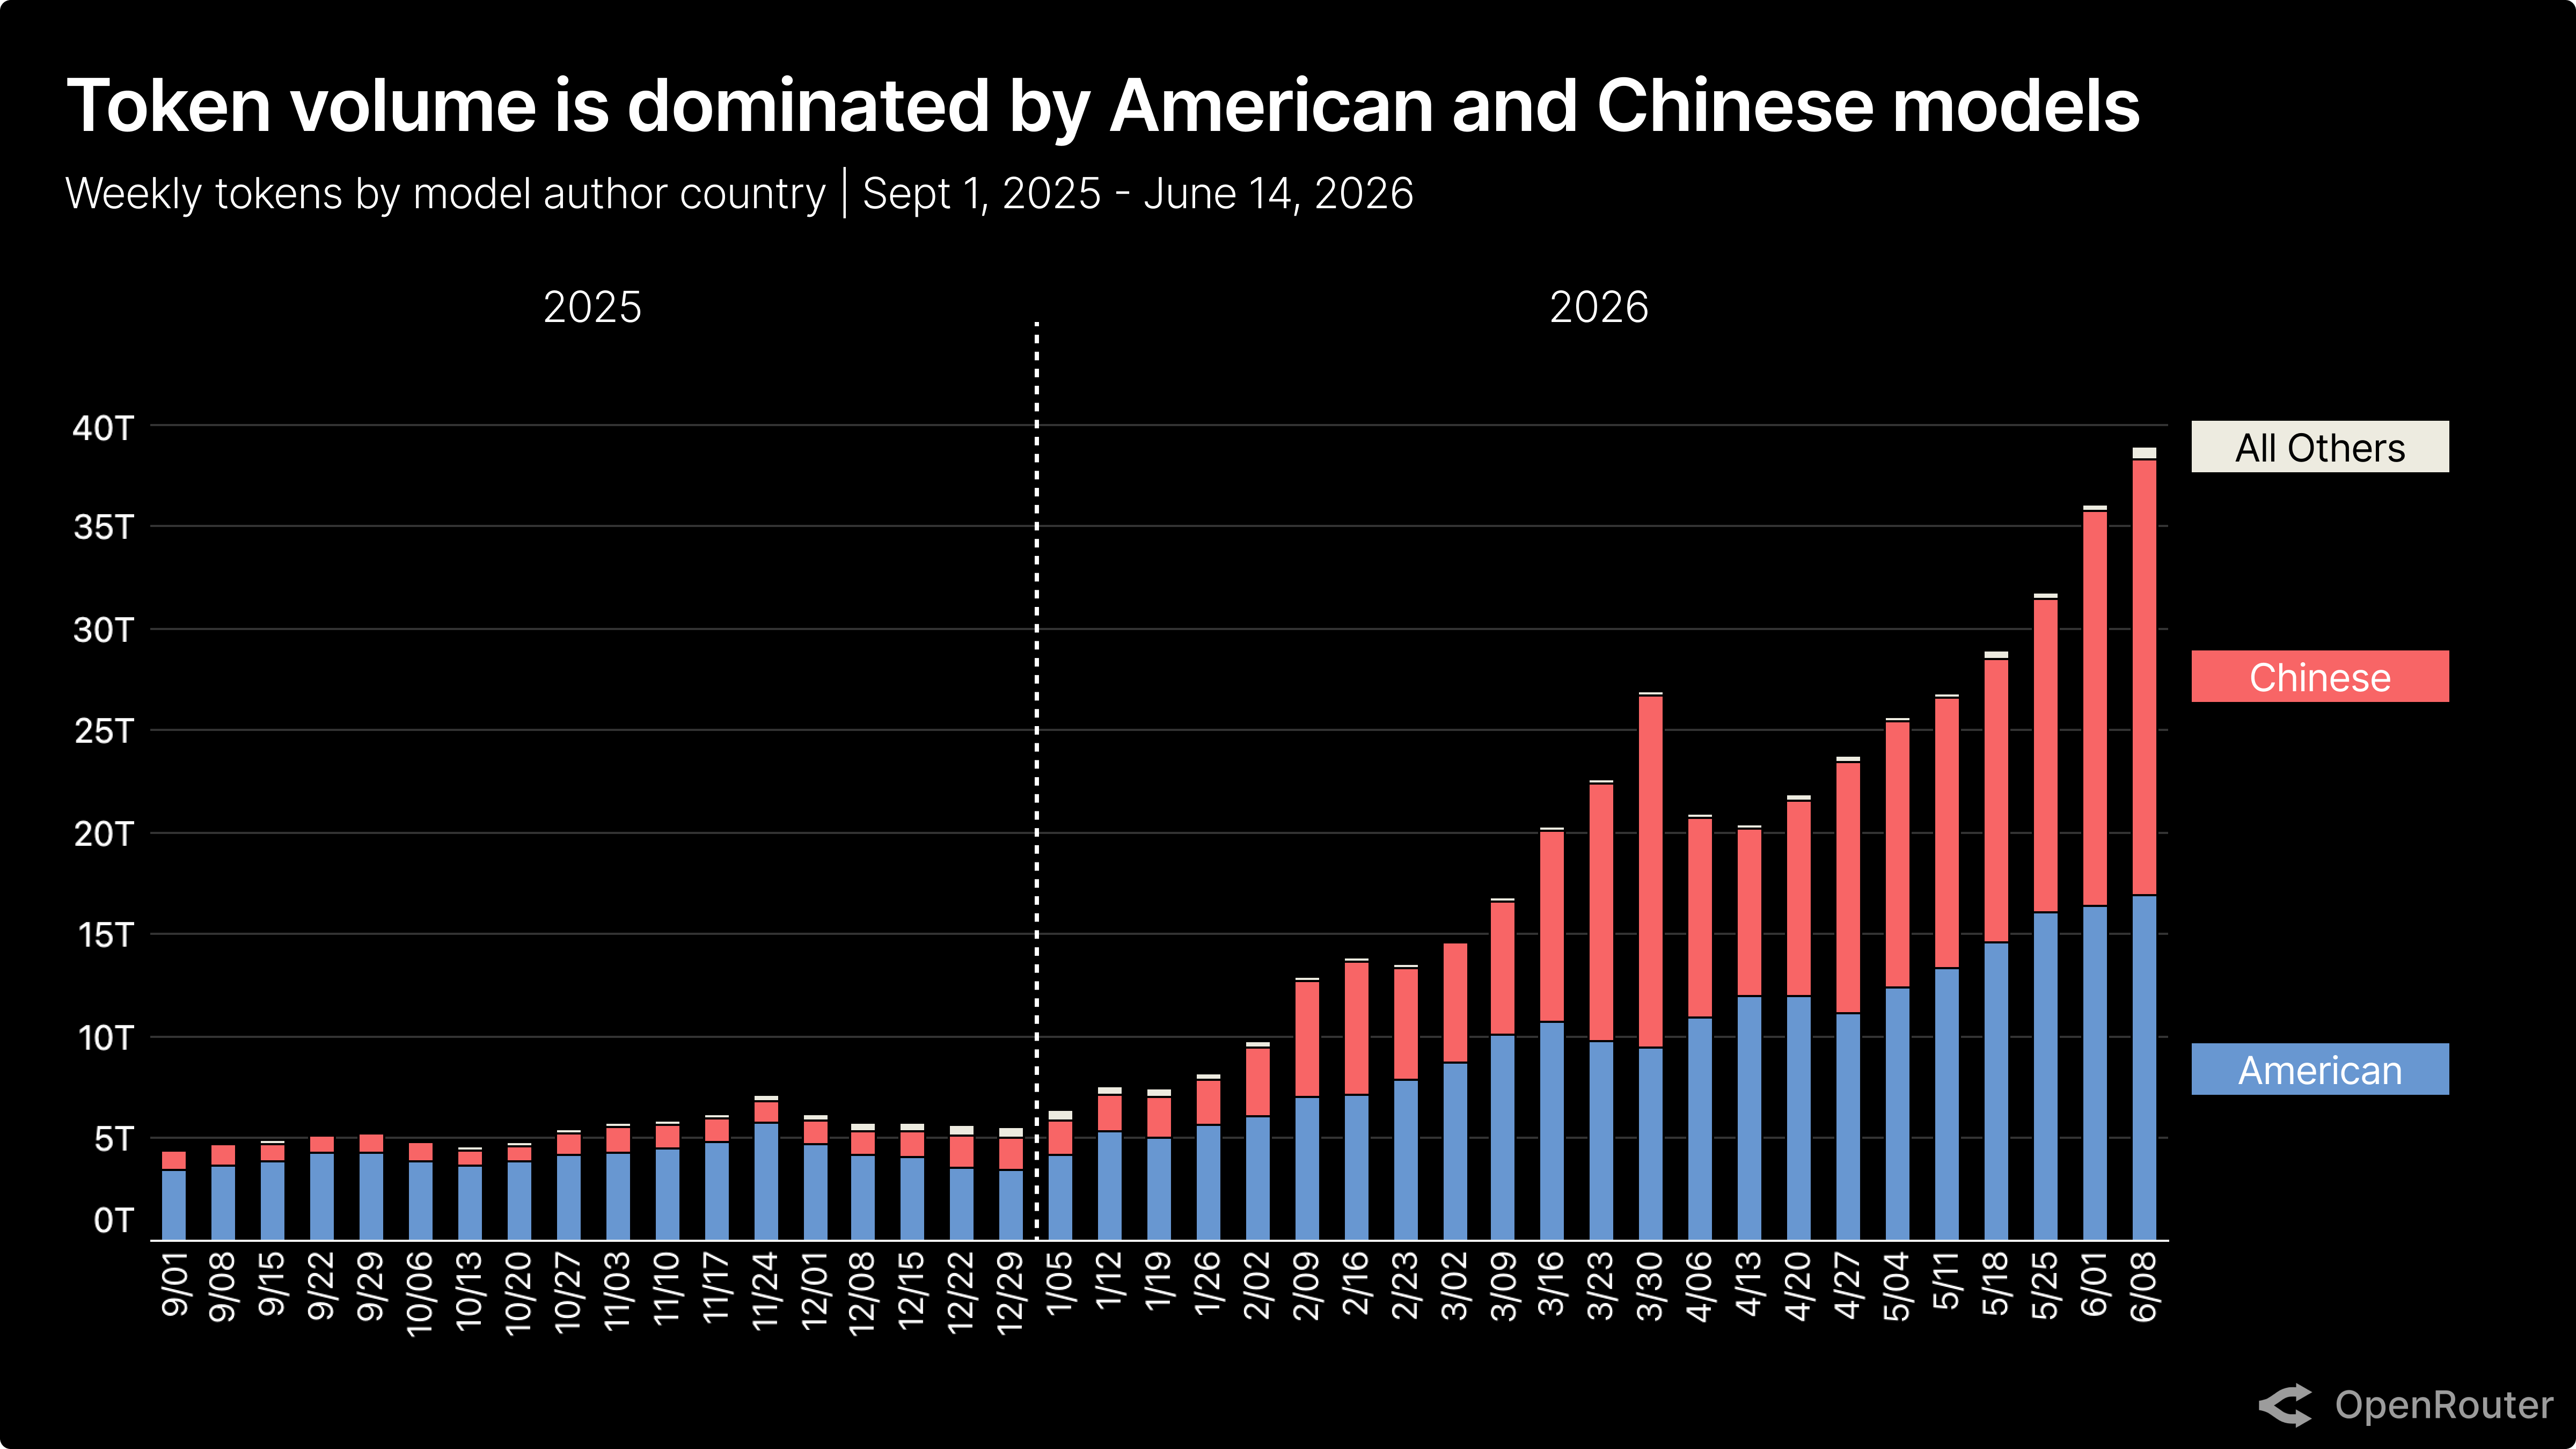
Tokens flow to the LLMs created in two countries: America and China (with a tiny smattering of others represented in the small beige slice). Token volume has exploded in 2026 but the growth has not spread to LLMs from other nations.
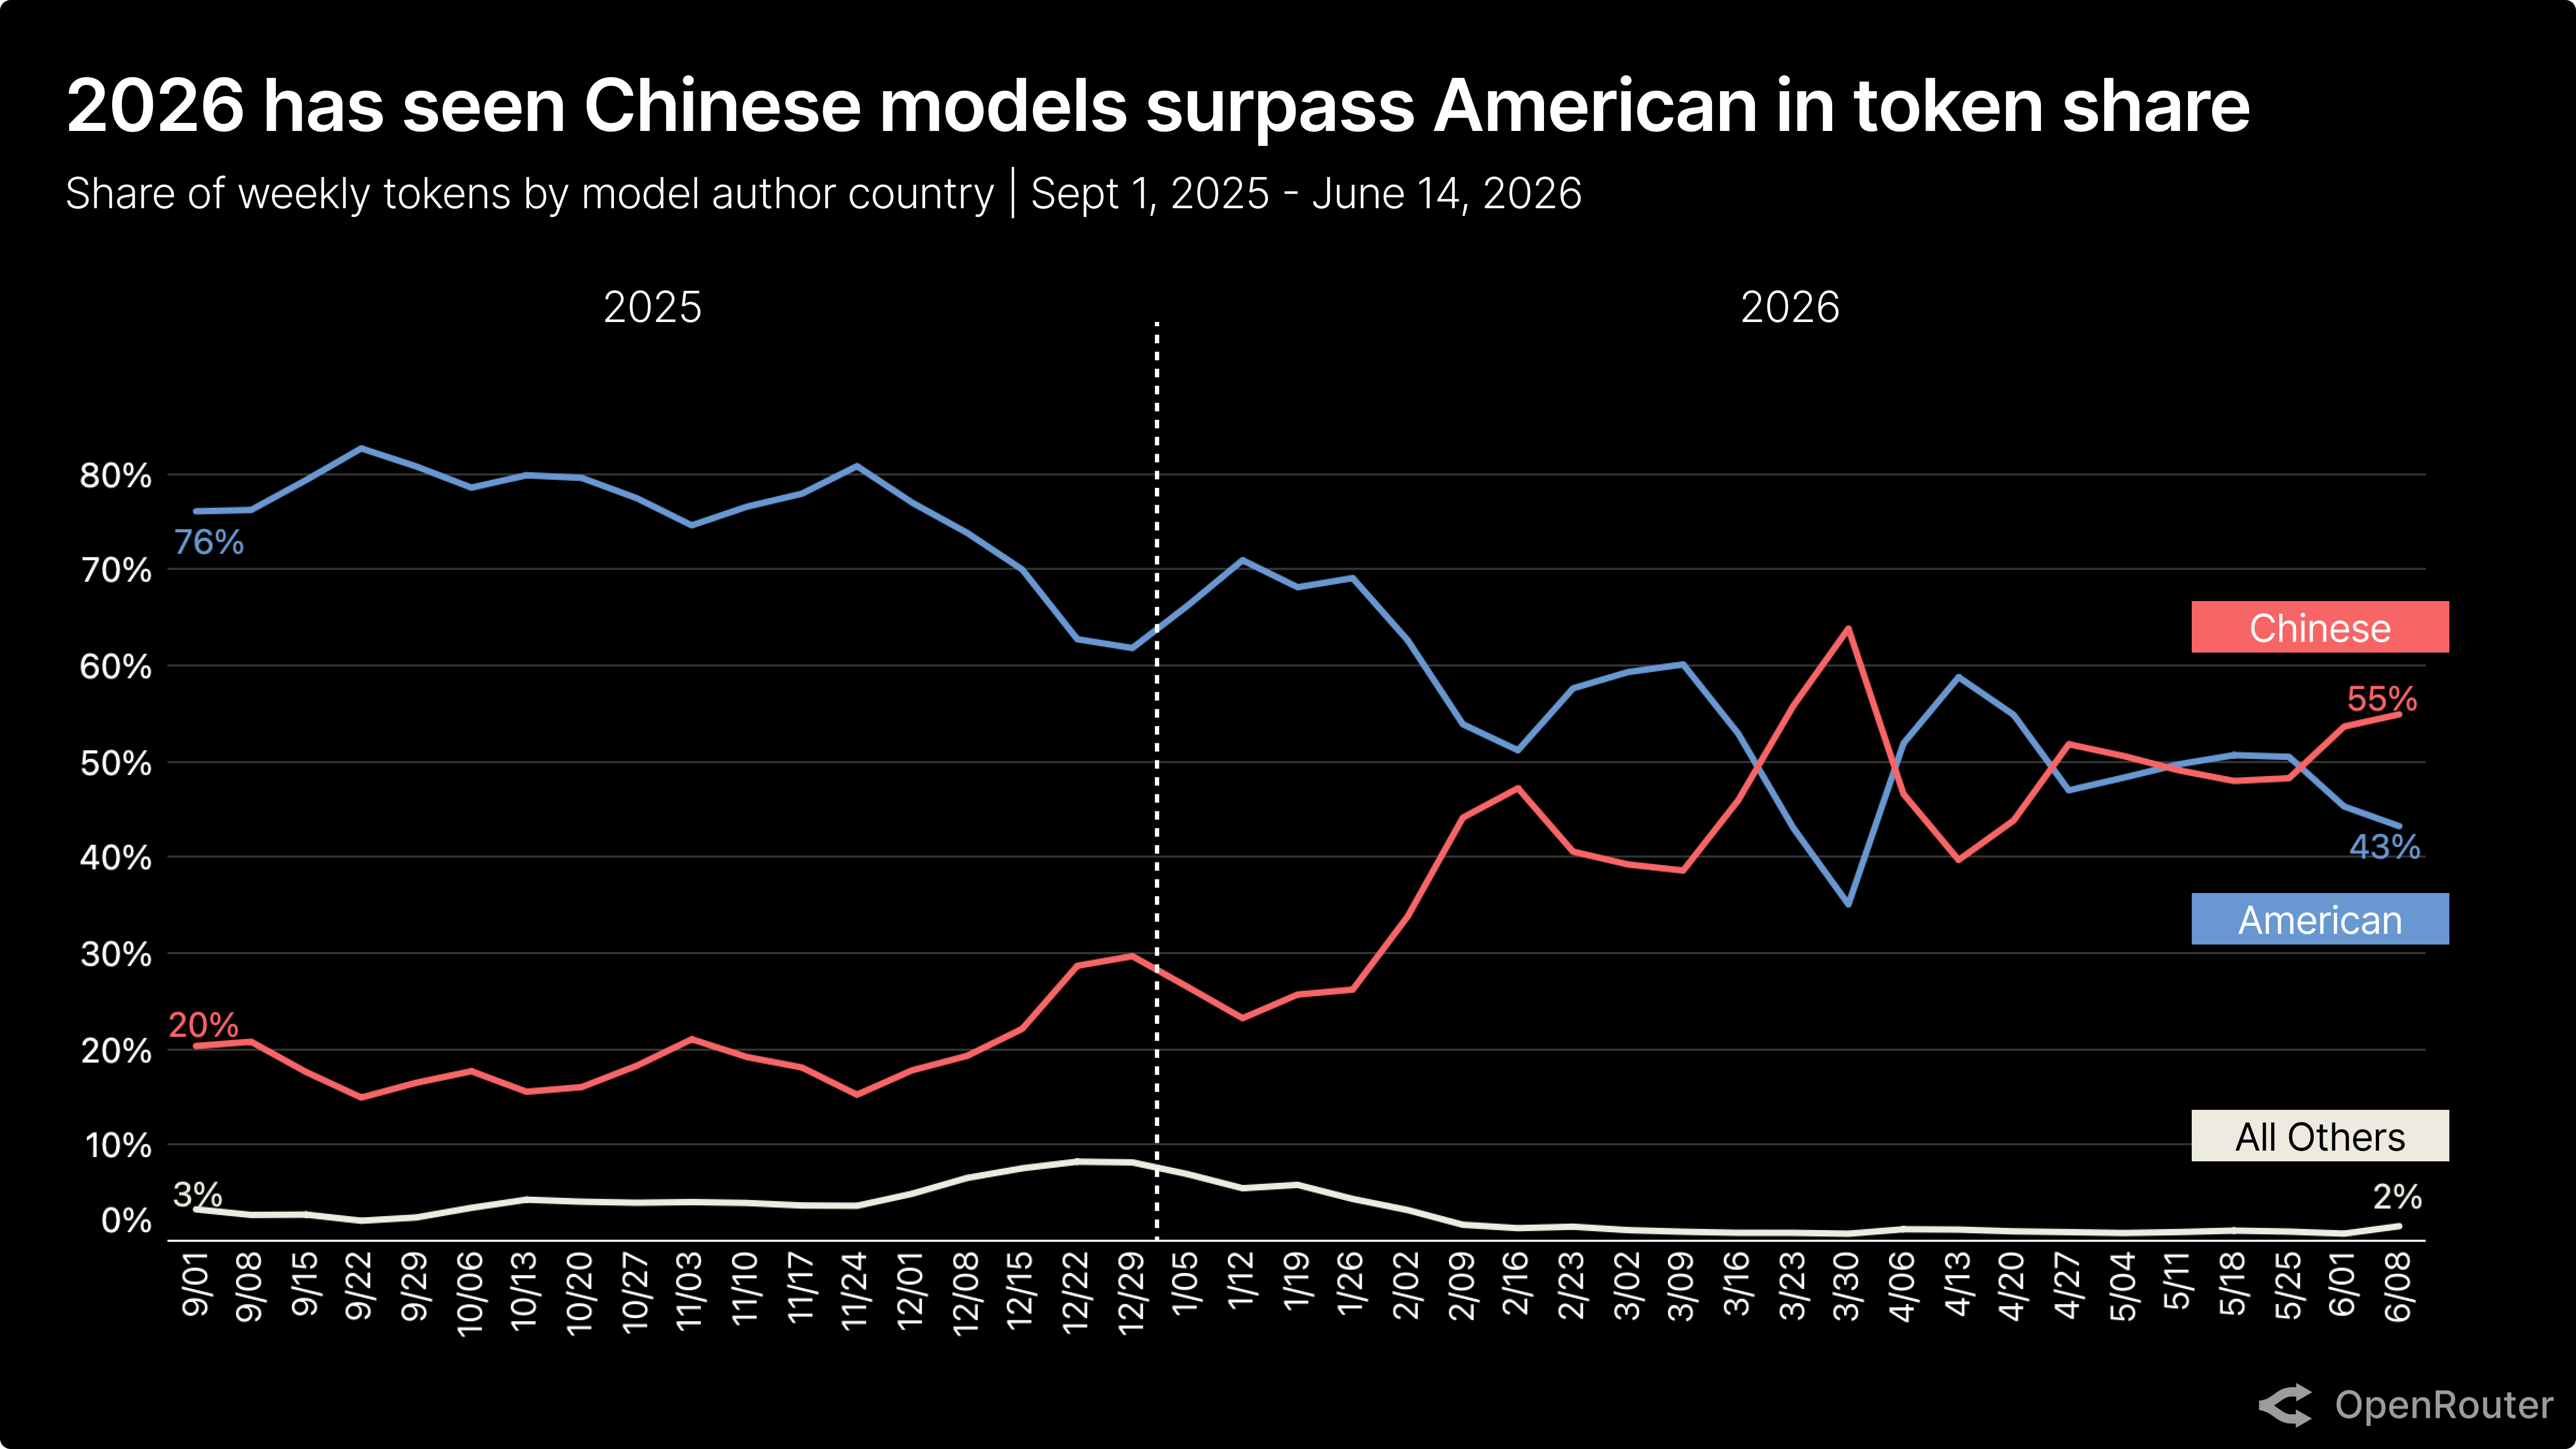
2025 was the year of American tokens, with models from the US responsible for about 3/4ths of the tokens used. The competition has been far more fierce in 2026, with Chinese models actually surpassing American ones in token share as of early June.
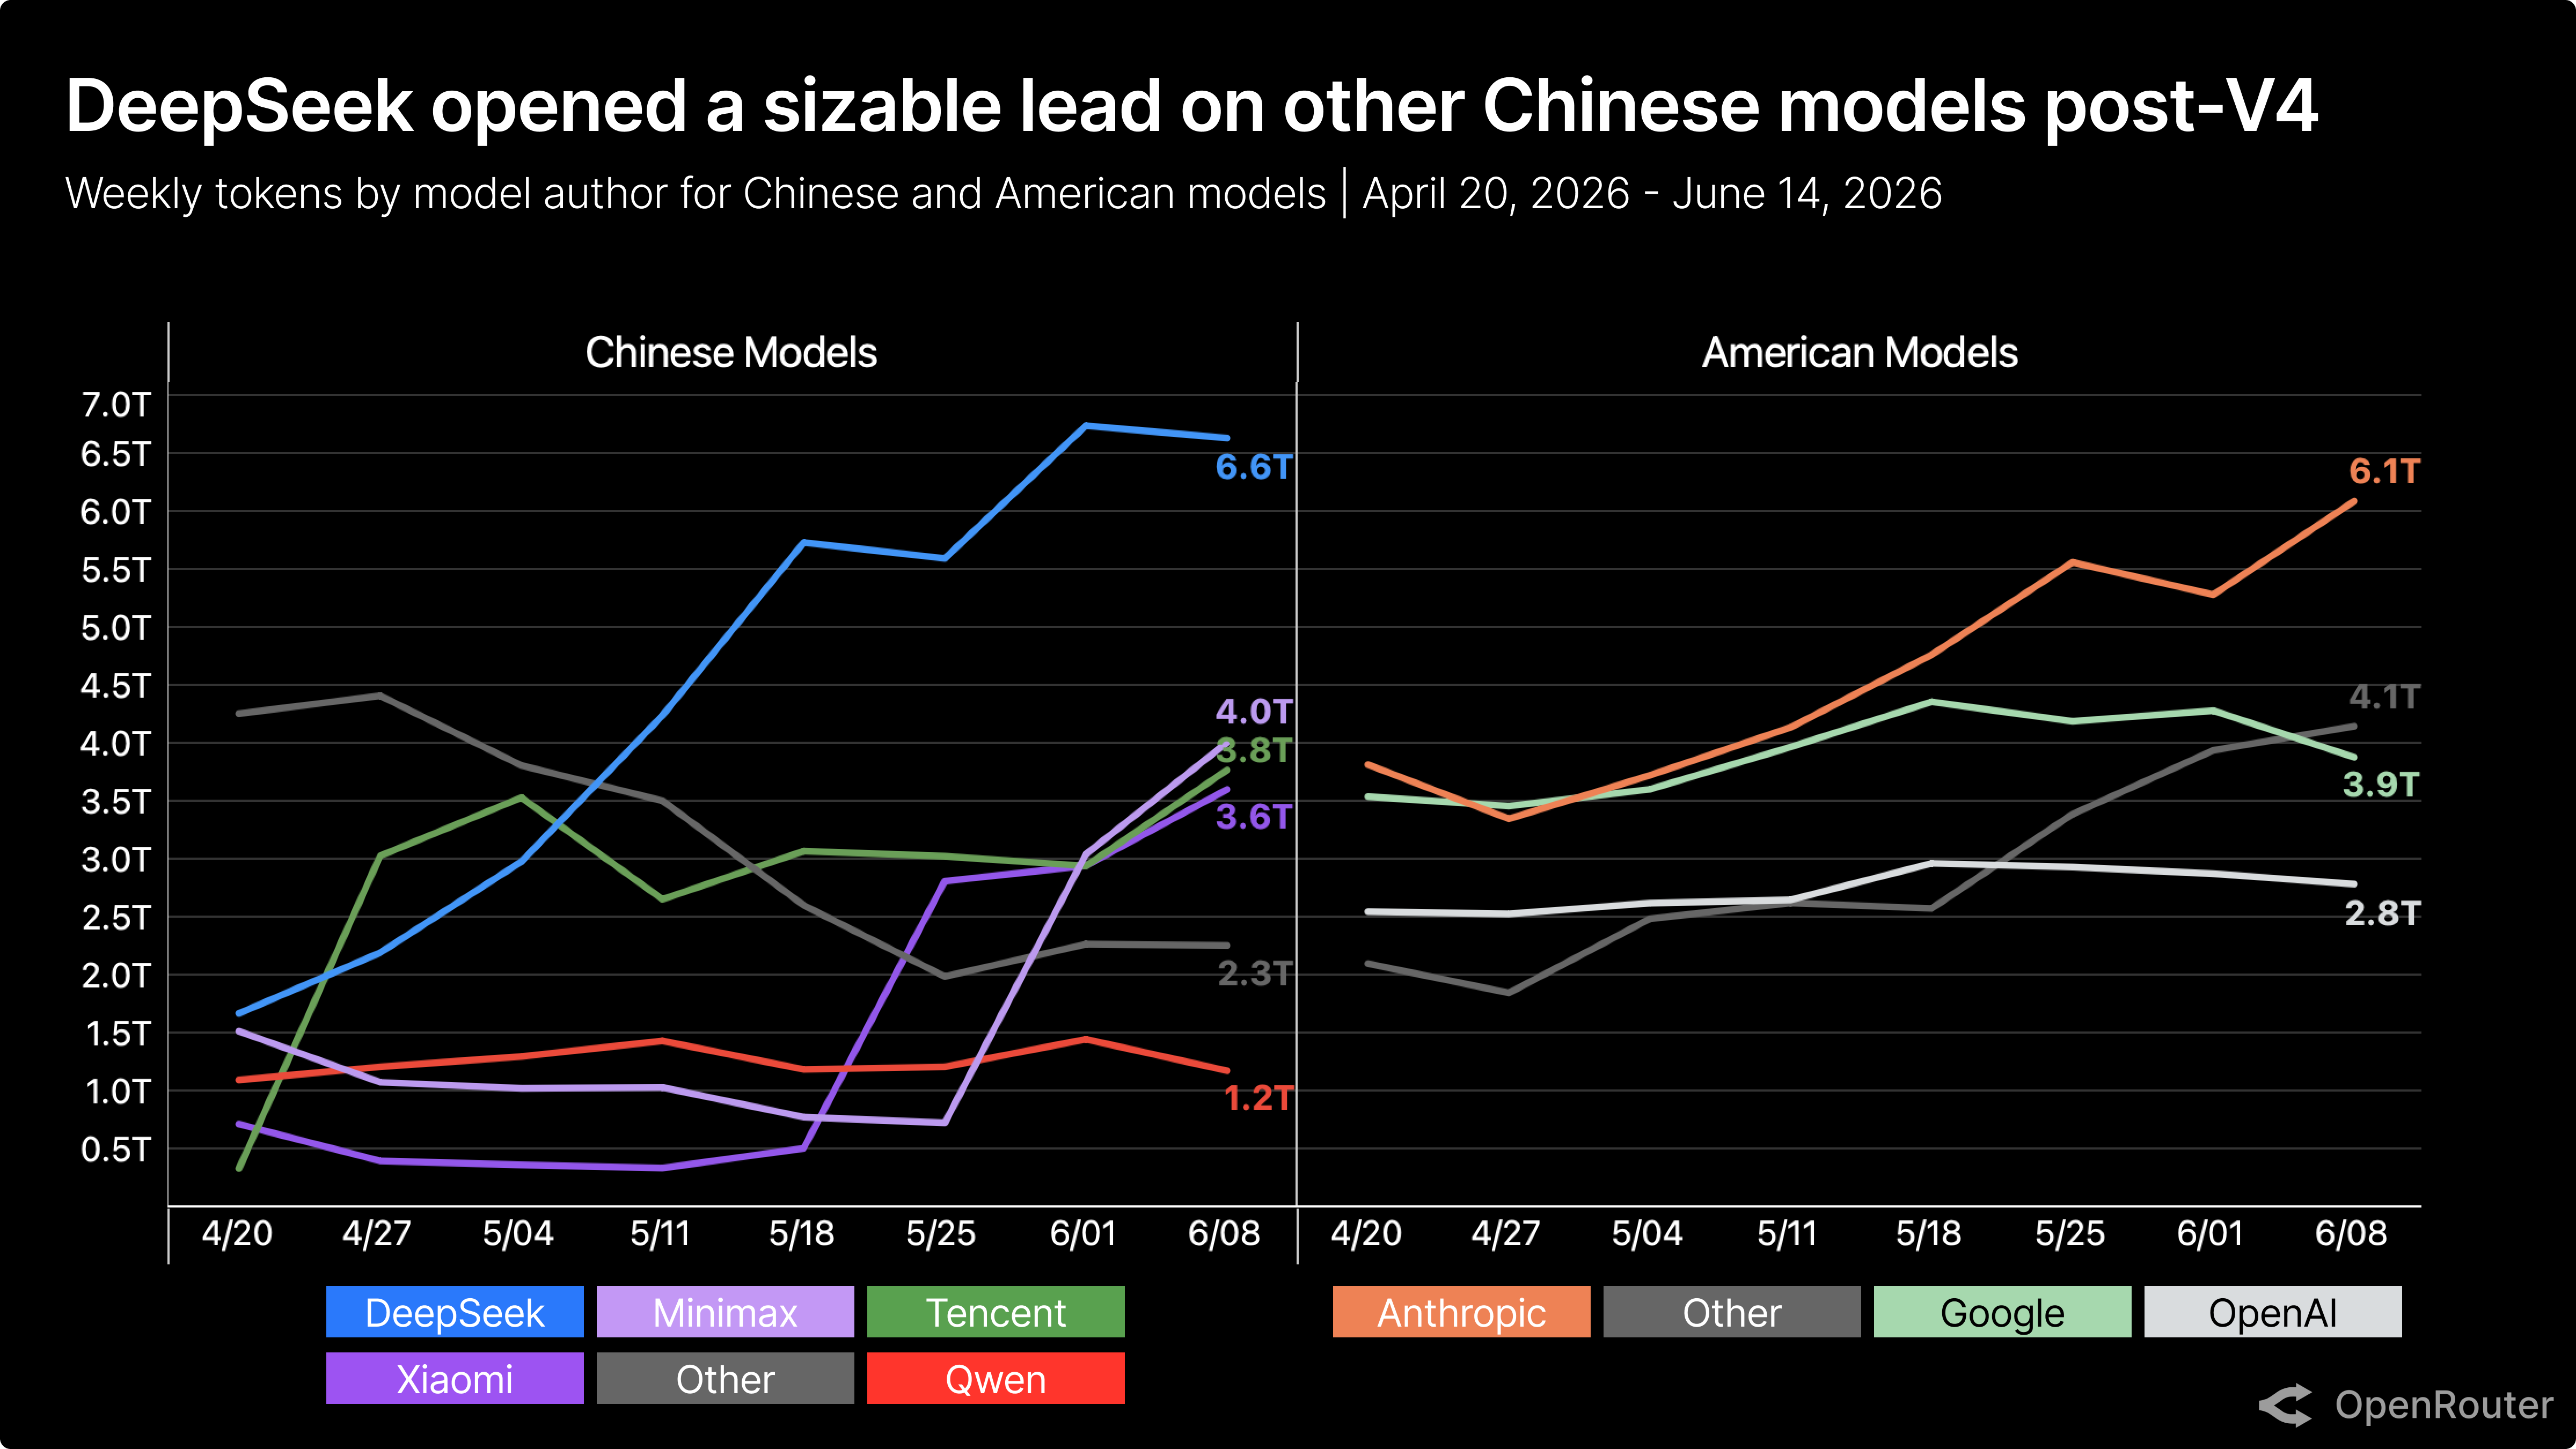
And to no surprise, it is DeepSeek leading the charge among Chinese models since the release of V4 in late April. While token usage amongst a few of the American leaders has plateaued over the past 6 weeks, multiple Chinese competitors saw tokens surge as June began.
With cost effective token usage dominating the summer headlines, we’d expect these cheaper-but-still-powerful open source models to continue to attract more tokens over time. As the Wall Street Journal mentions in this recent story (featuring OpenRouter data), “Startups and tech giants alike are mixing and matching AI models to avoid the premium prices”.
DeepSeek V4 is certain to be part of that mix.
Methodology Notes
A few notes on how we put these numbers together:
- Source: OpenRouter’s request logs.
- Sample size: Over 450 trillion tokens from January 1, 2026 - June 14, 2026.
- Share metric: All “share” figures refer to share of token volume (input and output combined), not share of spend. As the pricing section notes, the two can diverge sharply for low-cost models like V4.
- Activity type: We split token traffic at the API key level into three main categories (Agentic, Mixed, and Human). These are assigned according to a 7-signal weighted composite score that includes inputs such as tool call rate, turn count, gap timing, and others. Because the split happens at the key level, a single key doing mixed work is classified by its dominant pattern rather than per request.
Related items
92
FeaturedOpenRouter Launches Prompt Caching with Sticky Routing to Drastically Reduce Multi-Turn Costs
OpenRouter 推出提示缓存与粘性路由,大幅降低多轮对话成本
For developers making frequent AI API calls, this feature is a direct money-saver. Sticky routing guarantees cache hit rates, and session_id requires zero configuration—every OpenRouter user should try it immediately.
91
FeaturedEnabling Two Settings Triples ARC-AGI-3 Benchmark Scores
启用两项设置使ARC-AGI-3基准测试分数提升三倍
This finding is crucial! It shows that model performance depends not only on training but also on inference-time configuration. For AI engineers and researchers, this is a must-know optimization direction. Teams deploying models on resource-constrained devices in particular could find a low-cost way to boost capabilities.
91
FeaturedGPT-5.6: Fusing Frontier Intelligence with Frontier Efficiency
GPT-5.6:前沿智能与前沿效率的融合
This news is worth watching as it marks a shift from pure parameter scaling to efficiency competition. For AI developers and business decision-makers, GPT-5.6 means higher performance at lower cost, especially for long-context or agentic tasks previously hindered by inference expenses. OpenAI's move may redefine what 'frontier' means.
91
FeaturedLFM2.5-Encoders: New Models for Fast Long-Context Inference on CPU
LFM2.5-Encoder:面向CPU快速长上下文推理的新模型
This blog post catches my eye because it directly solves the pain point of running long-context LLMs on CPU. For teams or individual developers without high-end GPUs, the LFM2.5-Encoder series offers a ready-to-use open-source solution. Highly recommended for those working on RAG, document search, or code analysis—now a standard server can handle million-token documents.
91
FeaturedGPT-Red: OpenAI Automates Red Teaming via Self-Play to Boost Model Robustness
GPT-Red:OpenAI通过自我对弈实现AI红队自动化,提升模型鲁棒性
GPT-Red marks a milestone from human to automated red-teaming—essential for safety engineers and alignment researchers. While reducing cost, it also raises ethical questions about automated attacks, worth pondering for everyone in AI governance.
91
FeaturedOpenAI Launches GPT-5.5 Bio Bug Bounty Program
OpenAI推出GPT-5.5生物漏洞赏金计划
This program deserves attention as it pioneers the extension of AI bug bounty to biosecurity, offering a new research direction for the security community and a practical training ground for AI risk governance. It is particularly important for model safety researchers, biosecurity experts, and practitioners concerned about dual-use AI risks.
91
FeaturedvLLM Introduces Native-Speed Transformers Modeling Backend for Enhanced Inference Performance
vLLM推出原生速度Transformers建模后端,大幅提升推理性能
This update is critical for AI engineering teams: eliminating format conversion speeds up model iteration, and 2-5x speedup directly reduces GPU costs. If you're building LLM online services or batch inference, this is practically a must-read technical update.
90
FeaturedGoogle DeepMind Introduces SL2T, a Sign Language-to-Text Model for Deaf Users
Google DeepMind 发布手语转文本模型 SL2T,助力聋人用户
This news matters not only as a technical breakthrough but also as a sign that AI is beginning to address the needs of marginalized groups. For developers, the architecture and technical approach of SL2T merit deep study; for accessibility advocates, it's a key case for advancing industry standards.