Qwen Introduces Qwen3.8-Flash-Next: Multimodal MoE Model Previewing Qwen4 Architecture
Score
74提供了新模型的核心架构信息和实测量化体验,对比常见新闻稿有增量细节。
来自资深开发者的第一手试用记录,客观且包含实用偏好建议。
给出了具体的量化版本和运行平台,对想本地部署的开发者有直接参考价值。
模型刚发布即被试用报道,时效性极佳。
Simon Willison是知名的技术博主和开发者,信源可信度较高。
Base 82.5 × T2 Source weight ×0.9 = 74
Curation line 70Selected
Why selected
The post is a hands-on evaluation by veteran developer Simon Willison, highlighting new model traits and quantized runtime experience with unique personal insights.
AI commentary
「This isn't just a model announcement—it's the first practical run-down of Qwen3.8-Flash-Next with specific quantized builds worth trying. For anyone tracking next-gen architecture, this blog is more useful than the official press release.」
Quick overview
Qwen has released Qwen3.8-Flash-Next, an open multimodal MoE model with 125B total parameters but only 6B active, offering a significant performance boost and serving as an early preview of the Qwen4 architecture. Simon Willison tested it on a DGX Spark using Unsloth quantized versions, trying the 72.5GB UD-IQ1_S and the 78.9GB UD-Q2_K_XL, particularly recommending the high reasoning effort configuration of UD-Q2_K_XL. Continuing Qwen's open-source path, this model is worth watching.
- Qwen3.8-Flash-Next is an open multimodal MoE model with 125B total parameters and only 6B active.
- It serves as an early preview of the Qwen4 architecture with notable performance gains.
- Simon Willison tested Unsloth quantized versions on a DGX Spark, recommending the UD-Q2_K_XL high reasoning effort config.
Full text
Showing the source text; the full translation is being generated.
It's pretty big: 125B tokens, but only 6B active which means it gets a pretty big performance boost.
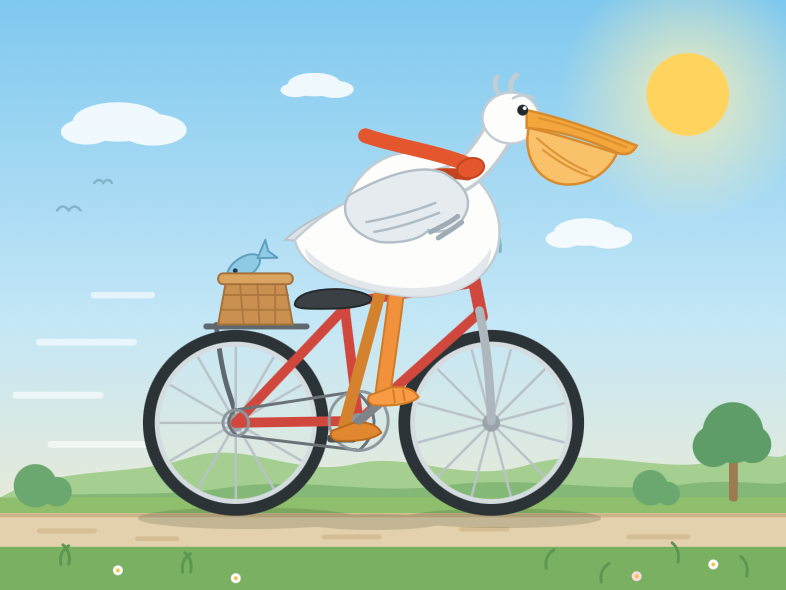
I've been trying it out on a DGX Spark using these Unsloth quantized models. I'm still exploring the model - so far I've tried the 72.5GB UD-IQ1_S one (producing these pelicans) and the 78.9GB UD-Q2_K_XL (producing these).
My favorite so far was this xhigh reasoning effort one from UD-Q2_K_XL:
Via Hacker News
Tags: ai, generative-ai, llms, qwen, pelican-riding-a-bicycle, ai-in-china, nvidia-spark
Related items
FeaturedDeepSeek V4 Doubles Token Share on OpenRouter, Driven by Agentic Workloads
DeepSeek V4 在 OpenRouter 上的代币份额翻倍,智能体工作负载成主要驱动力
The rapid adoption of DeepSeek V4 signals a strong market preference for high-performance, low-cost inference models, especially as agentic use cases reshape AI deployment.
91
FeaturedEnabling Two Settings Triples ARC-AGI-3 Benchmark Scores
启用两项设置使ARC-AGI-3基准测试分数提升三倍
This finding is crucial! It shows that model performance depends not only on training but also on inference-time configuration. For AI engineers and researchers, this is a must-know optimization direction. Teams deploying models on resource-constrained devices in particular could find a low-cost way to boost capabilities.
91
FeaturedGPT-5.6: Fusing Frontier Intelligence with Frontier Efficiency
GPT-5.6:前沿智能与前沿效率的融合
This news is worth watching as it marks a shift from pure parameter scaling to efficiency competition. For AI developers and business decision-makers, GPT-5.6 means higher performance at lower cost, especially for long-context or agentic tasks previously hindered by inference expenses. OpenAI's move may redefine what 'frontier' means.
91
FeaturedLFM2.5-Encoders: New Models for Fast Long-Context Inference on CPU
LFM2.5-Encoder:面向CPU快速长上下文推理的新模型
This blog post catches my eye because it directly solves the pain point of running long-context LLMs on CPU. For teams or individual developers without high-end GPUs, the LFM2.5-Encoder series offers a ready-to-use open-source solution. Highly recommended for those working on RAG, document search, or code analysis—now a standard server can handle million-token documents.
91
FeaturedGPT-Red: OpenAI Automates Red Teaming via Self-Play to Boost Model Robustness
GPT-Red:OpenAI通过自我对弈实现AI红队自动化,提升模型鲁棒性
GPT-Red marks a milestone from human to automated red-teaming—essential for safety engineers and alignment researchers. While reducing cost, it also raises ethical questions about automated attacks, worth pondering for everyone in AI governance.
91
FeaturedOpenAI Launches GPT-5.5 Bio Bug Bounty Program
OpenAI推出GPT-5.5生物漏洞赏金计划
This program deserves attention as it pioneers the extension of AI bug bounty to biosecurity, offering a new research direction for the security community and a practical training ground for AI risk governance. It is particularly important for model safety researchers, biosecurity experts, and practitioners concerned about dual-use AI risks.
91
FeaturedvLLM Introduces Native-Speed Transformers Modeling Backend for Enhanced Inference Performance
vLLM推出原生速度Transformers建模后端,大幅提升推理性能
This update is critical for AI engineering teams: eliminating format conversion speeds up model iteration, and 2-5x speedup directly reduces GPU costs. If you're building LLM online services or batch inference, this is practically a must-read technical update.
90
FeaturedGoogle DeepMind Introduces SL2T, a Sign Language-to-Text Model for Deaf Users
Google DeepMind 发布手语转文本模型 SL2T,助力聋人用户
This news matters not only as a technical breakthrough but also as a sign that AI is beginning to address the needs of marginalized groups. For developers, the architecture and technical approach of SL2T merit deep study; for accessibility advocates, it's a key case for advancing industry standards.