Anthropic Updates Claude Fable 5 Biology Safeguards, Substantially Reduces Fallbacks
Score
78官方首次披露模型安全更新方向,信息增量明显,但缺少具体机制细节。
内容简短直接,准确传递关键变化,但未提供技术细节或数据支撑。
对依赖 Claude 处理生物医疗场景的开发者具有直接参考价值,可预判模型行为变化。
来自 Anthropic 官方新闻,时效性高,属于最新发布的安全更新公告。
Anthropic 官方渠道发布,信源权威可靠。
Base 78 × T1 Source weight ×1 = 78
Curation line 60Selected
Why selected
The information comes from an official source and signals model behavior changes, providing clear information gain but lacking technical specifics.
AI commentary
「Developers should watch this because fewer safety fallbacks will directly change Claude’s behavior in biomedical settings. If you are building medical Q&A or bioinformatics tools, re-run baseline tests to confirm no new boundary risks.」
Quick overview
Anthropic is updating Claude Fable 5’s biology safeguards in a way that substantially reduces fallbacks. According to the official announcement, the model will be less likely to fall back to generic safety refusals when handling biology-related requests. The change is designed to keep safety guardrails intact while improving answer quality in sensitive biomedical contexts. Anthropic says the update focuses on precision rather than simply loosening or tightening restrictions. However, no technical details have been released yet. Users and developers in biotech, healthcare, and research fields may need to test Claude Fable 5’s new behavior to understand the exact impact.
- Anthropic announced updates to Claude Fable 5’s biology safeguards.
- The update substantially reduces fallbacks, limiting unnecessary refusals.
- No technical details were disclosed, but the focus is on more precise safety policies.
Full text
Showing the source text; the full translation is being generated.
Improving Fable 5's biology safeguards
Aug 7, 2026
We’re making updates to Claude Fable 5’s biology safeguards in a way that substantially reduces false positives. Fable 5 users will now experience many fewer “fallbacks”—where the system switches to a less capable model after they make a biology-related query. In our testing, this update reduced biology-related fallbacks by about 85% across our product surfaces.1
Fable 5 will thus be able to assist with a wider range of biology tasks.
In practice, users should see far fewer fallbacks on everyday health and educational questions—for example, interpreting lab results, understanding symptoms, and learning about biology in an educational context. Healthcare professionals will be able to receive more support from Fable 5 on clinical tasks.
We believe the greatest opportunity for AI to positively affect the world is in biology and medicine, and we're investing significantly in building a responsible way to give biologists frontier access. Today, Fable still falls back to Opus 5 for requests we consider dual-use—including virology, toxicology, and molecular design—so it isn't yet usable for professional biology research and drug development. We're committed to closing that gap through trusted access pathways for frontier biology capabilities.
Why we built strong biology safeguards
Our objective is to get Fable 5’s frontier capabilities into the hands of as many of our users as possible, as quickly as possible. However, to do so, we need to manage the increasing risks that come with models this capable. One such risk is in the field of biology: Fable 5 can now outperform experts on some highly complex biological tasks and provide operational support on others. That means that it can provide genuine assistance to a researcher developing a new medical treatment (which is the reason we’re so keen to widen access to the model via both classifier improvements and trusted access programs). But in the wrong hands, those same capabilities could be used by a malicious actor, for example in developing a biological weapon. Our capability assessments show that Fable 5 could provide significant uplift to such an actor—that is, it could provide them with capabilities they could not find anywhere else.
It’s often difficult to tell apart beneficial and harmful uses of AI in biology. For example, in some cases researching a treatment for a disease requires scientists to produce the dangerous compounds that cause that disease in the first place. This is most obvious for live vaccines, which require scientists to grow the same pathogen they’re aiming to prevent. It’s also the case for some medicines. To develop the drug captopril, which treats hypertension, scientists isolated toxic components of snake venom that crash blood pressure in humans. As new biological capabilities develop on the frontier of AI, we need to be cautious to ensure that the new risks they pose do not materialize ahead of their potential scientific benefits.
Sophisticated actors who wish to use our models to do harm know how to exploit this ambiguity to obscure their intent, making dangerous tasks look like ordinary research pursuits. The US Intelligence Community’s 2026 Annual Threat Assessment makes clear that such actors exist, and that advances in biotechnology including synthetic biology and genomic editing “could lead to novel biological threats.” It notes that several state actors likely maintain active offensive biological and chemical weapons programs—programs that could be accelerated by access to the raw capabilities of frontier AI models.
Because of our concerns about these “dual-use” capabilities (those that could be used for beneficial or harmful purposes, and where the line between them is not always easy to draw), we intentionally launched Fable 5 with almost all biology queries blocked. This enabled us to make the model available for users in other domains. We knew this would be frustrating for legitimate biology users: it would result in a high number of false positives in the near-term, where users asking biology-related questions would have their requests blocked and sent to a less capable model. Nevertheless, we chose to make this tradeoff because the cost of Fable being misused in a dual-use domain like biology could potentially be catastrophic.
How our biology safeguards work
One of the core ways we protect against misuse in biology is via safety classifiers: smaller, automated AI systems that detect when Fable 5 is asked to perform a safeguarded biology task, or produce a harmful output (we've previously written about our similar classifiers in the domain of cybersecurity).
In the case of Fable 5, when a classifier fires, the model re-routes the user’s request to Opus 5, a capable model that does not have the same level of biological capability as Fable 5 and which cannot provide as much assistance to a malicious user. This is the fallback that users see when their requests are blocked.
Developing precise, robust classifiers is not a straightforward task. For a classifier to work rapidly and consistently, it has to learn the difference between what we consider “in scope” and “out of scope” for the topics and queries we consider to be potentially harmful. It takes time and iteration to tune the classifiers, avoiding both false positives (where classifiers fire on out-of-scope content) and false negatives (where in-scope content is missed). We also require our classifiers to be robust to attempts to bypass them (known as jailbreaks), which requires even further research and testing.
Starting with a very broad biology classifier meant that we could give our users access to Fable 5 while we continued our research aimed at refining it. The alternative—holding back the model until much more safeguards progress was made—would have delayed the model’s general access, and its potential benefits to our users, by weeks or months.
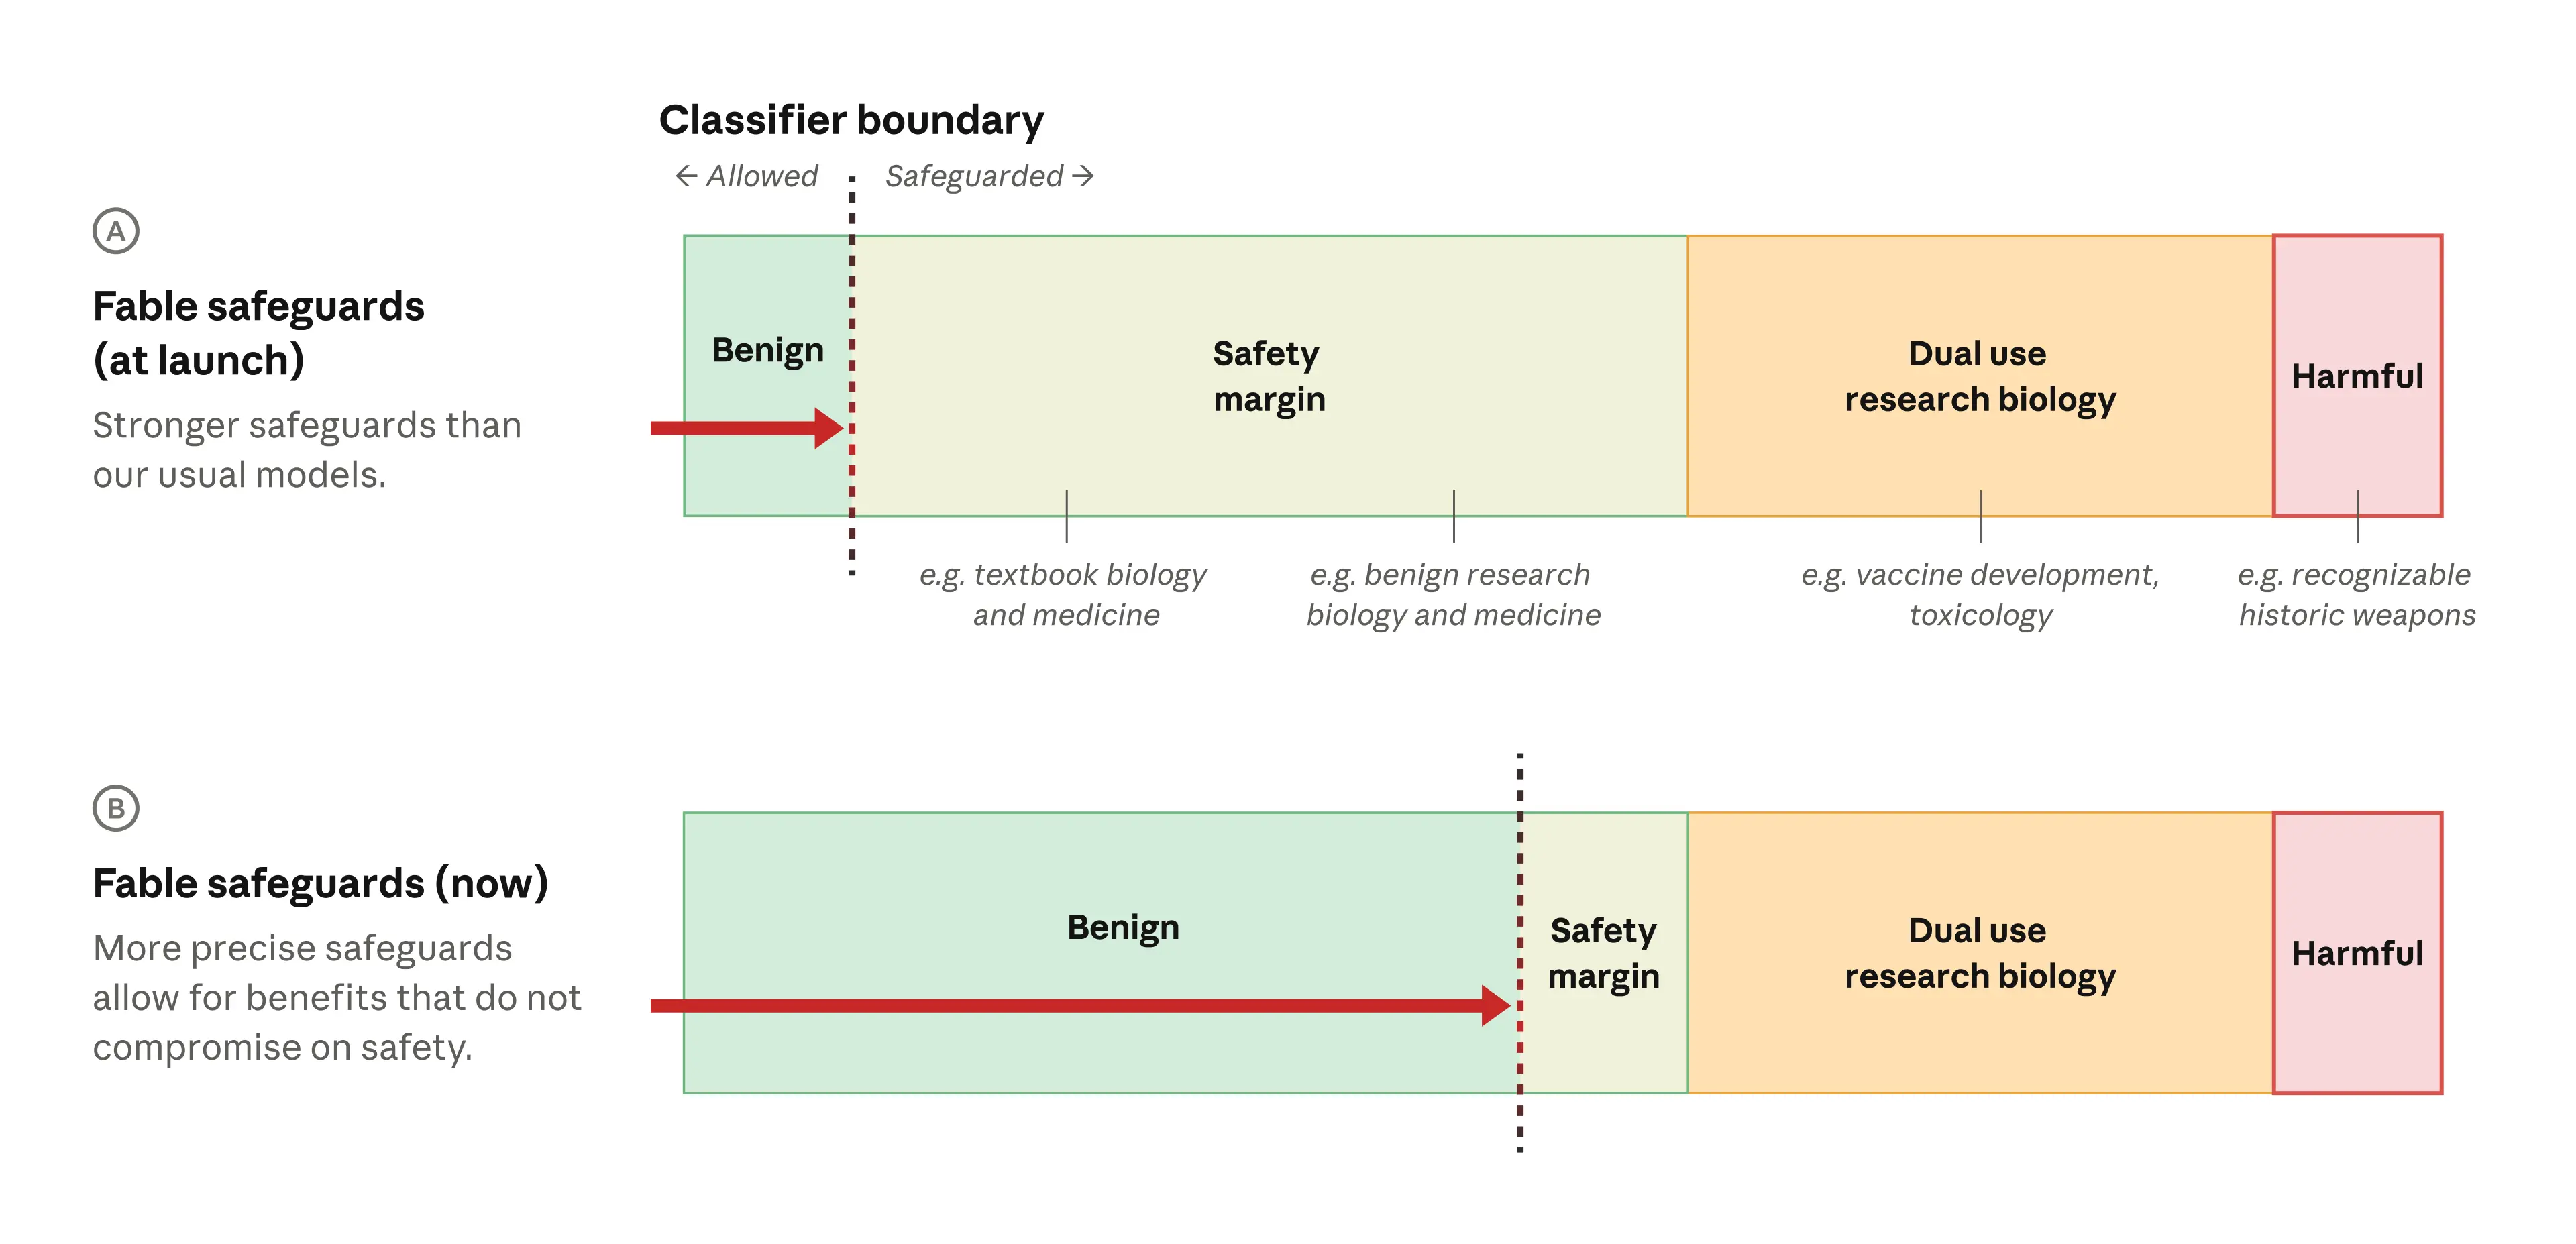
Over the past several weeks, we've carefully rewritten the classifier’s constitution (which consists of a collection of rules to help the model discern between safeguarded and allowed content), taking care to carve out benign uses in detail. We solicited feedback on the changes from a diverse range of experts (both internal and external to Anthropic). We then developed updated training data for the classifier based on that constitution, and retrained it, and verified the new classifier would still generally trigger for harmful and dual-use research biology content but would now enable a wider range of benign and beneficial uses.
As is illustrated in the diagram below, these updates meant that—compared to at the time of Fable 5’s launch—the classifier will trigger for many fewer benign biology-related requests.
Conclusions
There’s still much more to be done to refine our safeguards. There will inevitably remain false positives—requests that fall within the classifier’s safety margin where the request is very low-risk but where the classifier still fires. As we noted above, Fable will continue to block dual use professional biology and drug development queries because of potential dual-use risk. We are fully committed to developing a safe, scalable path for researchers to use our most capable models via trusted access pathways.
We hope you’ll continue to share your feedback with us so we can improve our safeguards even further.
Footnotes
1 As a result, we expect the total number of fallbacks—for biology–related or any other reasons—will also be reduced: by roughly 67% on Claude.ai, 55% on Cowork, 17% on Claude Code, and 7% on the Claude Platform.
Related content
Mariano-Florentino (Tino) Cuéllar to join Anthropic as Chief Global Affairs Officer
Mariano-Florentino (Tino) Cuéllar will join Anthropic as its first Chief Global Affairs Officer.
Read moreInvestigating three real-world incidents in our cybersecurity evaluations
Read moreOur position on open-weights models
Read moreOther reports on this story
- T1Anthropic:News(网页)Anthropic Launches Claude Economic Index Connector01:28
- T2TechCrunch:AI(RSS)Anthropic Updates Claude Voice Mode with Meeting Rescheduling and Email Drafting03:00
- T2Simon Willison 博客(Atom)Anthropic Backs Down: Claude Fable 5 Permanently Included in Subscription Plans14:00
Related items
FeaturedDeepSeek V4 Doubles Token Share on OpenRouter, Driven by Agentic Workloads
DeepSeek V4 在 OpenRouter 上的代币份额翻倍,智能体工作负载成主要驱动力
The rapid adoption of DeepSeek V4 signals a strong market preference for high-performance, low-cost inference models, especially as agentic use cases reshape AI deployment.
91
FeaturedEnabling Two Settings Triples ARC-AGI-3 Benchmark Scores
启用两项设置使ARC-AGI-3基准测试分数提升三倍
This finding is crucial! It shows that model performance depends not only on training but also on inference-time configuration. For AI engineers and researchers, this is a must-know optimization direction. Teams deploying models on resource-constrained devices in particular could find a low-cost way to boost capabilities.
91
FeaturedGPT-5.6: Fusing Frontier Intelligence with Frontier Efficiency
GPT-5.6:前沿智能与前沿效率的融合
This news is worth watching as it marks a shift from pure parameter scaling to efficiency competition. For AI developers and business decision-makers, GPT-5.6 means higher performance at lower cost, especially for long-context or agentic tasks previously hindered by inference expenses. OpenAI's move may redefine what 'frontier' means.
91
FeaturedLFM2.5-Encoders: New Models for Fast Long-Context Inference on CPU
LFM2.5-Encoder:面向CPU快速长上下文推理的新模型
This blog post catches my eye because it directly solves the pain point of running long-context LLMs on CPU. For teams or individual developers without high-end GPUs, the LFM2.5-Encoder series offers a ready-to-use open-source solution. Highly recommended for those working on RAG, document search, or code analysis—now a standard server can handle million-token documents.
91
FeaturedGPT-Red: OpenAI Automates Red Teaming via Self-Play to Boost Model Robustness
GPT-Red:OpenAI通过自我对弈实现AI红队自动化,提升模型鲁棒性
GPT-Red marks a milestone from human to automated red-teaming—essential for safety engineers and alignment researchers. While reducing cost, it also raises ethical questions about automated attacks, worth pondering for everyone in AI governance.
91
FeaturedOpenAI Launches GPT-5.5 Bio Bug Bounty Program
OpenAI推出GPT-5.5生物漏洞赏金计划
This program deserves attention as it pioneers the extension of AI bug bounty to biosecurity, offering a new research direction for the security community and a practical training ground for AI risk governance. It is particularly important for model safety researchers, biosecurity experts, and practitioners concerned about dual-use AI risks.
91
FeaturedvLLM Introduces Native-Speed Transformers Modeling Backend for Enhanced Inference Performance
vLLM推出原生速度Transformers建模后端,大幅提升推理性能
This update is critical for AI engineering teams: eliminating format conversion speeds up model iteration, and 2-5x speedup directly reduces GPU costs. If you're building LLM online services or batch inference, this is practically a must-read technical update.
90
FeaturedGoogle DeepMind Introduces SL2T, a Sign Language-to-Text Model for Deaf Users
Google DeepMind 发布手语转文本模型 SL2T,助力聋人用户
This news matters not only as a technical breakthrough but also as a sign that AI is beginning to address the needs of marginalized groups. For developers, the architecture and technical approach of SL2T merit deep study; for accessibility advocates, it's a key case for advancing industry standards.