Start Building with Nano Banana 2 Lite and Gemini Omni Flash
Score
74Why selected
The models are highly innovative and practical, but their performance in large-scale scenarios still needs further validation.
AI commentary
「This move enables developers to access cutting-edge image and video generation capabilities at lower cost, accelerating the deployment of creative and commercial applications.」
Quick overview
Google DeepMind launches Nano Banana 2 Lite, its fastest and most cost-efficient Gemini image model, alongside Gemini Omni Flash for high-quality video and conversational editing. These models aim to scale creative workflows, reduce compute costs, and enhance real-time interaction.
- Nano Banana 2 Lite is the fastest and most cost-efficient Gemini image model, suitable for large-scale deployment.
- Gemini Omni Flash supports high-quality video generation and conversational editing for natural interaction.
- Both models are available via API for developers to integrate into existing applications.
- DeepMind emphasizes significantly reduced inference cost while maintaining quality.
Full text
Showing the source text; the full translation is being generated.
Start building with Nano Banana 2 Lite and Gemini Omni Flash
Jun 30, 2026
· Share x.com Facebook LinkedIn Mail Copy linkWe’re making it easier to experiment and scale your ideas with Nano Banana 2 Lite, our fastest, most cost-efficient Gemini Image model, and Gemini Omni Flash for high-quality video generation and conversational editing.
Today, we’re making it faster and easier to experiment, refine and scale your ideas with two major releases:
- Introducing Nano Banana 2 Lite: Our fastest, most cost-efficient image model in the Nano Banana family yet, built for high throughput, speed and scale. Nano Banana 2 Lite is available today in Google AI Studio, Gemini API and Gemini Enterprise Agent Platform. It is also rolling out today in Google consumer surfaces including AI Mode in Search, Gemini app and many other products.
- Bringing Gemini Omni Flash to developers: Our high quality, cost-efficient model for video generation and conversational editing, now available in Google AI Studio, the Gemini API and Gemini Enterprise Agent Platform for the first time. Omni Flash is also available in the Gemini app and Google Flow.
Building with generative media is often about creative iteration. With these two models, developers can build comprehensive, end-to-end multimedia experiences that connect rapid image generation with video creation and editing. Whether your workflow requires generating thousands of images or editing multi-turn video sequences, you now have two new models to build faster, iterate seamlessly and bring your creative vision to life.
Nano Banana 2 Lite: our fastest most cost-efficient Gemini Image model
Watch a side-by-side comparison of image generation speed and quality between Nano Banana 2 Lite and Nano Banana 2 using a simple prompt.
Nano Banana 2 Lite (gemini-3.1-flash-lite-image) is designed for rapid ideation and high-velocity developer pipelines where speed and cost are the primary constraints. It’s our recommended replacement for developers currently using our first version of Nano Banana (gemini-2.5-flash-image), you can swap it out now for immediate benefits across key performance dimensions.
Performance benchmarks for Nano Banana 2 and 2 Lite compared to competitor AI image models, evaluating trade-offs between generation/editing quality (Elo scores), processing latency and cost per 1K-resolution image.

Nano Banana 2 Lite shines in:
- Latency: Delivers text-to-image outputs in 4 seconds. This makes it ideal for interactive prototyping and rapid visual drafting.
- Cost-efficiency ($0.034 per 1K image): A cost-efficient choice for developers focused on drafting, ideating, managing operational budgets or low-bandwidth usage.
Despite prioritizing speed, Nano Banana 2 Lite retains reliable prompt adherence, strong character consistency and legible in-image text rendering.
Understanding the Nano Banana family
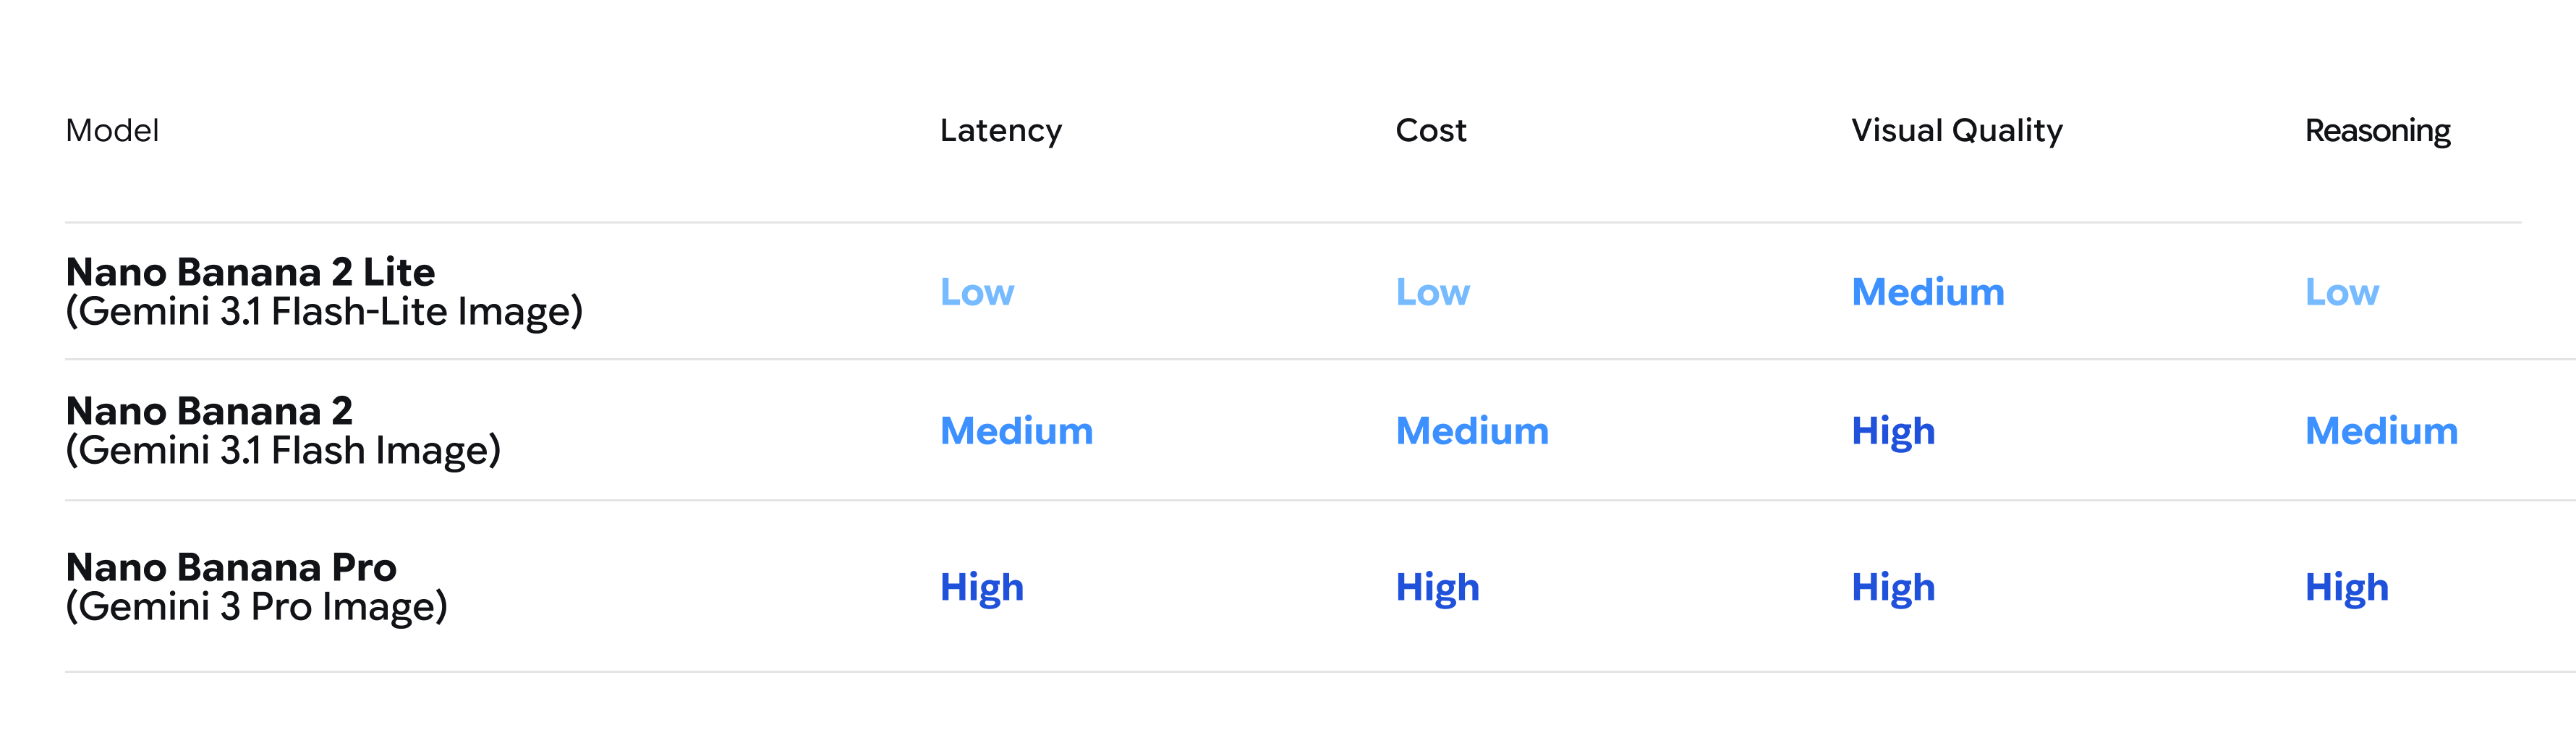
- Nano Banana 2 Lite (Gemini 3.1 Flash Lite Image): Built for speed. Optimized for near-real-time, high-volume workflows where ultra-low latency is critical.
- Nano Banana 2 (Gemini 3.1 Flash Image): The generalist workhorse. Delivers high quality at a lower latency, offering the best balance of performance and cost.
- Nano Banana Pro (Gemini 3 Pro Image): Optimized for complex, professional use cases. It provides the most robust control and advanced reasoning for tasks where accuracy is more important than speed.
- Nano Banana (Gemini 2.5 Flash Image): Our legacy model. We recommend upgrading to Nano Banana 2 Lite for better quality, faster speeds and lower costs.
To see the full list of model capabilities and how to integrate check out the developer docs.
Alongside its release on developer platforms, Nano Banana 2 Lite is also coming to Google consumer surfaces including AI Mode in Search, Gemini app, NotebookLM, Google Photos, Stitch, Google Flow, and Google Ads.
Experience high-quality, cost-efficient video editing and generation with Gemini Omni Flash
Watch as someone uses Gemini Omni to perform four digital magic tricks, like pulling a 3D balloon word out of her phone and pouring water from the screen into a glass. There is a small “original" video in the corner revealing how she actually filmed the tricks before the Omni generated special effects were added.
At Google I/O we introduced Gemini Omni Flash, the model where Gemini’s multimodal reasoning meets video generation and editing. Today, Gemini Omni Flash (gemini-omni-flash-preview) is rolling to developers via the Gemini API and Google AI Studio, natively supporting high-quality video generation and conversational editing from a combination of text, image and video inputs. This model is priced competitively at $0.10 per second of video output, which is the same as Veo 3.1 Fast.
Omni Flash shines in:
- Conversational video editing: Refine and edit videos using natural language.
- Multimodal referencing: Combine inputs like images, text and video to maintain control and consistency over your scene.
- Real-world knowledge: Omni draws on Gemini’s knowledge such as history, biology and narrative logic to construct compelling videos.
- Text and action synchronization: Connect text and graphics directly to video actions, through simple prompting.
For comprehensive benchmarking information, please visit Google DeepMind's Gemini Omni webpage.

Limitations:
- Omni offers 10-second video generations currently, with longer durations coming soon.
- Uploading audio references and scene extension is not yet supported in the Gemini API for this model.
- Video references up to 3 seconds in duration are accepted by the API schema but are not correctly processed by the model at this time.
- Character consistency when changing scenes or panning movements has some limitations but we are working to make this better.
Gemini Omni is available in public preview starting today in Google AI Studio and the Gemini API. To see the full list of model capabilities and regional specific limitations check out the developer docs.
Build with both models today
The real magic happens when you chain these models together. Use Nano Banana 2 Lite as a high-speed image generation model, then pass that image as a reference to Gemini Omni Flash to animate it into a high-quality video. Plus, by using the Interactions API for these multi-turn experiences, you can maintain session history and context so users can stack up to three sequential edits.
To help you get started we created a few demo apps you can remix that let you experience how you can pair both Nano Banana 2 Lite and Gemini Omni Flash into one workflow.
Anywhere is a demo app built to showcase the strong capabilities of both models. Take a selfie or upload a photo, and the app uses Nano Banana 2 Lite to instantly transport you to dozens of iconic landmarks. Then, when an image is clicked, Omni Flash is used to turn the generated image into an animated clip of the location.
Space Lift is a demo interior design app powered by Nano Banana 2 Lite and Gemini Omni, that lets you instantly reimagine any room by uploading a photo. The app automatically generates fully realized concepts across various design aesthetics. Once you find a look you love, tap the video button to watch Omni bring the design to life with a cinematic showcase, letting you experience your new space in motion before making it a reality.
Omni product studio is a demo app that converts static images created by Nano Banana 2 Lite into cinematic e-commerce videos created by Gemini Omni. This demo illustrates building interactive media by merging multimodal inputs through quick interaction with an image-to-video output.



Build with safety and transparency
Built on Google’s secure infrastructure, Gemini Omni and Nano Banana 2 Lite use SynthID watermarking. You can verify AI content through the Gemini app, Gemini in Chrome or Search. Learn more about how we're expanding our verification tools to help you understand how content was created and edited across the web.
Start your project today
Nano Banana 2 Lite resources:
- Head over to Google AI Studio to experiment with the model in the playground.
- Dive into our Gemini API Documentation.
- Check out our Nano Banana prompting guide, filled with best practices and example prompts.
Gemini Omni Flash resources:
- Head over to Google AI Studio to experiment with the model in the playground.
- Dive into our Gemini API Documentation.
- Check out our Gemini Omni Flash prompting guide, filled with best practices and example prompts.
Related items
FeaturedDeepSeek V4 Doubles Token Share on OpenRouter, Driven by Agentic Workloads
DeepSeek V4 在 OpenRouter 上的代币份额翻倍,智能体工作负载成主要驱动力
The rapid adoption of DeepSeek V4 signals a strong market preference for high-performance, low-cost inference models, especially as agentic use cases reshape AI deployment.
91
FeaturedEnabling Two Settings Triples ARC-AGI-3 Benchmark Scores
启用两项设置使ARC-AGI-3基准测试分数提升三倍
This finding is crucial! It shows that model performance depends not only on training but also on inference-time configuration. For AI engineers and researchers, this is a must-know optimization direction. Teams deploying models on resource-constrained devices in particular could find a low-cost way to boost capabilities.
91
FeaturedGPT-5.6: Fusing Frontier Intelligence with Frontier Efficiency
GPT-5.6:前沿智能与前沿效率的融合
This news is worth watching as it marks a shift from pure parameter scaling to efficiency competition. For AI developers and business decision-makers, GPT-5.6 means higher performance at lower cost, especially for long-context or agentic tasks previously hindered by inference expenses. OpenAI's move may redefine what 'frontier' means.
91
FeaturedLFM2.5-Encoders: New Models for Fast Long-Context Inference on CPU
LFM2.5-Encoder:面向CPU快速长上下文推理的新模型
This blog post catches my eye because it directly solves the pain point of running long-context LLMs on CPU. For teams or individual developers without high-end GPUs, the LFM2.5-Encoder series offers a ready-to-use open-source solution. Highly recommended for those working on RAG, document search, or code analysis—now a standard server can handle million-token documents.
91
FeaturedGPT-Red: OpenAI Automates Red Teaming via Self-Play to Boost Model Robustness
GPT-Red:OpenAI通过自我对弈实现AI红队自动化,提升模型鲁棒性
GPT-Red marks a milestone from human to automated red-teaming—essential for safety engineers and alignment researchers. While reducing cost, it also raises ethical questions about automated attacks, worth pondering for everyone in AI governance.
91
FeaturedOpenAI Launches GPT-5.5 Bio Bug Bounty Program
OpenAI推出GPT-5.5生物漏洞赏金计划
This program deserves attention as it pioneers the extension of AI bug bounty to biosecurity, offering a new research direction for the security community and a practical training ground for AI risk governance. It is particularly important for model safety researchers, biosecurity experts, and practitioners concerned about dual-use AI risks.
91
FeaturedvLLM Introduces Native-Speed Transformers Modeling Backend for Enhanced Inference Performance
vLLM推出原生速度Transformers建模后端,大幅提升推理性能
This update is critical for AI engineering teams: eliminating format conversion speeds up model iteration, and 2-5x speedup directly reduces GPU costs. If you're building LLM online services or batch inference, this is practically a must-read technical update.
90
FeaturedGoogle DeepMind Introduces SL2T, a Sign Language-to-Text Model for Deaf Users
Google DeepMind 发布手语转文本模型 SL2T,助力聋人用户
This news matters not only as a technical breakthrough but also as a sign that AI is beginning to address the needs of marginalized groups. For developers, the architecture and technical approach of SL2T merit deep study; for accessibility advocates, it's a key case for advancing industry standards.