CORS Chat: A Browser Tool for Testing OpenAI-Responses-Compatible Chat Endpoints
Score
72介绍了一个新发布的实用工具,附带了具体使用场景和特性,但未提供深入技术剖析。
内容清晰简洁,工具设计合理,作者有实际验证,但篇幅较短,缺少架构说明。
对本地 LLM 开发者来说可以直接使用,解决了测试界面缺失的问题,且支持导出 JSON。
工具当天构建并发布,信息新鲜,反映了作者当前的工作流和最新模型环境。
Simon Willison 是知名开发者博主,原始博客来源可信,且附有可访问链接。
Base 80 × T2 Source weight ×0.9 = 72
Curation line 70Selected
Why selected
Information gain is solid as it introduces a concrete new tool with design details, but it's essentially a personal utility share with limited novelty.
AI commentary
「This small tool hits a real pain point for local model testing: when you quickly want to verify a compatible chat endpoint, a lightweight UI is missing. If you develop LLM apps or debug local deployments, this is worth a try, especially the progressive SVG rendering which is far more intuitive than plain-text logs.」
Quick overview
Simon Willison built CORS Chat today with GPT-5.6-Sol xhigh to test OpenAI-Responses-compatible chat endpoints. It works with LM Studio (using the --cors option) and OpenRouter, and has been exercised against Qwen 3.8 27B running locally on both an M5 MacBook Pro and an NVIDIA DGX Spark. Conversations persist in the browser and can be exported as copy-pasted JSON. A neat feature is that it detects SVG images being generated and progressively renders them in chat while tokens stream in, making it handy for multimodal testing.
- CORS Chat is a browser-based web UI for interacting with OpenAI-Responses-compatible endpoints, supporting LM Studio and OpenRouter.
- Conversations are persisted in the browser and can be exported as JSON for replay and debugging.
- It progressively renders SVG images as tokens stream in, enabling real-time multimodal output viewing.
- Verified with local models on M5 MacBook Pro and NVIDIA DGX Spark, as well as remote APIs.
Full text
Showing the source text; the full translation is being generated.
Tool: CORS Chat
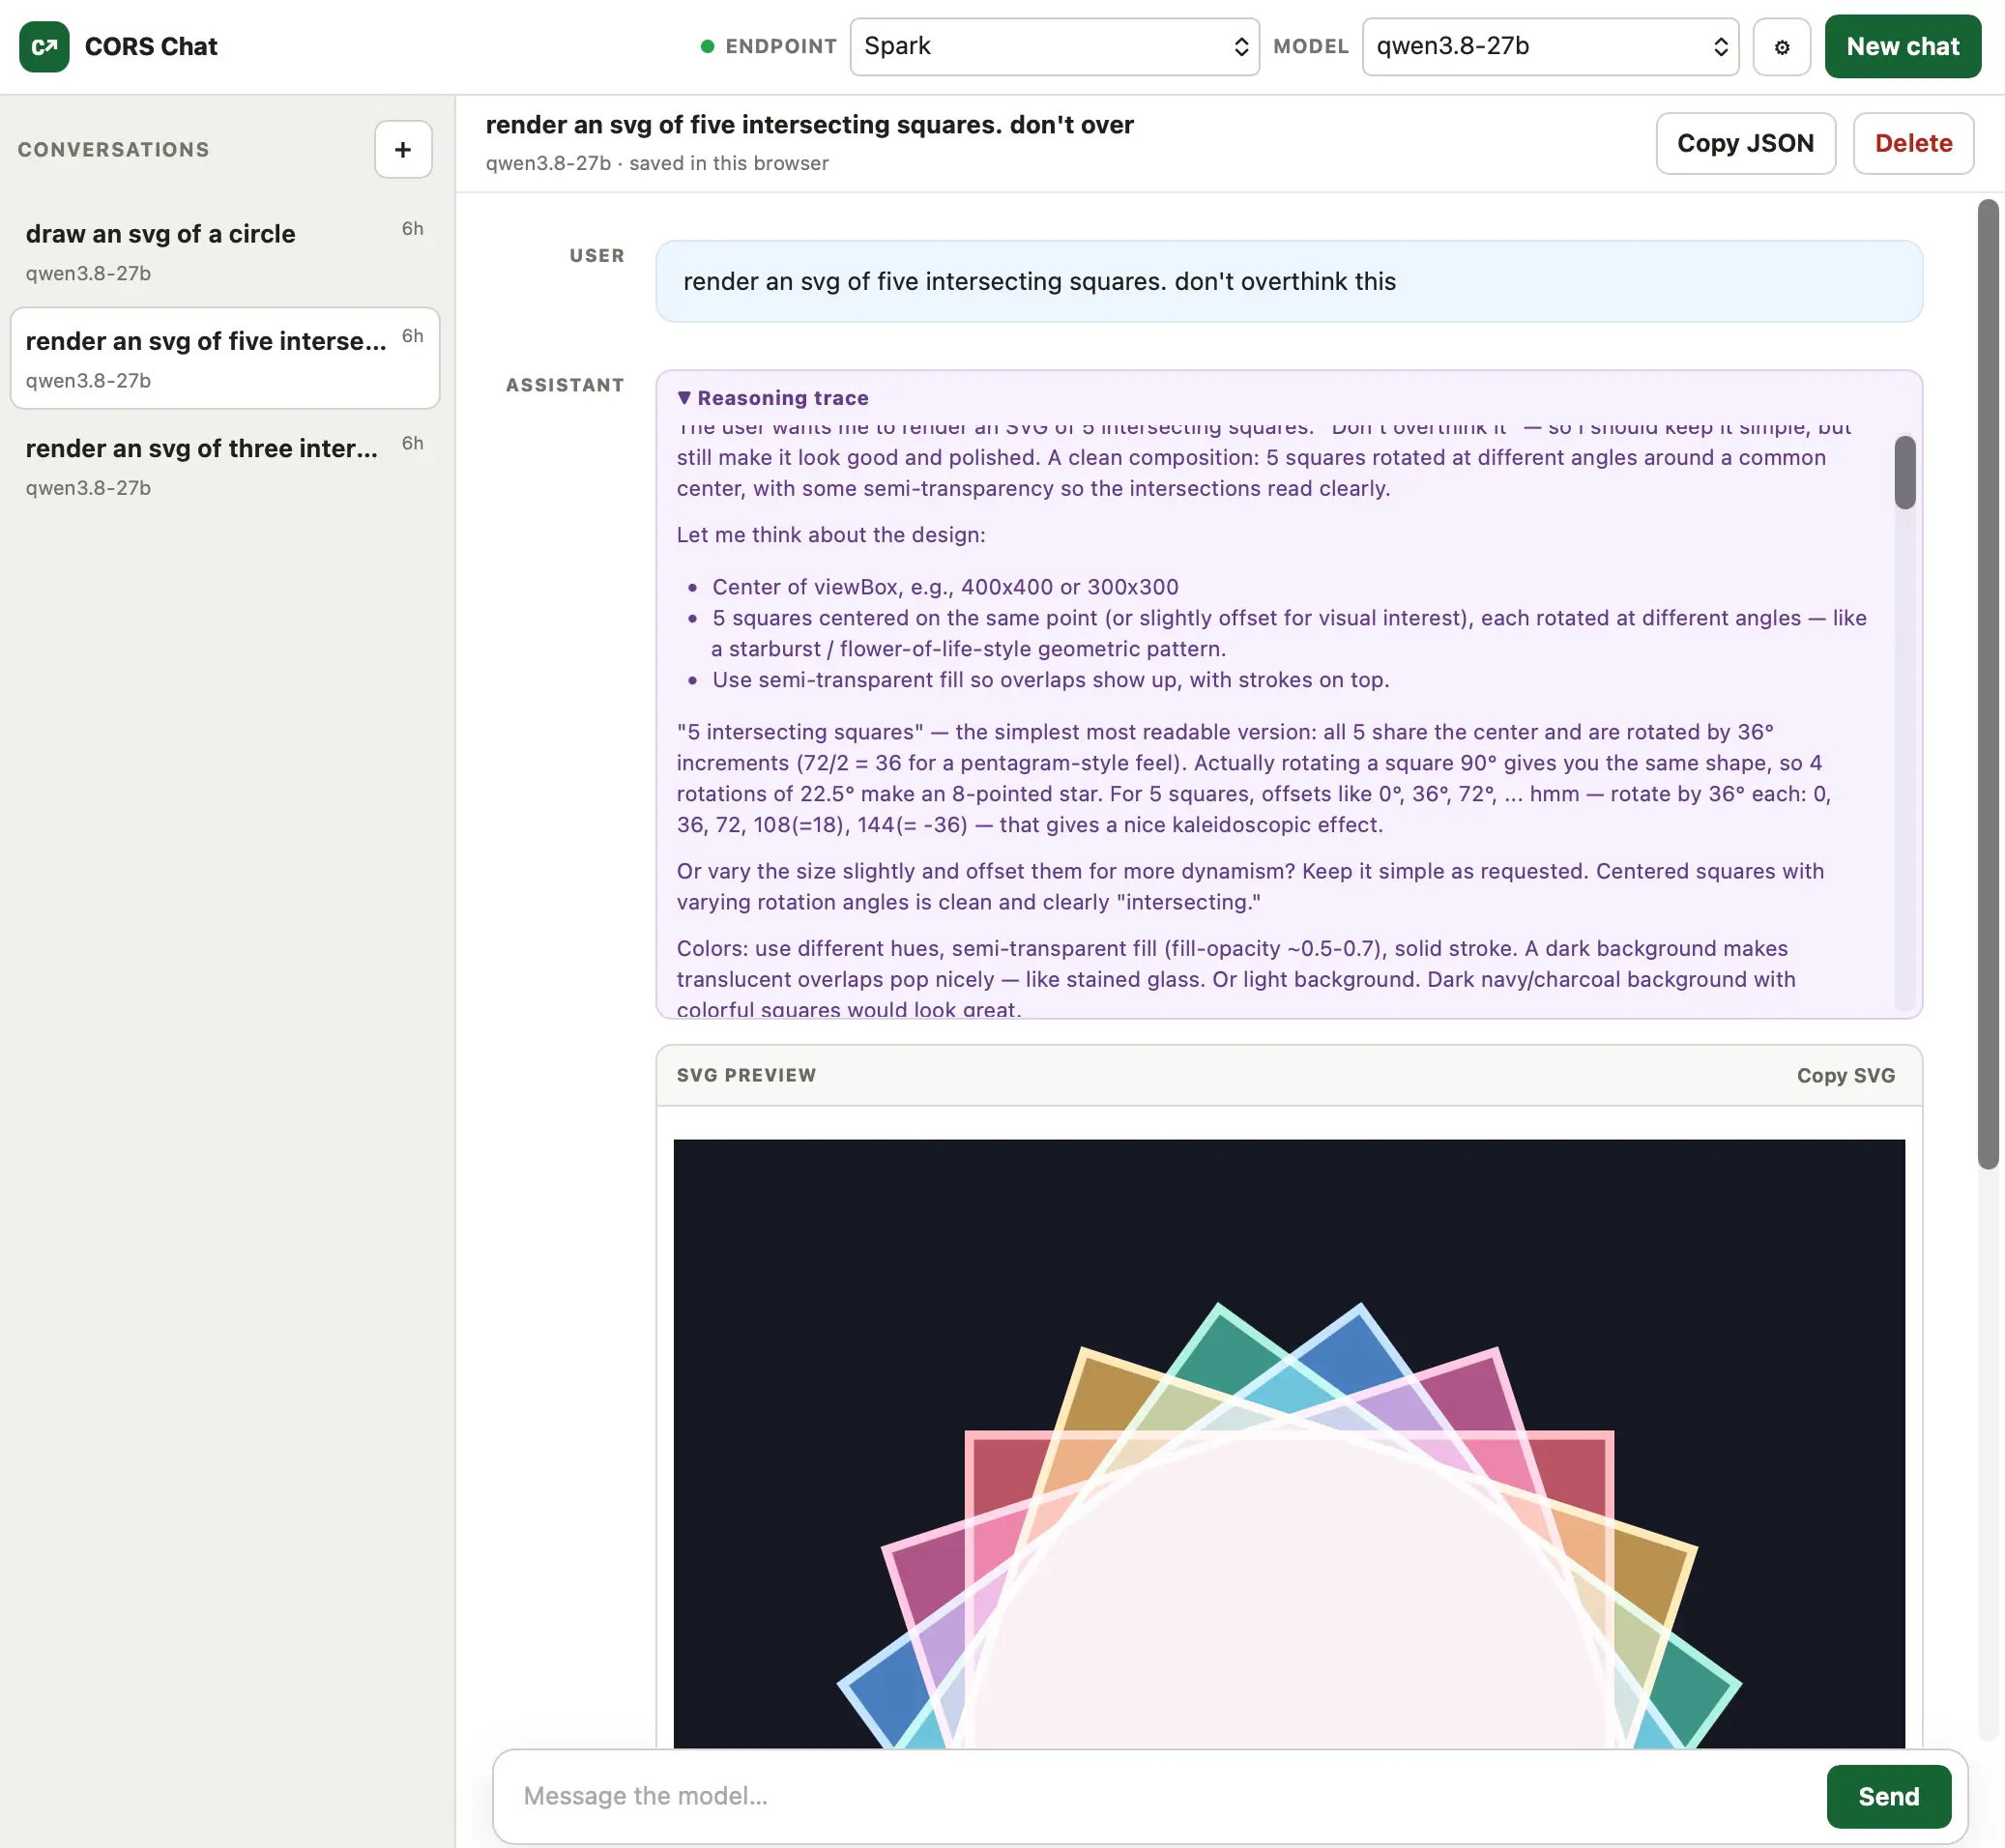
I built this today (with GPT-5.6-Sol xhigh) to help test Qwen 3.8 27B running in LM Studio on both my M5 MacBook Pro and an NVIDIA DGX Spark.
It provides a web UI for exercising an OpenAI-Responses-compatible chat endpoint. I've tried it against LM Studio with the --cors option and OpenRouter, and both work fine.
Conversations are persisted in the browser and can be exported as copy-pasted JSON. One fun detail is that it notices SVG images that are being generated and progressively renders them in the chat while the tokens are still streaming in.
Tags: svg, ai, generative-ai, llms, cors, openrouter, lm-studio
Related items
FeaturedDeepSeek V4 Doubles Token Share on OpenRouter, Driven by Agentic Workloads
DeepSeek V4 在 OpenRouter 上的代币份额翻倍,智能体工作负载成主要驱动力
The rapid adoption of DeepSeek V4 signals a strong market preference for high-performance, low-cost inference models, especially as agentic use cases reshape AI deployment.
91
FeaturedEnabling Two Settings Triples ARC-AGI-3 Benchmark Scores
启用两项设置使ARC-AGI-3基准测试分数提升三倍
This finding is crucial! It shows that model performance depends not only on training but also on inference-time configuration. For AI engineers and researchers, this is a must-know optimization direction. Teams deploying models on resource-constrained devices in particular could find a low-cost way to boost capabilities.
91
FeaturedGPT-5.6: Fusing Frontier Intelligence with Frontier Efficiency
GPT-5.6:前沿智能与前沿效率的融合
This news is worth watching as it marks a shift from pure parameter scaling to efficiency competition. For AI developers and business decision-makers, GPT-5.6 means higher performance at lower cost, especially for long-context or agentic tasks previously hindered by inference expenses. OpenAI's move may redefine what 'frontier' means.
91
FeaturedLFM2.5-Encoders: New Models for Fast Long-Context Inference on CPU
LFM2.5-Encoder:面向CPU快速长上下文推理的新模型
This blog post catches my eye because it directly solves the pain point of running long-context LLMs on CPU. For teams or individual developers without high-end GPUs, the LFM2.5-Encoder series offers a ready-to-use open-source solution. Highly recommended for those working on RAG, document search, or code analysis—now a standard server can handle million-token documents.
91
FeaturedGPT-Red: OpenAI Automates Red Teaming via Self-Play to Boost Model Robustness
GPT-Red:OpenAI通过自我对弈实现AI红队自动化,提升模型鲁棒性
GPT-Red marks a milestone from human to automated red-teaming—essential for safety engineers and alignment researchers. While reducing cost, it also raises ethical questions about automated attacks, worth pondering for everyone in AI governance.
91
FeaturedOpenAI Launches GPT-5.5 Bio Bug Bounty Program
OpenAI推出GPT-5.5生物漏洞赏金计划
This program deserves attention as it pioneers the extension of AI bug bounty to biosecurity, offering a new research direction for the security community and a practical training ground for AI risk governance. It is particularly important for model safety researchers, biosecurity experts, and practitioners concerned about dual-use AI risks.
91
FeaturedvLLM Introduces Native-Speed Transformers Modeling Backend for Enhanced Inference Performance
vLLM推出原生速度Transformers建模后端,大幅提升推理性能
This update is critical for AI engineering teams: eliminating format conversion speeds up model iteration, and 2-5x speedup directly reduces GPU costs. If you're building LLM online services or batch inference, this is practically a must-read technical update.
90
FeaturedGoogle DeepMind Introduces SL2T, a Sign Language-to-Text Model for Deaf Users
Google DeepMind 发布手语转文本模型 SL2T,助力聋人用户
This news matters not only as a technical breakthrough but also as a sign that AI is beginning to address the needs of marginalized groups. For developers, the architecture and technical approach of SL2T merit deep study; for accessibility advocates, it's a key case for advancing industry standards.