Google DeepMind Introduces Gemini 3.7 Flash, a Workhorse Model for Coding and Agents
Score
77发布了新模型点,但未提供技术细节,信息增量有限。
内容简洁,定位明确,但缺乏深度评测和性能数据。
对开发者和智能体应用者具有直接参考价值,影响工具选型。
刚发布的官方消息,时效性极强。
来源为Google DeepMind官方博客,信源高度权威。
Base 76.5 × T1 Source weight ×1 = 77
Curation line 60Selected
Why selected
The news is fresh and highly relevant to the AI community, with accurate positioning despite limited details.
AI commentary
「This news is critical for those following AI development tools, as the Flash series is known for cost-effectiveness and this 3.7 version strengthens coding and agent capabilities, meaning existing workflows could soon embrace a smarter assistant. For agent startup teams, this is a must-track model update.」
Quick overview
Google DeepMind has officially launched Gemini 3.7 Flash, its most intelligent workhorse model optimized for coding and agentic tasks. The model delivers efficient performance in code generation, debugging, and autonomous agent workflows, designed to balance speed and intelligence as a reliable daily tool for developers. This release further consolidates DeepMind's leadership in AI models and offers enterprises and developers a more powerful application foundation.
- Gemini 3.7 Flash is positioned as the most intelligent workhorse model, with a focus on coding and agent capabilities.
- The model is optimized for code generation, debugging, and autonomous agent tasks, emphasizing efficiency and responsiveness.
- This release marks DeepMind's further step in practical model deployment, serving the developer ecosystem.
Full text
Showing the source text; the full translation is being generated.
Introducing Gemini 3.7 Flash
Aug 13, 2026
|Our most intelligent workhorse model yet for coding and agents.
Tulsee Doshi
Senior Director, Product Management, on behalf of the Gemini team
Share
Your browser does not support the audio element.
Listen to article [[duration]] minutes This content is generated by Google AI. Generative AI is experimental Voice Speed Voice Speed 0.75X 1X 1.5X 2XToday, we’re building on the progress of our widely used Flash series by introducing Gemini 3.7 Flash, our most intelligent workhorse model yet for coding and agents.
This release comes just three weeks after Gemini 3.6 Flash, and is a direct result of developer feedback and algorithmic innovations that we look forward to bringing to future models. 3.7 Flash delivers substantial improvements across software engineering, knowledge work, and web development workflows — with an introductory price of half the original 3.6 Flash cost per million tokens.
Better intelligence for complex workflows
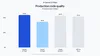
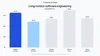
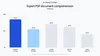
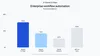
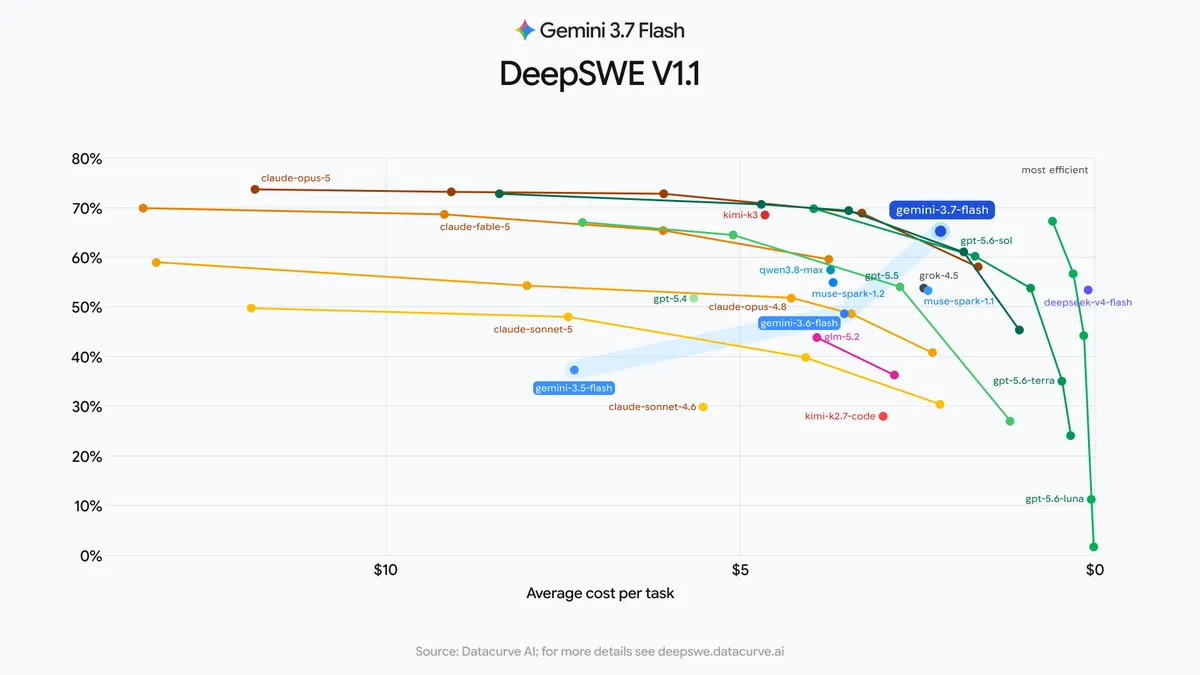
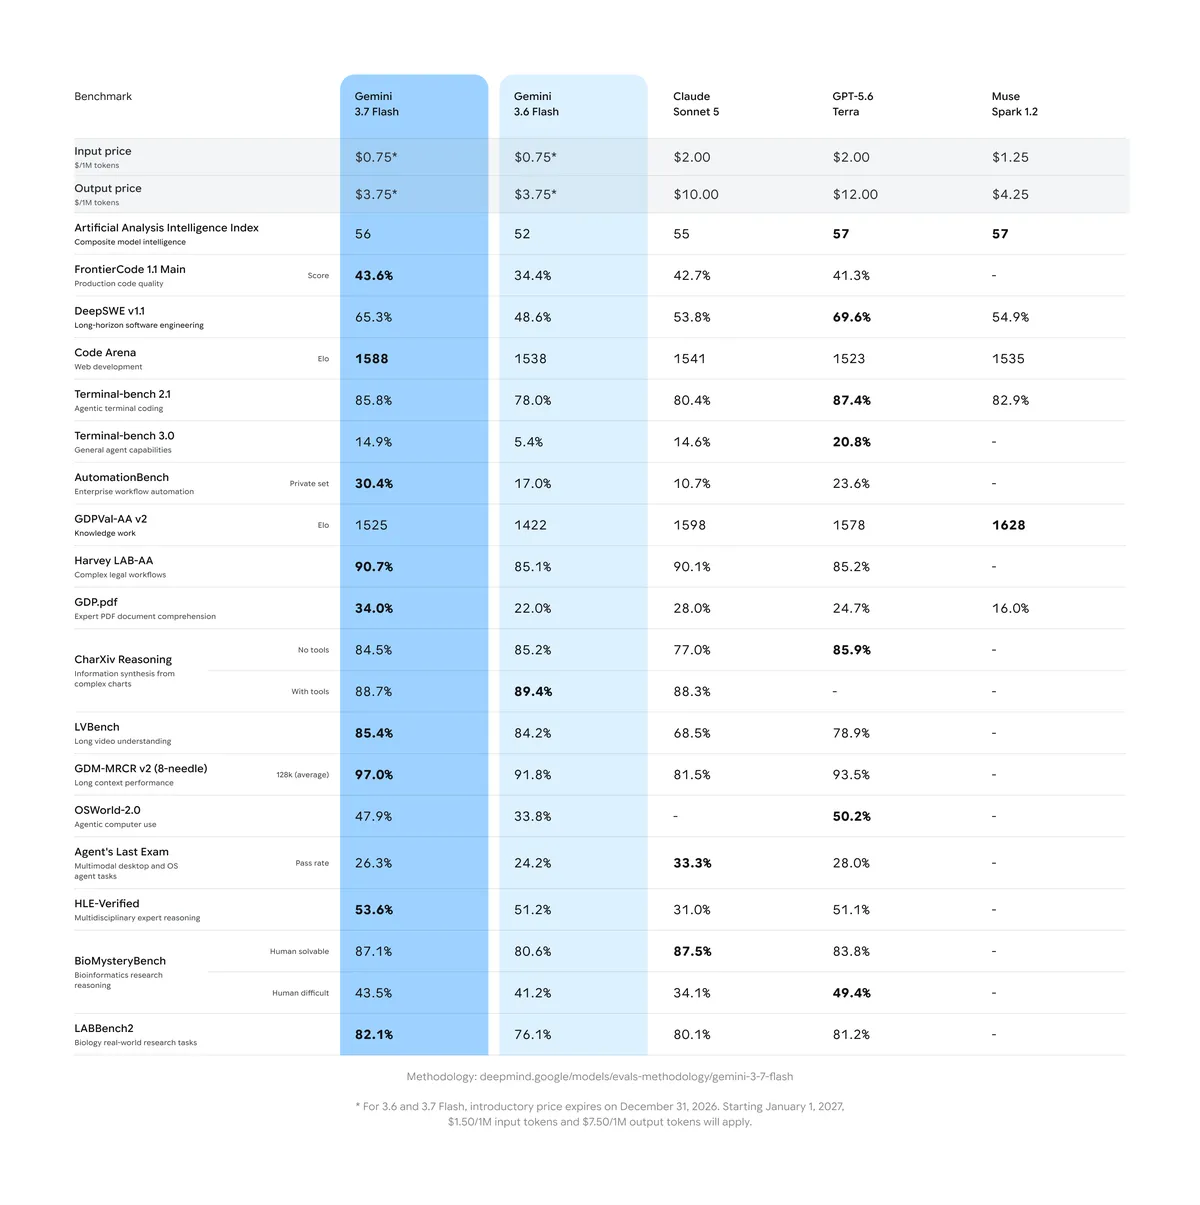
3.7 Flash shows strong gains over 3.6 Flash in coding tasks like debugging and issue resolution. It also achieves higher first-pass code accuracy and has improved performance in generating production-ready code as seen in FrontierCode 1.1 Main (43.6% vs 34.4%) and DeepSWE v1.1 (65.3% vs 49.0%).
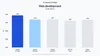
In web development, 3.7 Flash generates more functional layouts and feature-complete apps in fewer prompts. For UI generation, the model shows high design adherence and parity based on a reference input, whether it’s a screenshot, an image, or a full design system. It outperforms 3.6 Flash on Arena.ai’s WebDev Arena with an Elo score of 1588 vs 1538.
For knowledge-dense fields like finance, law, and biosciences, 3.7 Flash delivers improved reasoning and accuracy. It significantly outperforms 3.6 Flash on the GDP.pdf benchmark (34.0% vs 22.0%), an eval for testing a model’s ability to process complex documents. It also surpasses 3.6 Flash in AutomationBench, demonstrating it can more effectively complete real-world business workflows (30.4% vs 17.0%).
From a simple text prompt to a fully playable 3D game. We used Gemini 3.7 Flash combined with Nano Banana to dynamically generate characters, items, and textures in real-time.
Stunning, interactive landing pages generated in a single shot. We used Gemini 3.7 Flash to orchestrate sub-agents, using Gemini Omni to create smooth, interactive parallax components.
A robotics model getting trained with Gemini 3.7 Flash using multimodal understanding in a 3 agent graph loop that helps the robot learn faster.
From a static PDF to an interactive data story. Watch how complex annual reports are transformed into engaging web experiences complete with live charts and aggregated insights.
Better developer experience and price
Gemini 3.7 Flash delivers a noticeably improved developer experience over 3.6 Flash. It better adapts to roadblocks, clarifies intent when needed, and follows instructions with greater fidelity. It thinks more diligently, putting in more effort into multi-step planning and tool calls. A more disciplined execution means less manual oversight and fewer retries across engineering workflows.
3.7 Flash is available through the end of the year at an introductory price 1 of $0.75/1M input tokens and $3.75/1M output tokens. This price combined with the enhanced model performance enables developers and customers to scale production-ready agents cost effectively.
Early customer feedback is highlighting 3.7 Flash’s performance and precision, achieving results that are significantly better than 3.6 Flash at a low cost.
Improving Gemini Spark with 3.7 Flash
Gemini Spark, available to Google AI Pro and Ultra subscribers in over 160 countries, will be using Gemini 3.7 Flash starting today. We launched Spark at I/O as your personal AI agent that runs 24/7, taking action on your behalf while under your direction. This model update makes Spark more efficient for knowledge work with improved tool use for Google Workspace apps, delivering improved accuracy and output quality for complex, multi-skill workflows.
With 3.7 Flash, Gemini Spark can turn ideas into action more efficiently by consolidating files, drafting emails, and updating status documents.
Built with safety in mind
We continually work to improve the coverage and robustness of Frontier Safety safeguards. Gemini 3.7 Flash is shipping with updated safeguards against misuse in the domains of Chemical, Biological, Radiological, and Nuclear (CBRN) and cyber offense, while enabling beneficial use cases, in accordance with our approach to bioresilience and our cyber program.
For more information, see the 3.7 Flash model card.
Try it today
- Developers: Explore agent-first workflows in Google Antigravity or start building today in the Gemini API via Google AI Studio and Android Studio. Get started with our developer guide.
- Enterprises: Access 3.7 Flash in Gemini Enterprise Agent Platform and the Gemini Enterprise app.
- Individuals: Available via Spark, your 24/7 personal agent in the Gemini app for Google AI Pro and Ultra subscribers in supported countries.
Detailed benchmarks
Get the latest news from Google in your inbox
Sign up for our newsletters with product updates, event information, special offers, and more.
Done. Just one step more.
Check your inbox to confirm your subscription.
You can also subscribe with a different email address.
Your information will be used in accordance with Google's privacy policy. You may opt out at any time.
POSTED IN:Related items
FeaturedDeepSeek V4 Doubles Token Share on OpenRouter, Driven by Agentic Workloads
DeepSeek V4 在 OpenRouter 上的代币份额翻倍,智能体工作负载成主要驱动力
The rapid adoption of DeepSeek V4 signals a strong market preference for high-performance, low-cost inference models, especially as agentic use cases reshape AI deployment.
91
FeaturedEnabling Two Settings Triples ARC-AGI-3 Benchmark Scores
启用两项设置使ARC-AGI-3基准测试分数提升三倍
This finding is crucial! It shows that model performance depends not only on training but also on inference-time configuration. For AI engineers and researchers, this is a must-know optimization direction. Teams deploying models on resource-constrained devices in particular could find a low-cost way to boost capabilities.
91
FeaturedGPT-5.6: Fusing Frontier Intelligence with Frontier Efficiency
GPT-5.6:前沿智能与前沿效率的融合
This news is worth watching as it marks a shift from pure parameter scaling to efficiency competition. For AI developers and business decision-makers, GPT-5.6 means higher performance at lower cost, especially for long-context or agentic tasks previously hindered by inference expenses. OpenAI's move may redefine what 'frontier' means.
91
FeaturedLFM2.5-Encoders: New Models for Fast Long-Context Inference on CPU
LFM2.5-Encoder:面向CPU快速长上下文推理的新模型
This blog post catches my eye because it directly solves the pain point of running long-context LLMs on CPU. For teams or individual developers without high-end GPUs, the LFM2.5-Encoder series offers a ready-to-use open-source solution. Highly recommended for those working on RAG, document search, or code analysis—now a standard server can handle million-token documents.
91
FeaturedGPT-Red: OpenAI Automates Red Teaming via Self-Play to Boost Model Robustness
GPT-Red:OpenAI通过自我对弈实现AI红队自动化,提升模型鲁棒性
GPT-Red marks a milestone from human to automated red-teaming—essential for safety engineers and alignment researchers. While reducing cost, it also raises ethical questions about automated attacks, worth pondering for everyone in AI governance.
91
FeaturedOpenAI Launches GPT-5.5 Bio Bug Bounty Program
OpenAI推出GPT-5.5生物漏洞赏金计划
This program deserves attention as it pioneers the extension of AI bug bounty to biosecurity, offering a new research direction for the security community and a practical training ground for AI risk governance. It is particularly important for model safety researchers, biosecurity experts, and practitioners concerned about dual-use AI risks.
91
FeaturedvLLM Introduces Native-Speed Transformers Modeling Backend for Enhanced Inference Performance
vLLM推出原生速度Transformers建模后端,大幅提升推理性能
This update is critical for AI engineering teams: eliminating format conversion speeds up model iteration, and 2-5x speedup directly reduces GPU costs. If you're building LLM online services or batch inference, this is practically a must-read technical update.
90
FeaturedGoogle DeepMind Introduces SL2T, a Sign Language-to-Text Model for Deaf Users
Google DeepMind 发布手语转文本模型 SL2T,助力聋人用户
This news matters not only as a technical breakthrough but also as a sign that AI is beginning to address the needs of marginalized groups. For developers, the architecture and technical approach of SL2T merit deep study; for accessibility advocates, it's a key case for advancing industry standards.