Mistral AI 发布 Leanstral 1.5:为企业打造开放模型驱动的AI平台
评分
63精选理由
该发布标志着Mistral AI在开放模型企业化方向的重要进展,结合多模态与自主代理,具有较高的实用价值与行业影响。
AI 点评
「Leanstral 1.5 将开放模型与企业级需求深度结合,可能重塑企业AI部署的效率和成本结构。」
速览
Mistral AI 推出 Leanstral 1.5,一个基于开放模型的企业级AI平台,支持自定义、微调及部署AI助手、自主代理和多模态AI。该版本强调“推理丰裕”,旨在通过开源生态降低企业AI应用门槛,提供更强的可控性和数据安全。
- 基于开放模型的企业级AI平台,支持定制化与微调
- 集成AI助手、自主代理和多模态AI能力
- 强调“推理丰裕”,降低企业AI使用门槛
- 注重数据安全与可控性,适合敏感业务场景
正文
Research
Leanstral 1.5: Proof Abundance for All
July 2, 2026
By Leanstral Team at Mistral AI
Back to Blog
6 min read
Share this post Copy url to clipboard Copied
Thinking
Summary
Leanstral 1.5, a free Apache-2.0 licensed model with 6B active parameters, delivers a major performance upgrade in formal verification, saturating miniF2F, solving 587/672 PutnamBench problems, and achieving state-of-the-art results on FATE-H (87%) and FATE-X (34%). Trained through mid-training, supervised fine-tuning, and reinforcement learning with CISPO, it excels in agentic proof engineering and real-world code verification, uncovering 5 previously unknown bugs across 57 repositories tested. Fully open-sourced and available via Hugging Face and a free API, Leanstral 1.5 is now accessible for practical proof engineering in Lean 4.
Since its launch, Leanstral has offered an open, practical approach to proof engineering in Lean 4. Today, we are releasing Leanstral 1.5, a free Apache-2.0 licensed model with 119B total and only 6B active parameters, delivering a performance upgrade that makes formal verification more powerful and accessible than ever.
Leanstral 1.5 saturates miniF2F, solves 587/672 PutnamBench problems, and achieves a new state-of-the-art of %87 on FATE-H and 34% on FATE-X. Beyond benchmarks, it verifies complex code properties and uncovers previously unknown bugs in open-source repositories—proving that rigorous formal methods can be both effective and practical for real-world use.
Training Leanstral
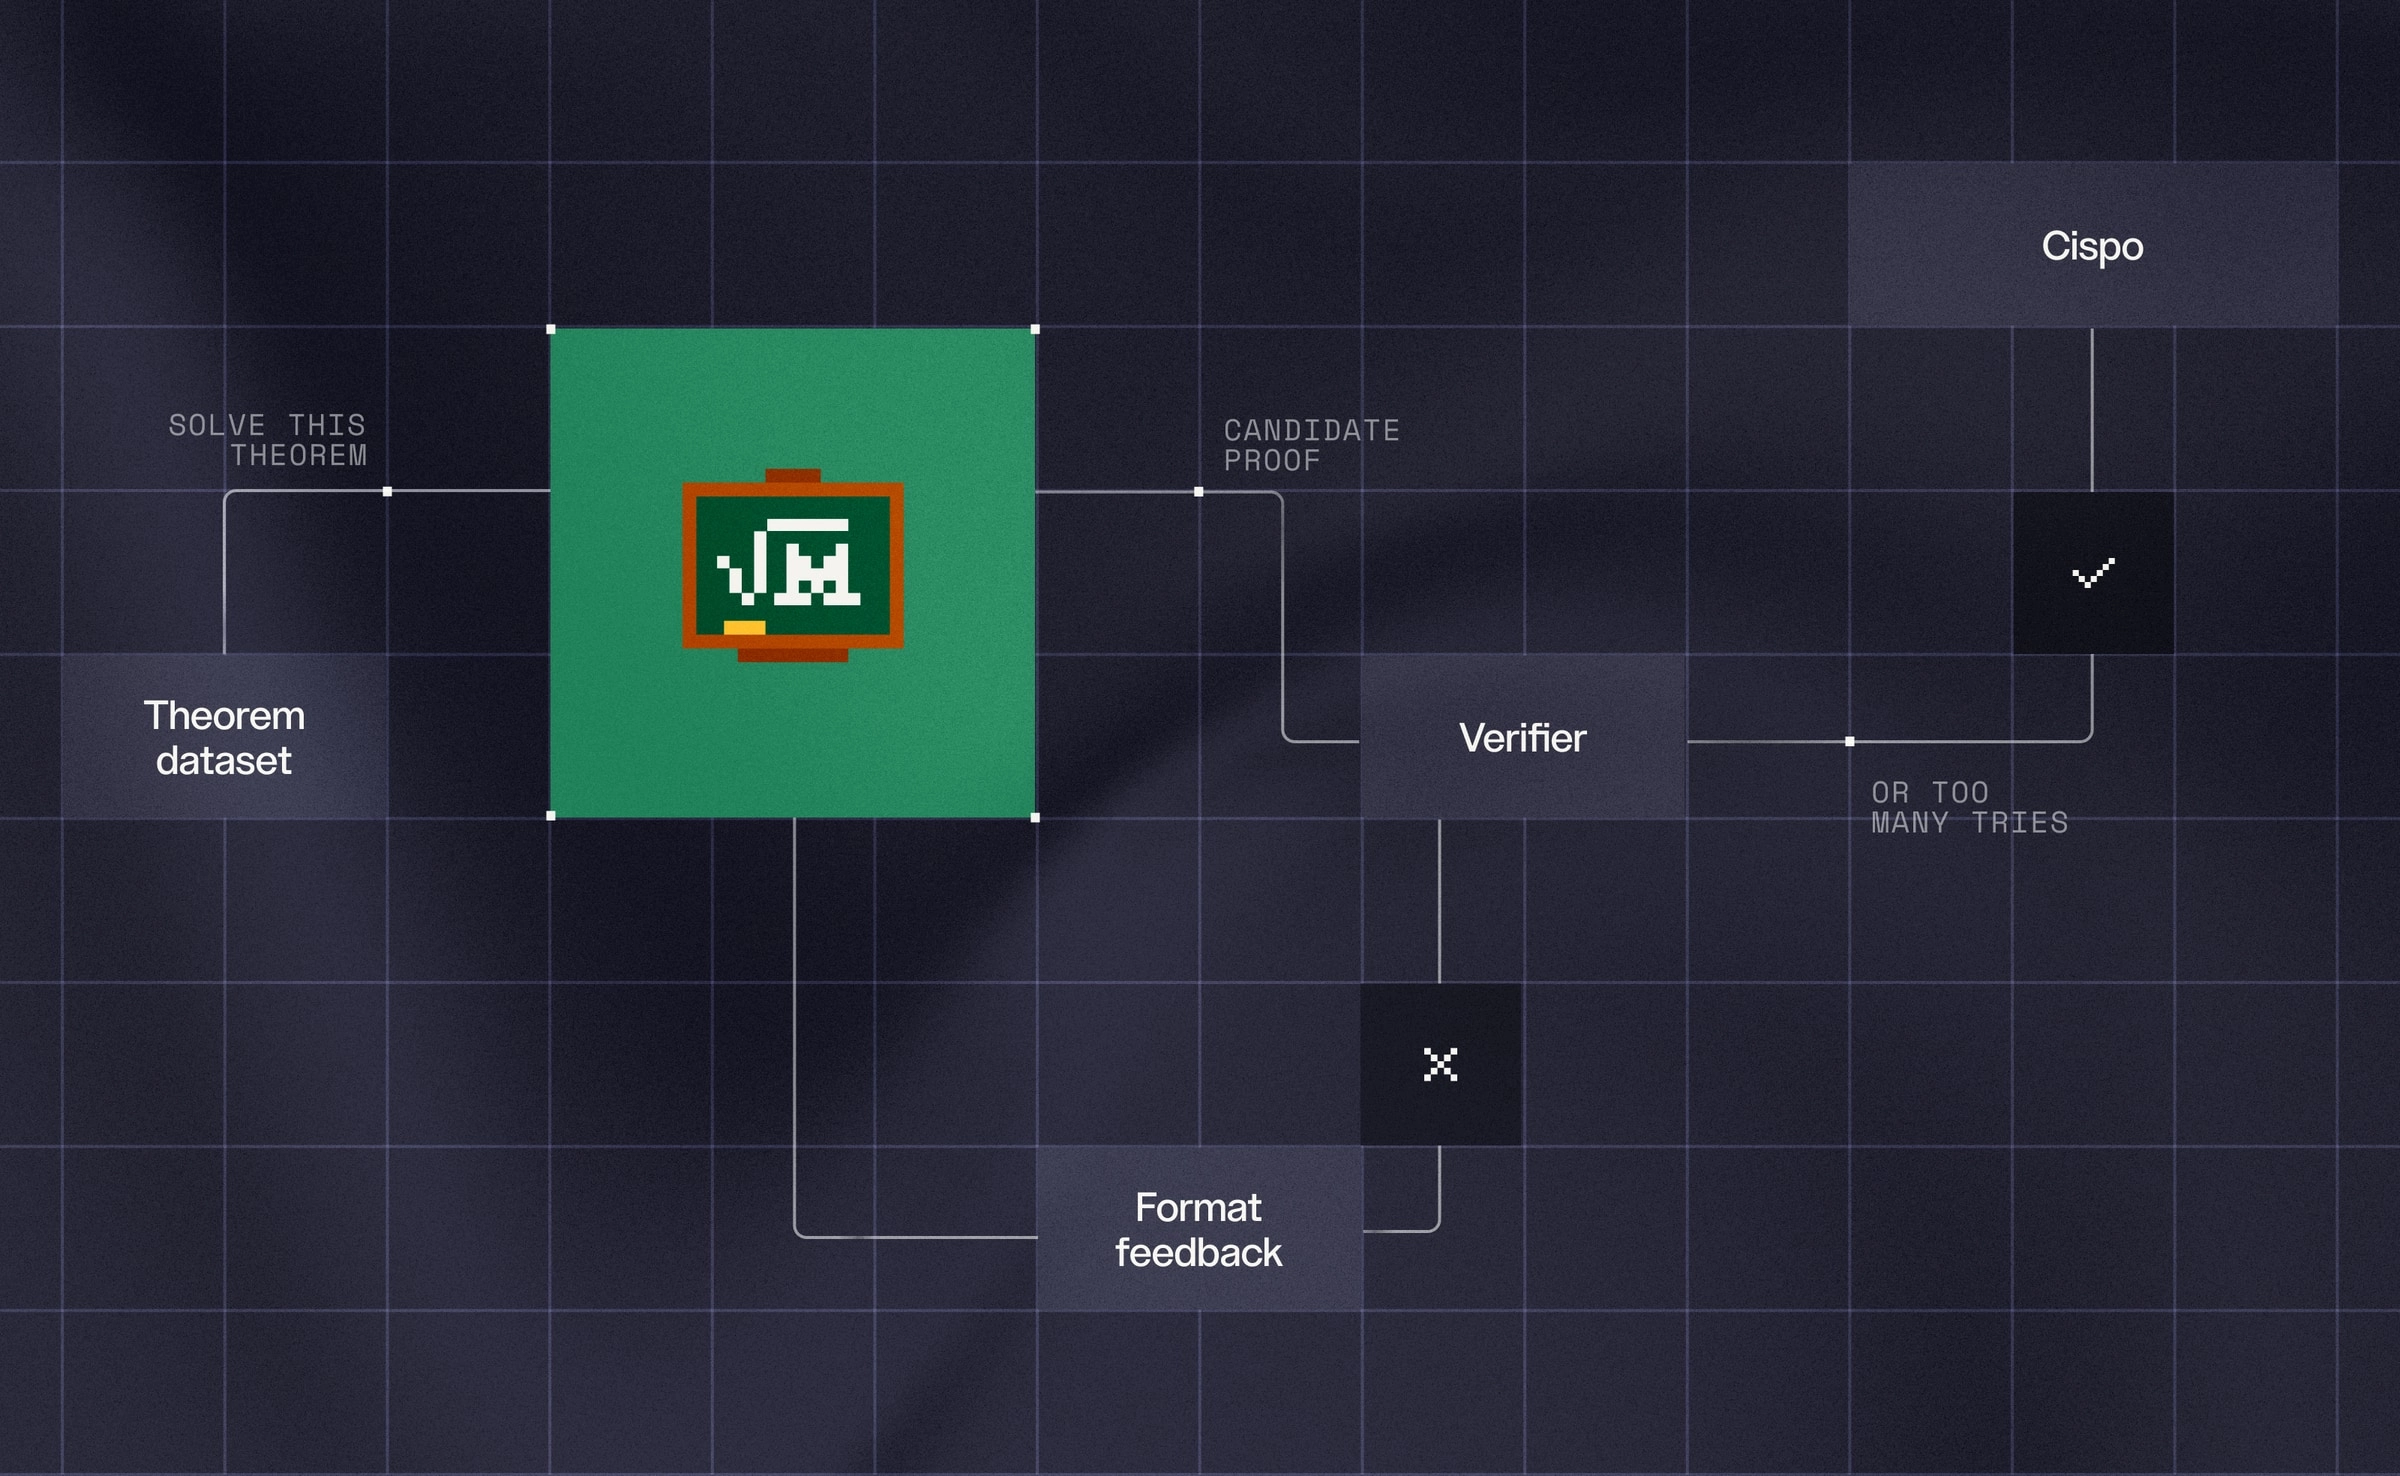
Leanstral 1.5 goes through a three-stage process: mid-training, supervised fine-tuning, and reinforcement learning with CISPO. Leanstral 1.5 leverages extensive training on two RL environments:
In the multiturn environment, the model is given a theorem statement and must either prove or disprove it. The model submits a proof, receives Lean compiler feedback, and refines its approach with each attempt. If the proof compiles it succeeds; otherwise the loop continues until the model either solves the problem or exhausts its budget.
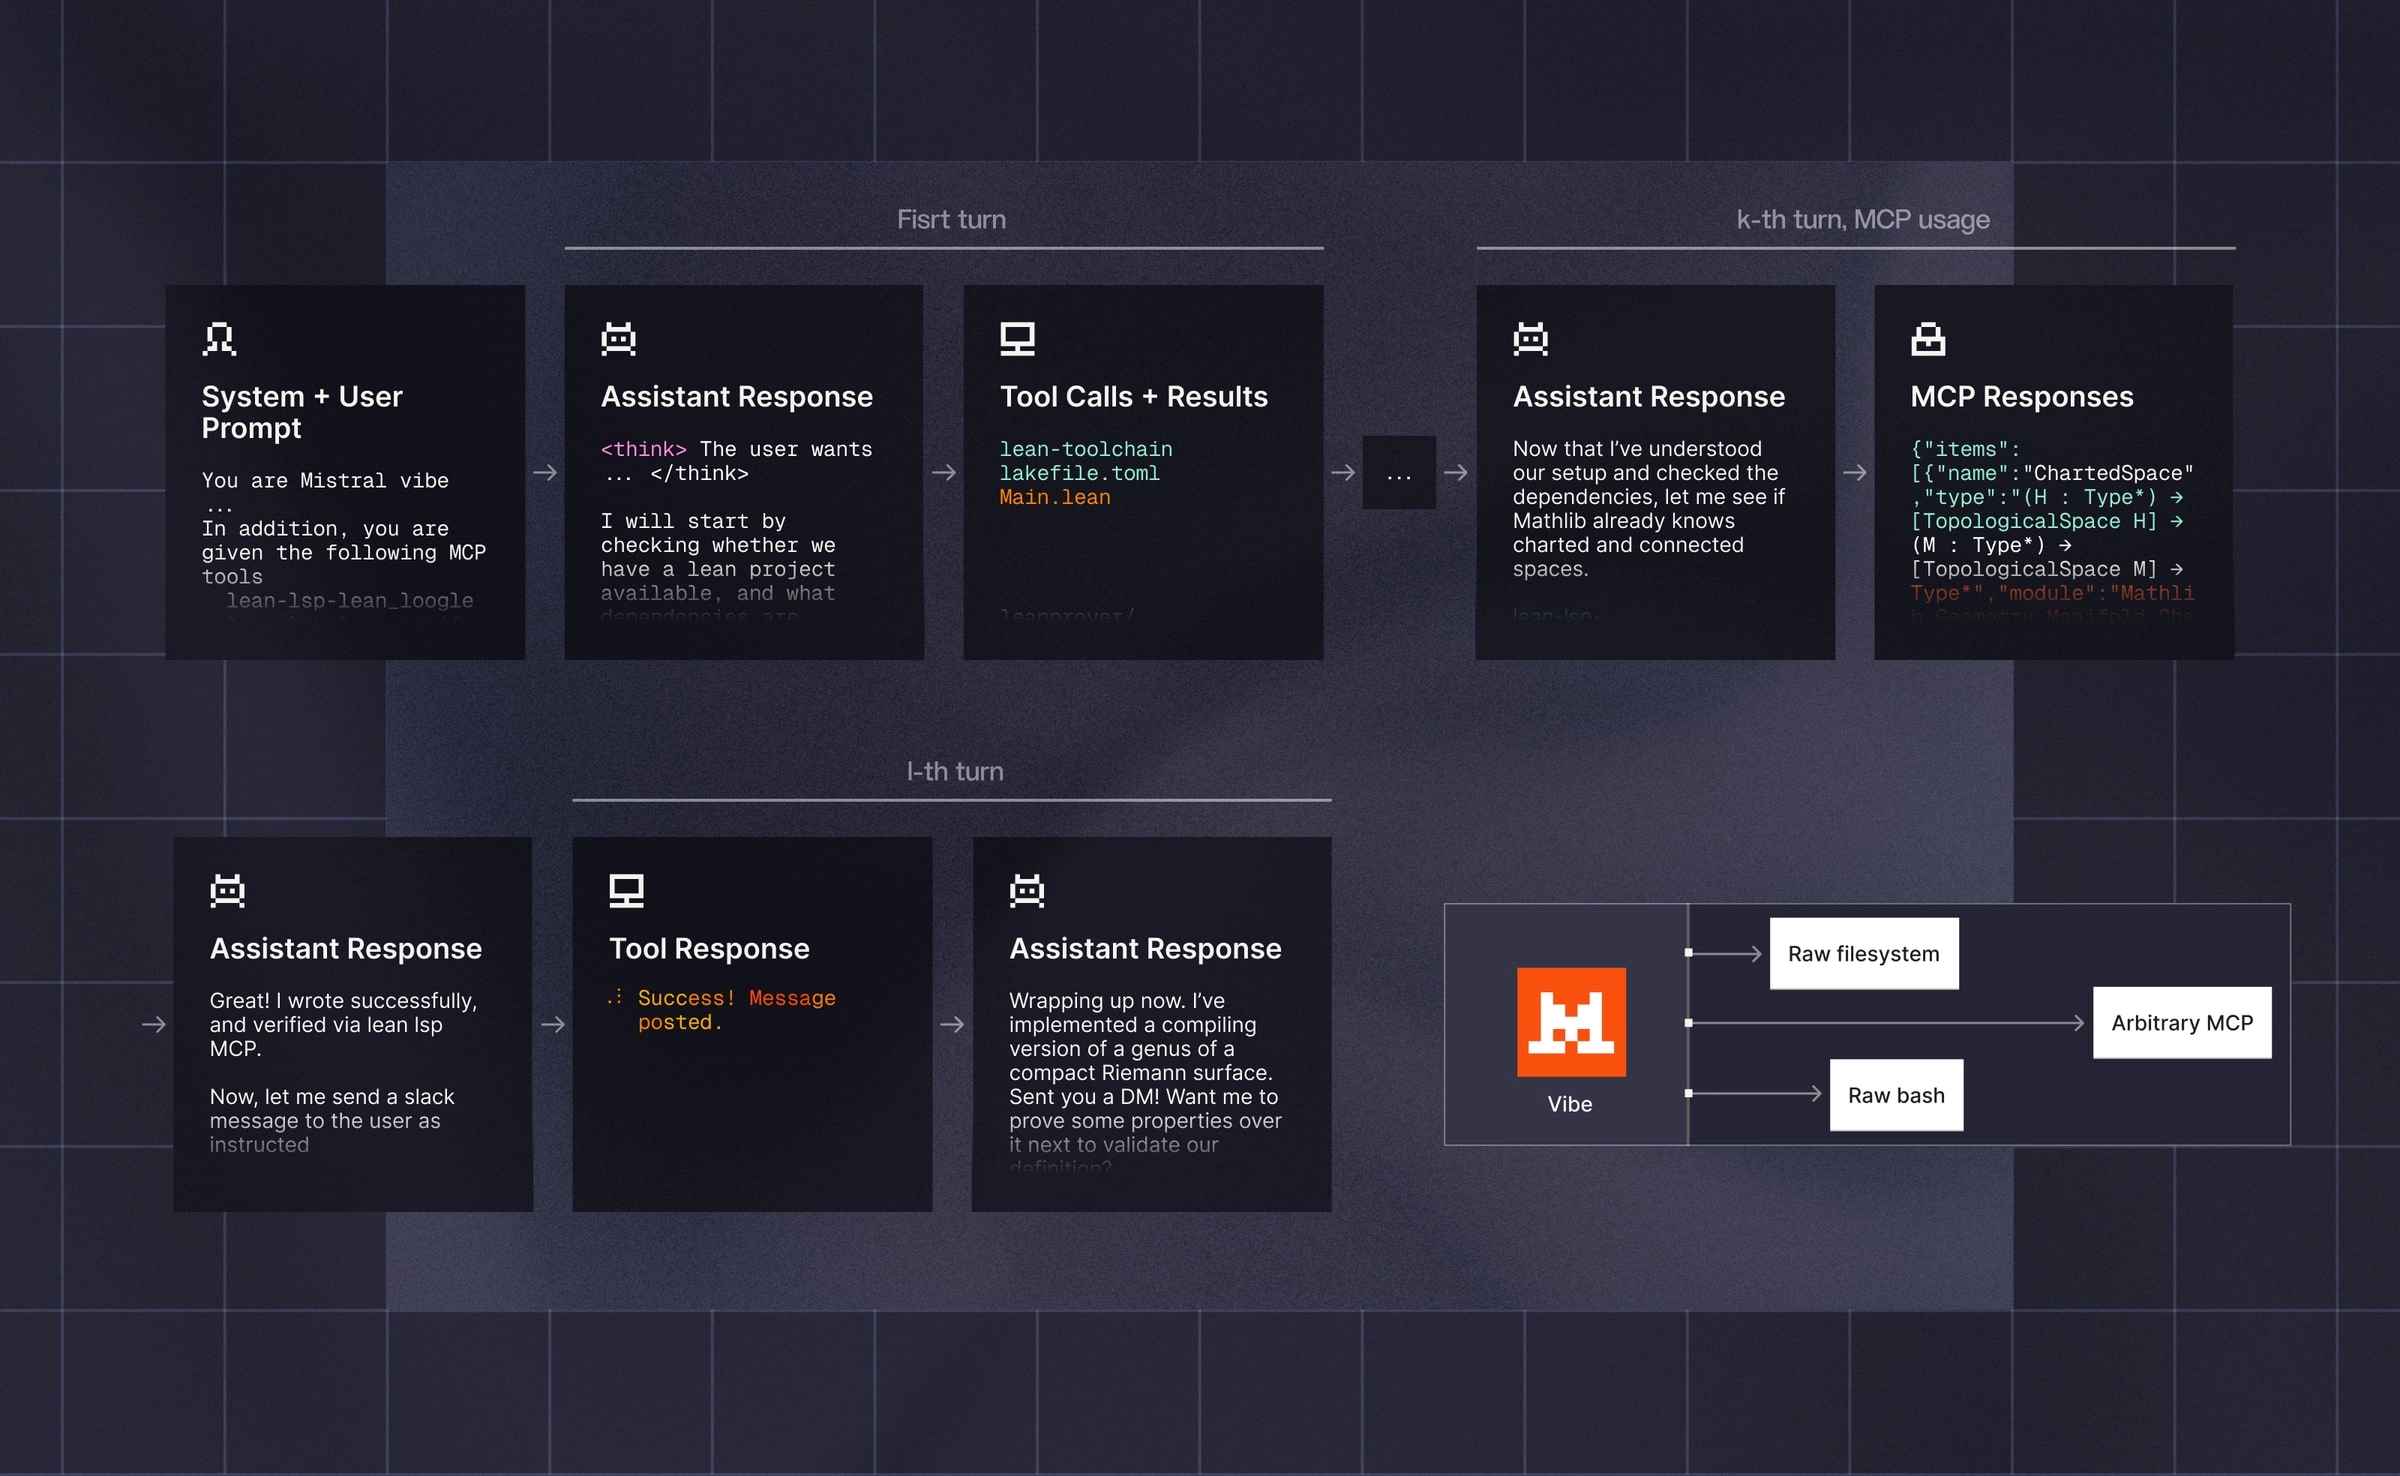
In the code agent environment, Leanstral operates like a developer in a raw filesystem: it edits files, runs bash commands, and uses the Lean language server to inspect goals, errors, and type information in real time. This allows it to tackle long-horizon tasks like completing partial proofs in a repository, building auxiliary lemmas, and persisting through multiple rounds of context compaction. The model learns to navigate the full proof-engineering workflow and is finally verified by our fork of SafeVerify for correctness given a list of target theorems.
Evaluation
We evaluate Leanstral on the following benchmarks:
miniF2F is a cross-system benchmark for formal mathematics, ranging from elementary problems to IMO-level challenges, testing diverse proof abilities across algebra, combinatorics, and number theory.
PutnamBench consists of 672 problems from the Putnam Mathematical Competition, requiring deep reasoning and long proof chains to solve challenging mathematical problems.
FATE-H and FATE-X are abstract algebra benchmarks for graduate and PhD-level problems, respectively, testing advanced reasoning in areas like group theory, ring theory, and module theory.
FLTEval is based on real pull requests from the Fermat’s Last Theorem repository, testing practical proof engineering with real-world complexity.
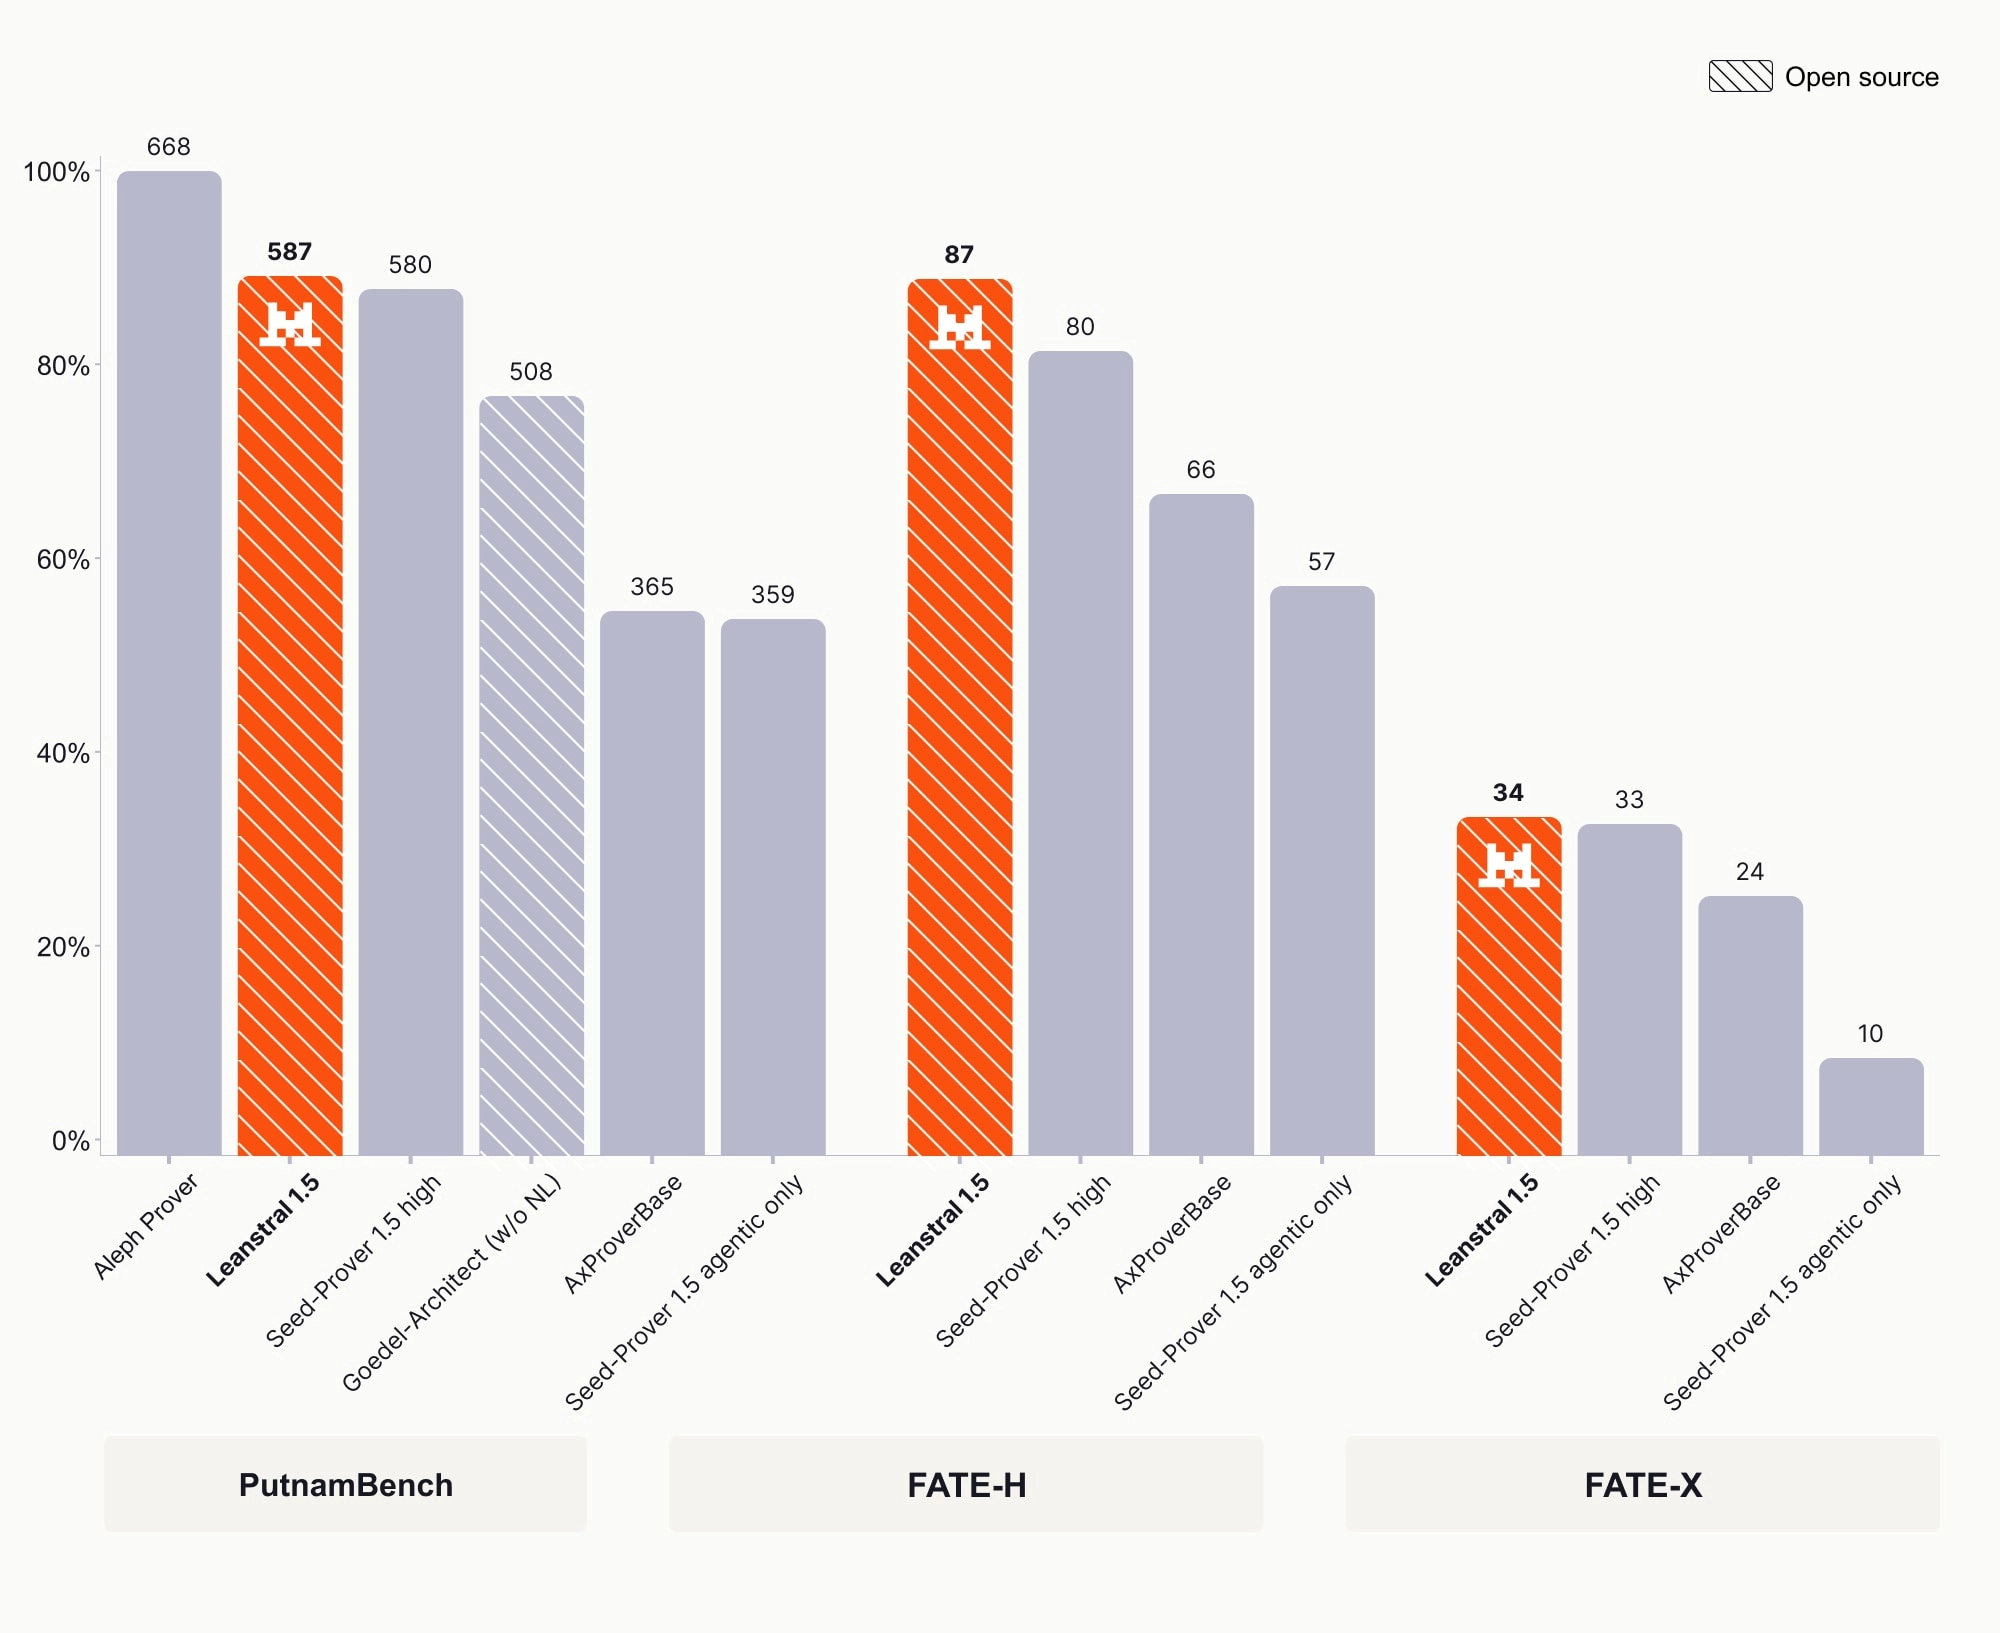
We saturate miniF2F completely, reaching 100% on both the validation and test sets. On PutnamBench and FATE-H/X, we compare Leanstral 1.5 against Goedel-Architect without natural-language guidance, Seed-Prover 1.5 at its high setting, and AxProverBase. Leanstral reaches a new state-of-the-art on FATE-H/X, solving 87 and 34 problems respectively. On PutnamBench, it edges out Seed-Prover 1.5 high by 7 problems at far lower cost: about $4 per problem, against an estimated $300 or more for Seed-Prover, whose high setting runs with a budget of 10 H20-days per problem. The only provers ranked higher operate under different conditions—some receive natural-language proof guidance, others cost far more to run, like Aleph Prover at $54–68 per problem.
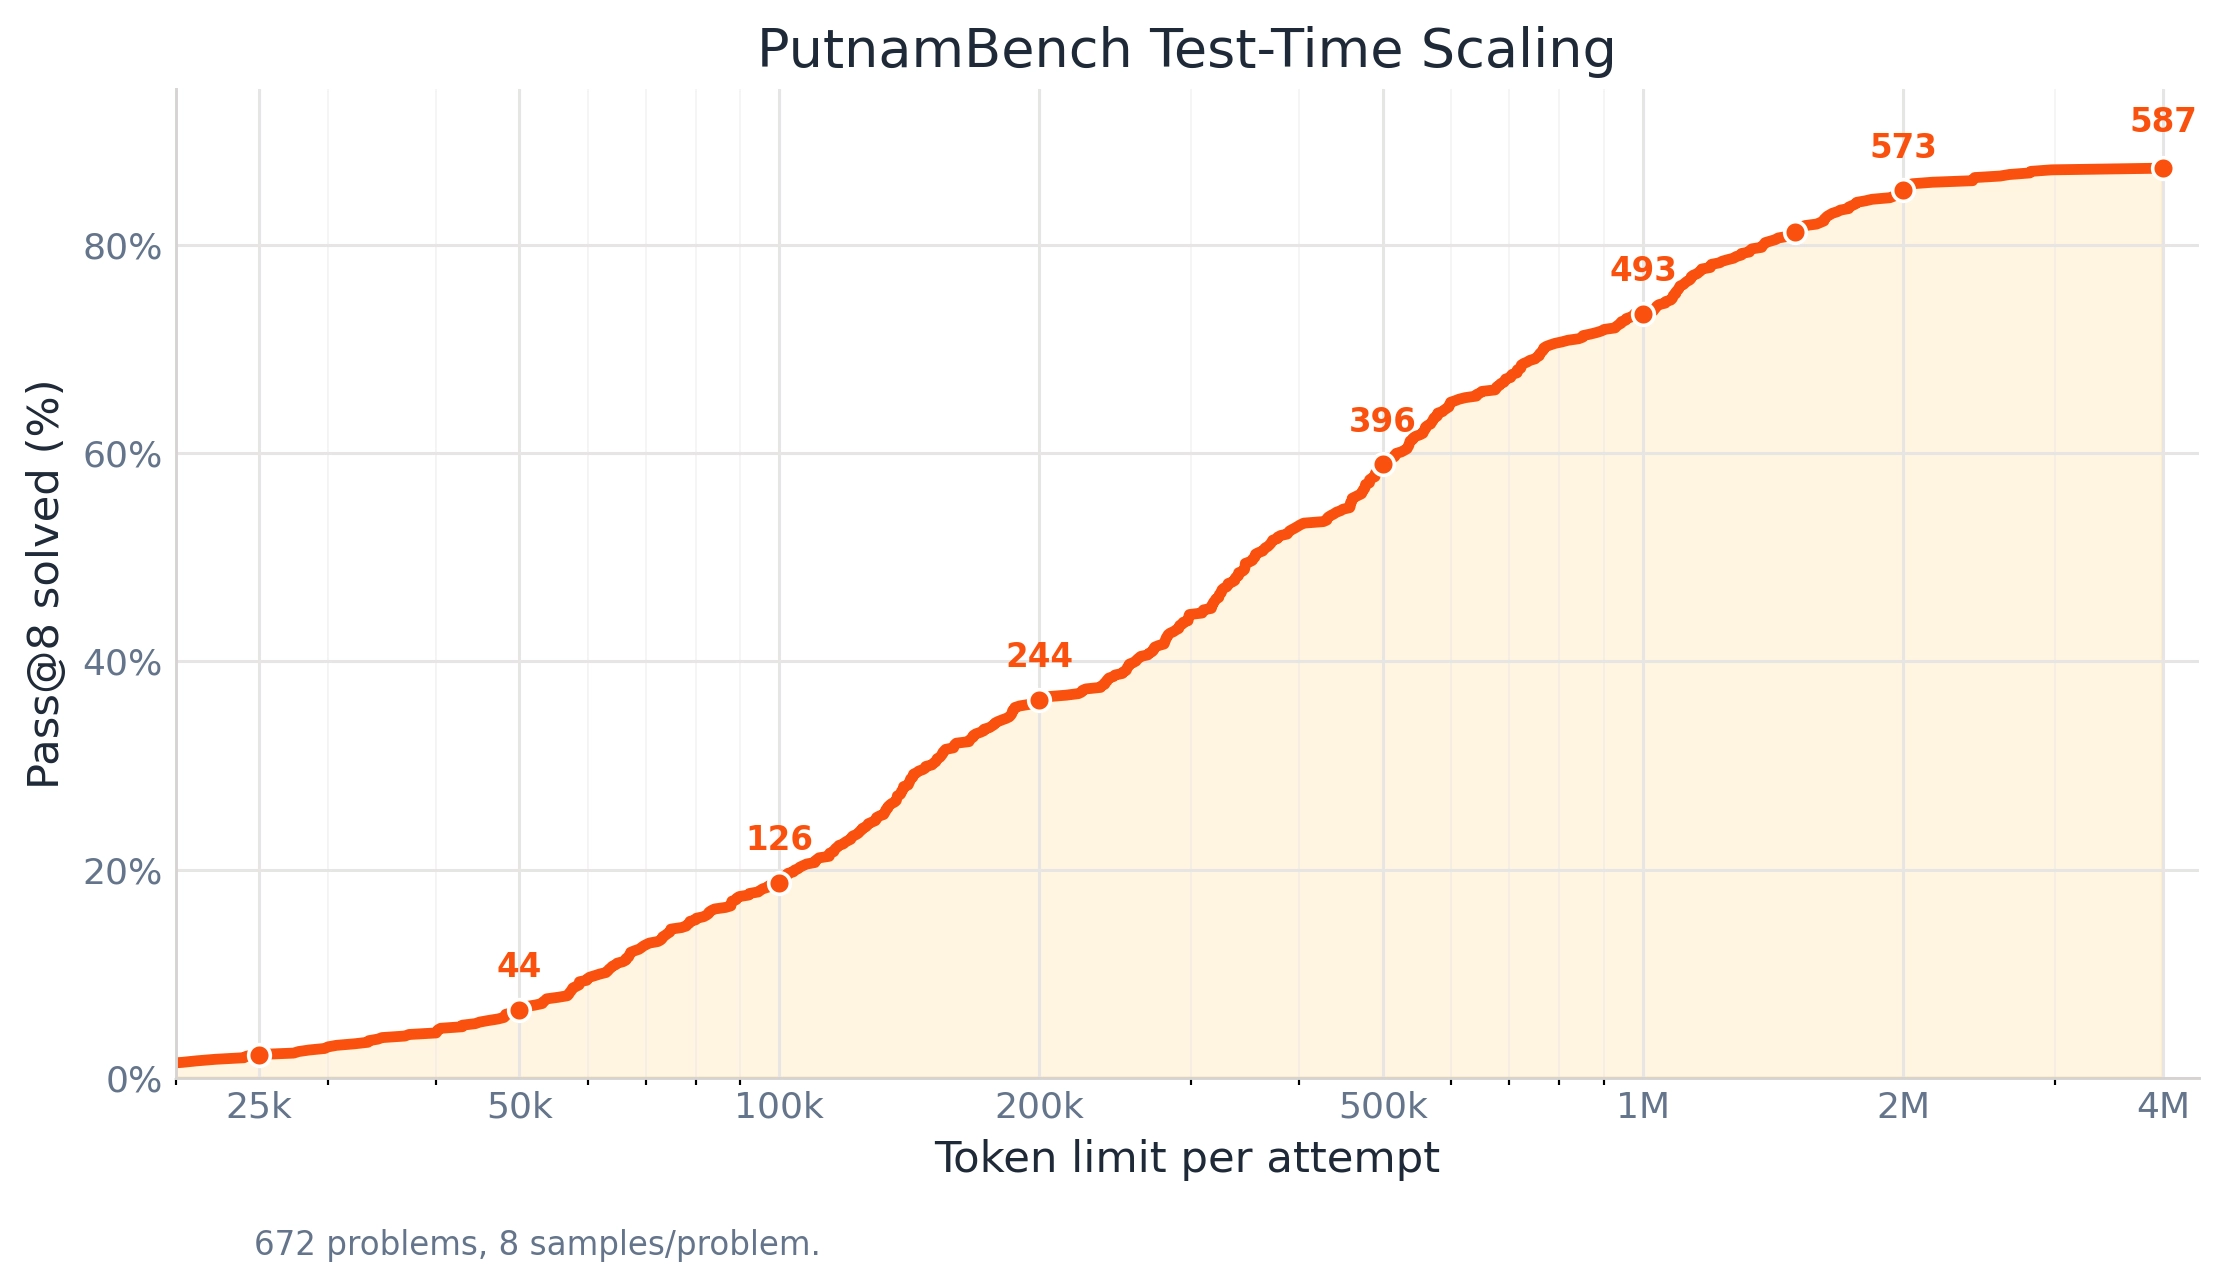
Leanstral 1.5 shows the strongest test-time scaling we have seen from a formal-reasoning model. The figure below tracks Pass@8 on PutnamBench as we raise the token budget per attempt from 25k to 4M: performance climbs smoothly and monotonically the whole way, from 44 problems solved at 50k to 244 at 200k, 493 at 1M, and 587 at 4M. Rather than giving up when a proof runs long, Leanstral keeps reasoning, editing files, and revising across millions of tokens, turning that budget directly into solved problems—the same behavior behind the AVL-tree proof below, which ran for over 2.7 million tokens across 22 compactions.
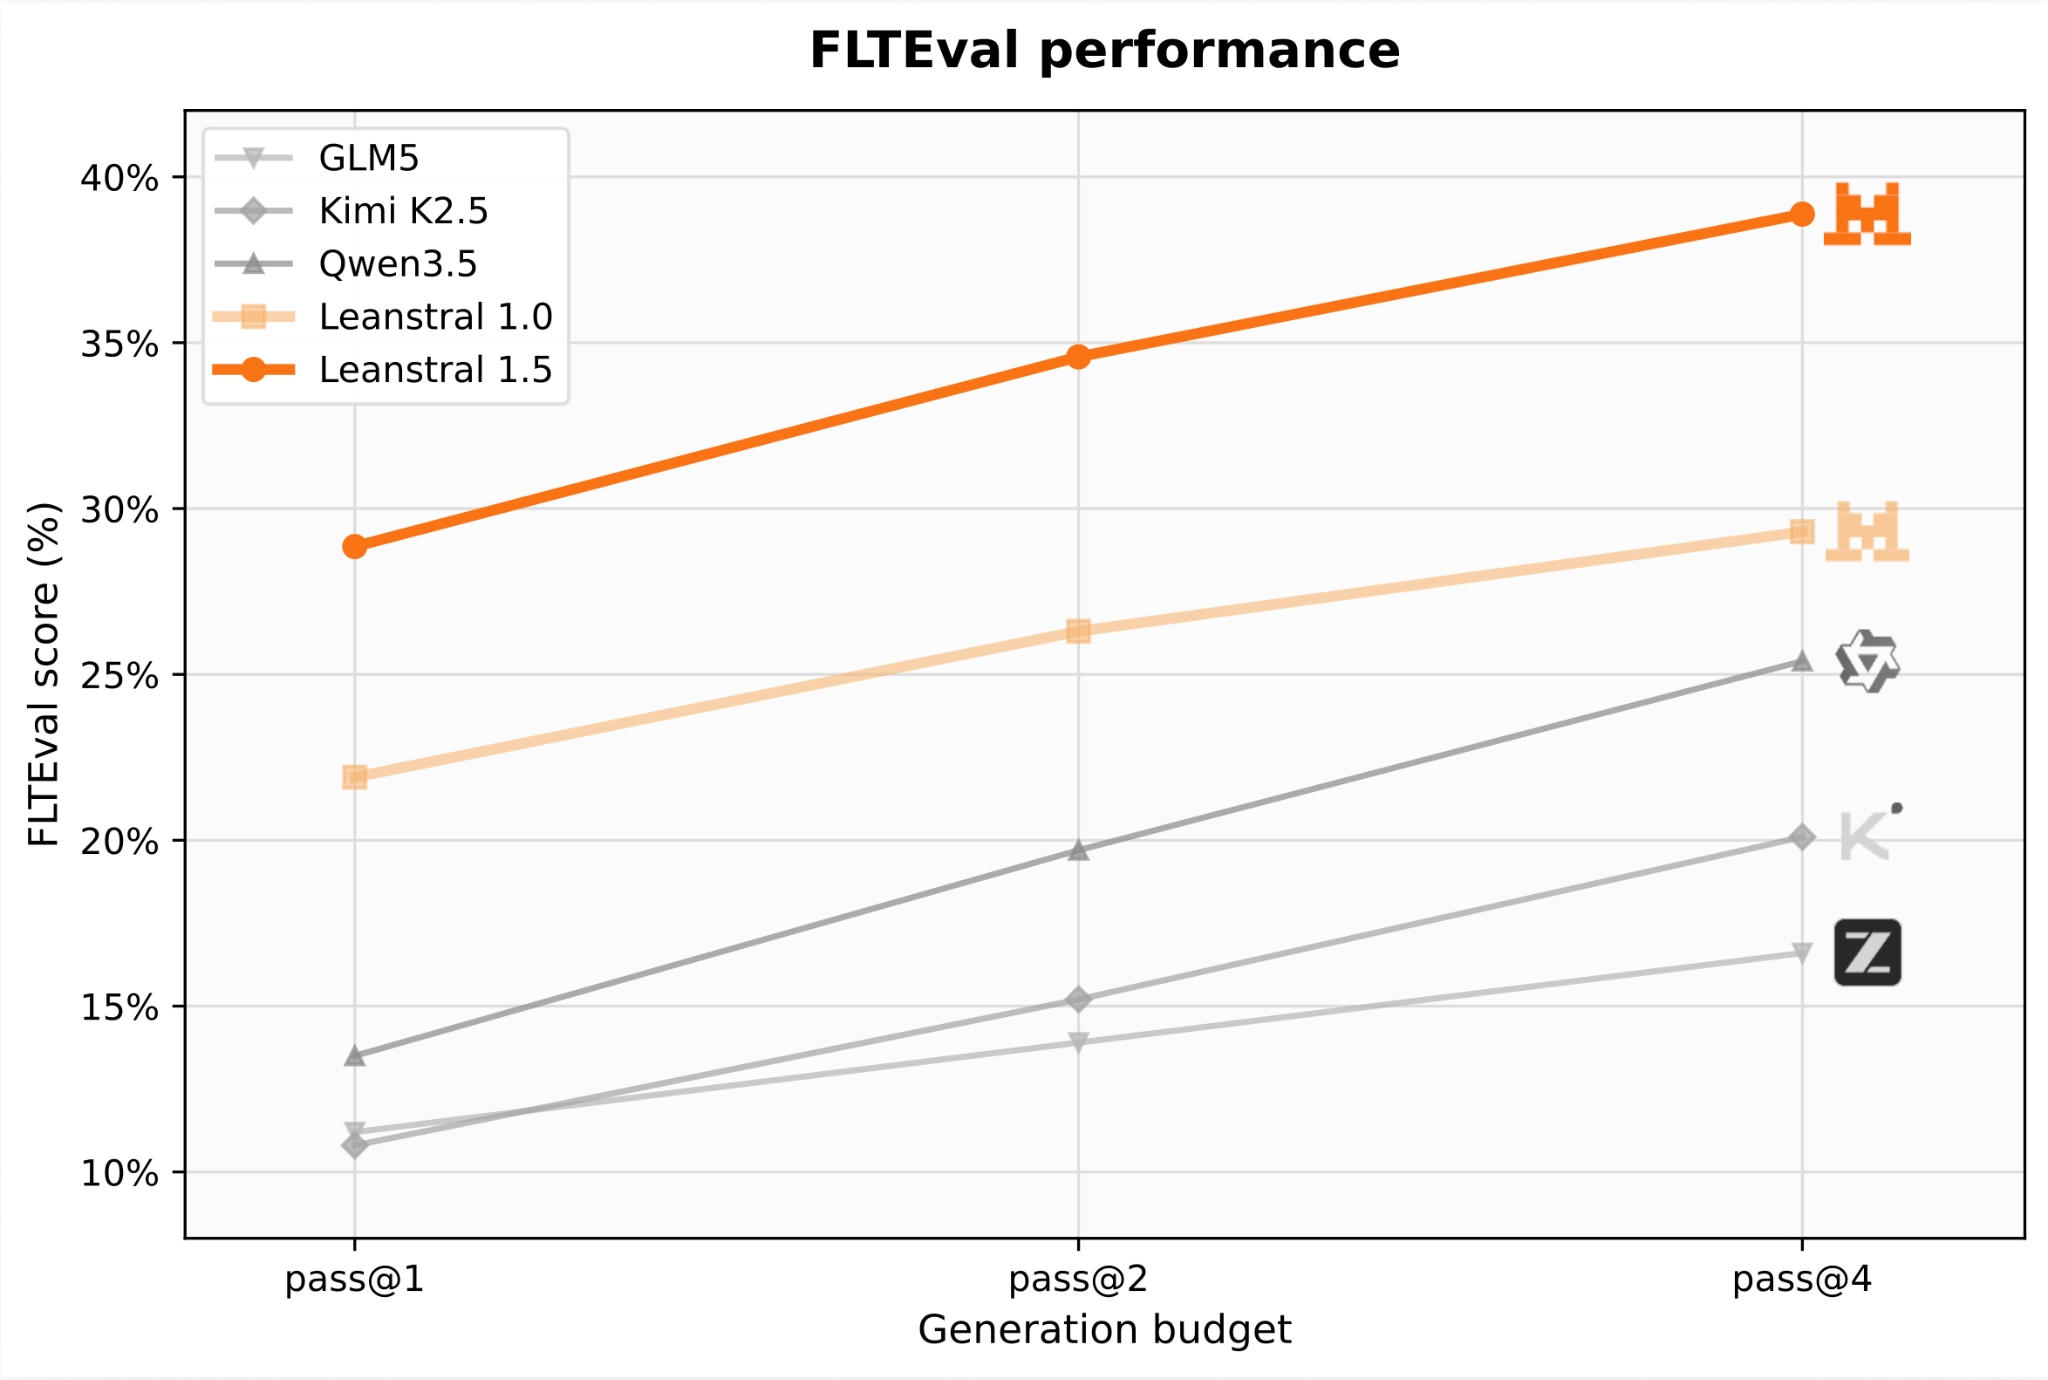
With this release, we also fully open source FLTEval. Leanstral 1.5 lifts pass@1 on the benchmark from 21.9 to 28.9 and pass@8 from 31.9 to 43.2, surpassing Opus 4.6's 39.6 at one-seventh the cost. It also widens its lead over open-source models 3–10× larger, as shown in the figure below.
Code Verification Case Studies
While being primarily trained for mathematics, Leanstral 1.5 exhibits strong abilities in code verification. We present 2 critical case studies to demonstrate its impact.
AVL Trees: Proving Time Complexity
AVL trees are self-balancing binary search trees that maintain O(log n) height through rebalancing during insertions and deletions. Leanstral 1.5 proved these time complexity guarantees for a real implementation—a task that required structural induction to mirror the tree’s recursive structure, careful handling of monadic time tracking, and exhaustive case analysis for rebalancing paths. Over 2.7 million tokens and 22 compactions, Leanstral systematically unfolded each layer of the TimeM monad, exposing the underlying computations despite their interleaving with control flow. It established an almost tight bound of 48 steps per height unit plus a constant for insertion, then connected height to tree size via a logarithmic relationship, delivering complete, verified proofs that insertion and deletion are indeed O(log n).
Bug Discovery: Finding Hidden Flaws
To test Leanstral’s bug-catching abilities, we built an automated pipeline: Aeneas translates Rust code to Lean, while Leanstral infers the user intent and generates correctness properties from the code. Leanstral then attempts to prove each property in four attempts. If they all fail, it tries to prove the negation instead, also with four attempts. Across 57 tested repositories, this process flagged 47 violated properties, with 11 pointing to genuine bugs—5 of them previously unreported on GitHub.
One such bug was in the sign function for zigzag decoding of the datrs/varinteger library. On input Std.U64.MAX, the expression (value + 1) overflowed, causing crashes in debug mode and silent corruption in release mode—an edge case that testing and fuzzing would typically miss. Leanstral’s pipeline caught it automatically, demonstrating that formal verification can already be applied to real-world codebases and find bugs that some traditional methods overlook.
Get Started
Leanstral 1.5 has a Apache-2.0 license. The weights can be found on Huggingface, while also being available now as a free API endpoint as leanstral-1-5. We recommend using it in Mistral Vibe. To begin your journey, grab an API Key, and:
1. Set up Mistral Vibe
uv tool install mistral-vibeuv tool update mistral-vibevibe --setup2. Install Leanstral 1.5
/leanstallexit3. Launch the agent
vibe --agent lean4. Install Lean LSP MCP (Optional)
It is highly recommended to install Lean LSP MCP by adding the following to your ~/.vibe/config.toml
[[mcp_servers]]name = "lean-lsp"transport = "stdio"command = "uvx"args = ["lean-lsp-mcp"]tool_timeout_sec = 600If there are no existing MCP servers, you may have to remove mcp_servers = [].
5. Start proving
Ask Leanstral to tackle a theorem, debug a proof, or contribute to a repository. It’s that simple.
0%
相关条目
精选DeepSeek V4 在 OpenRouter 上的代币份额翻倍,智能体工作负载成主要驱动力
DeepSeek V4 的快速采用表明市场对高性能、低成本推理模型的强烈偏好,尤其是智能体场景将重塑 AI 部署格局。
91
精选启用两项设置使ARC-AGI-3基准测试分数提升三倍
这项发现太关键了!它表明模型的性能不仅取决于训练,还取决于推理时的配置。对于AI工程师和研究者来说,这是一个必须注意的优化方向。特别是那些在资源受限设备上部署模型的团队,可能会因此找到低成本提升能力的方法。
91
精选GPT-5.6:前沿智能与前沿效率的融合
这条消息值得关注,因为它标志着大模型竞争从单纯拼参数转向拼效率。对于AI开发者和企业决策者来说,GPT-5.6意味着可以用更少预算获得更高性能,尤其适合那些被推理成本挡在门外的长上下文或Agent场景。OpenAI这一步,可能重新定义‘前沿’的标准。
91
精选LFM2.5-Encoder:面向CPU快速长上下文推理的新模型
这篇博文让我眼前一亮,因为它直接解决了大模型在CPU上跑长上下文的痛点。对于没有高端GPU的团队或个人开发者,LFM2.5-Encoder系列提供了可立即使用的开源方案。尤其推荐给做RAG、文档搜索或代码分析的朋友——现在用普通服务器就能处理百万级token的文档了。
91
精选GPT-Red:OpenAI通过自我对弈实现AI红队自动化,提升模型鲁棒性
GPT-Red 是红队测试从人工到自动化的里程碑,特别适合安全工程师和对齐研究者关注。它直接降低了测试成本,但也引发了对“自动攻击”本身的伦理讨论——值得所有关注AI治理的人深入思考。
91
精选OpenAI推出GPT-5.5生物漏洞赏金计划
这个计划值得关注,因为它首次将AI漏洞赏金制度拓展到生物安全领域,不仅为安全社区提供了新的研究方向,也为AI风险治理提供了实际演练场。对模型安全研究者、生物安全专家以及关心AI双重用途的从业者尤其重要。
91
精选vLLM推出原生速度Transformers建模后端,大幅提升推理性能
这项更新对于AI工程团队非常关键:无需格式转换意味着能更快地迭代模型,而2-5倍的速度提升直接降低GPU成本。如果你正在做LLM在线服务或者批量推理,这几乎是必读的技术更新。
90
精选Google DeepMind 发布手语转文本模型 SL2T,助力聋人用户
这则消息的意义不仅在于技术突破,更在于AI开始真正关注边缘群体的需求。对开发者而言,SL2T的架构思路和技术路径值得深入研究;对无障碍倡导者来说,这是推动行业标准的重要案例。