Anthropic Introduces Claude Sonnet 5: The Most Agentic Sonnet Model Yet
Score
68Why selected
The model achieves notable breakthroughs in agentic capability and coding intelligence while retaining cost and speed advantages, offering high practical value for developers and enterprises, though not yet reaching frontier AGI levels.
AI commentary
「Claude Sonnet 5 marks a key evolution from passive response to proactive agentic roles, offering significantly more efficient solutions for coding and office scenarios that require autonomous planning and execution.」
Quick overview
Anthropic has officially released Claude Sonnet 5, positioned as the most agentic Sonnet model to date, offering top-tier intelligence for coding and everyday professional work. The model demonstrates significant improvements in complex task execution, tool use, and autonomous decision-making, aiming to deliver a more efficient AI assistant experience for developers and enterprise users. Claude Sonnet 5 maintains the speed and cost advantages of the Sonnet series while achieving breakthroughs in reasoning accuracy and multi-step task planning.
- Claude Sonnet 5 is Anthropic's third-generation Sonnet model optimized for agentic capabilities
- Achieves top-tier intelligence for coding and daily professional work, supporting complex tool use and multi-step reasoning
- Maintains speed and cost-effectiveness of the Sonnet series while improving accuracy and autonomous decision-making
- Targeted at developers and enterprise use cases as an efficient AI assistant replacement for existing workflows
Full text
Showing the source text; the full translation is being generated.
Introducing Claude Sonnet 5
Jun 30, 2026
Claude Sonnet 5 is built to be the most agentic Sonnet model yet. It can make plans, use tools like browsers and terminals, and run autonomously at a level that, just a few months ago, required larger and more expensive models.
For many developers, the agentic AI era began with Sonnet-class models: Claude Sonnet 3.5, 3.6, and 3.7 were the first models that showed impressive skills in coding and tool use. More recently, though, the clearest gains in agentic capabilities have been in our Opus-class models.
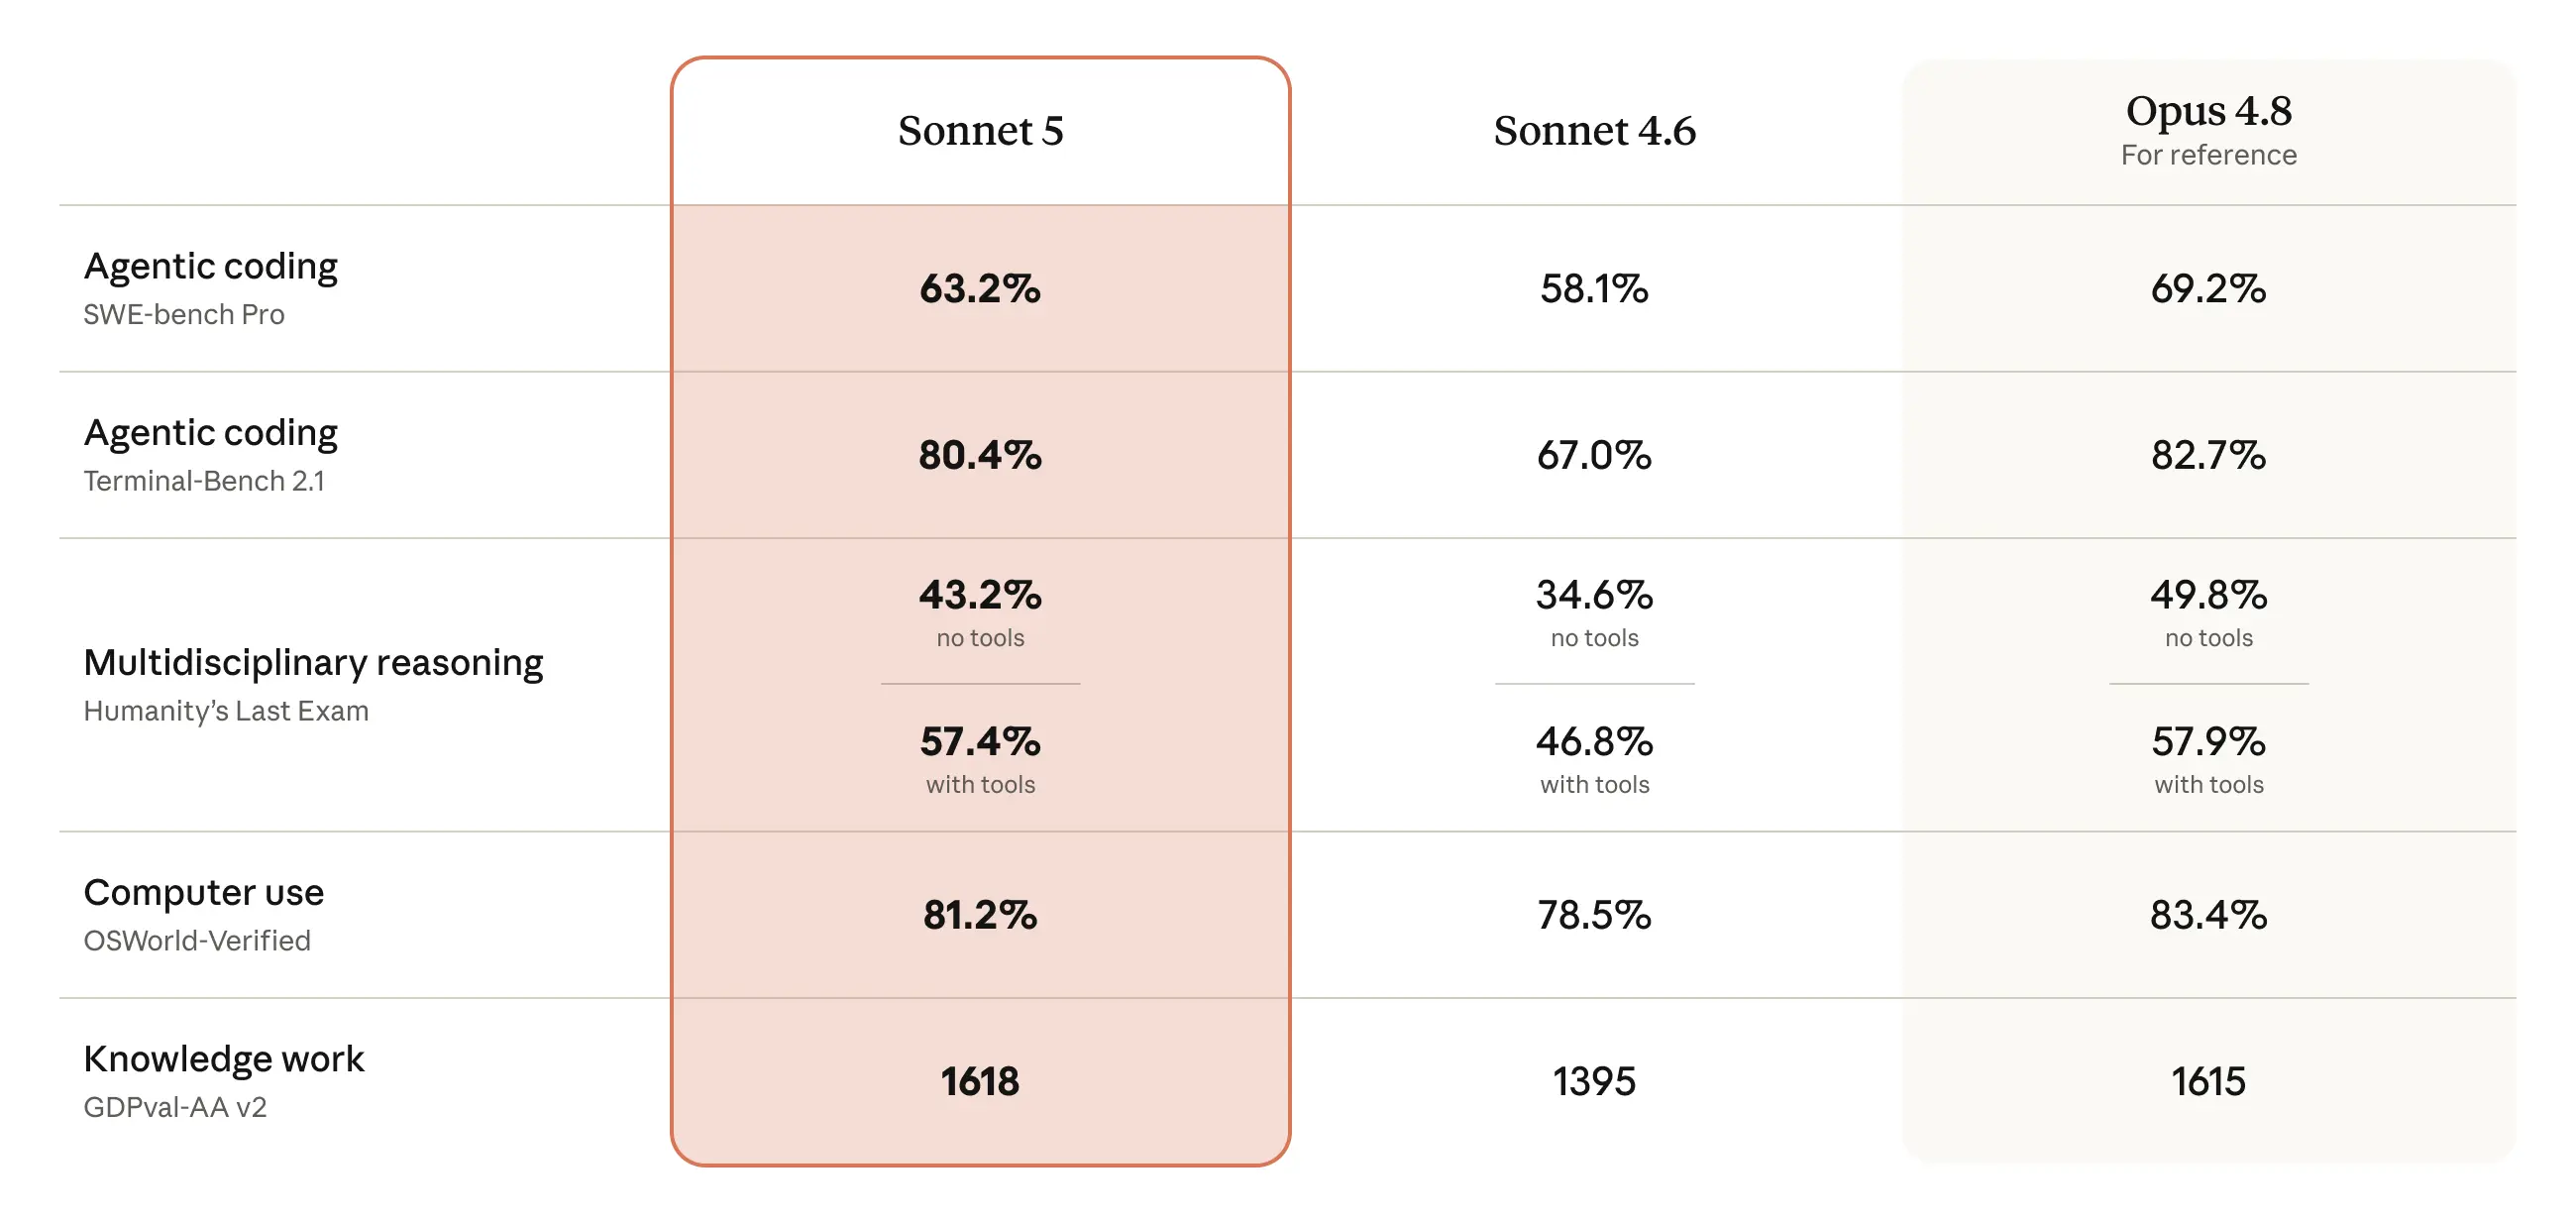
Sonnet 5 narrows the gap: its performance is close to that of Opus 4.8, but at lower prices. It’s a substantial improvement over its predecessor, Sonnet 4.6, on important aspects of agentic performance like reasoning, tool use, coding, and knowledge work:
Our safety assessments found that Sonnet 5 shows an overall lower rate of undesirable behaviors than Sonnet 4.6, and is generally safer to use in agentic contexts. Evaluations also show that it has a much lower ability to perform cybersecurity tasks than our current Opus models.
From today, Claude Sonnet 5 is available across all plans: it is the default model for Free and Pro plans, and is available to Max, Team, and Enterprise users. It’s also available in Claude Code and on the Claude Platform, where it launches with introductory pricing of $2 per million input tokens and $10 per million output tokens through August 31, 2026, after which it will be priced at $3 per million input tokens and $15 per million output tokens. Developers can use claude-sonnet-5 via the Claude API.
Working with Claude Sonnet 5
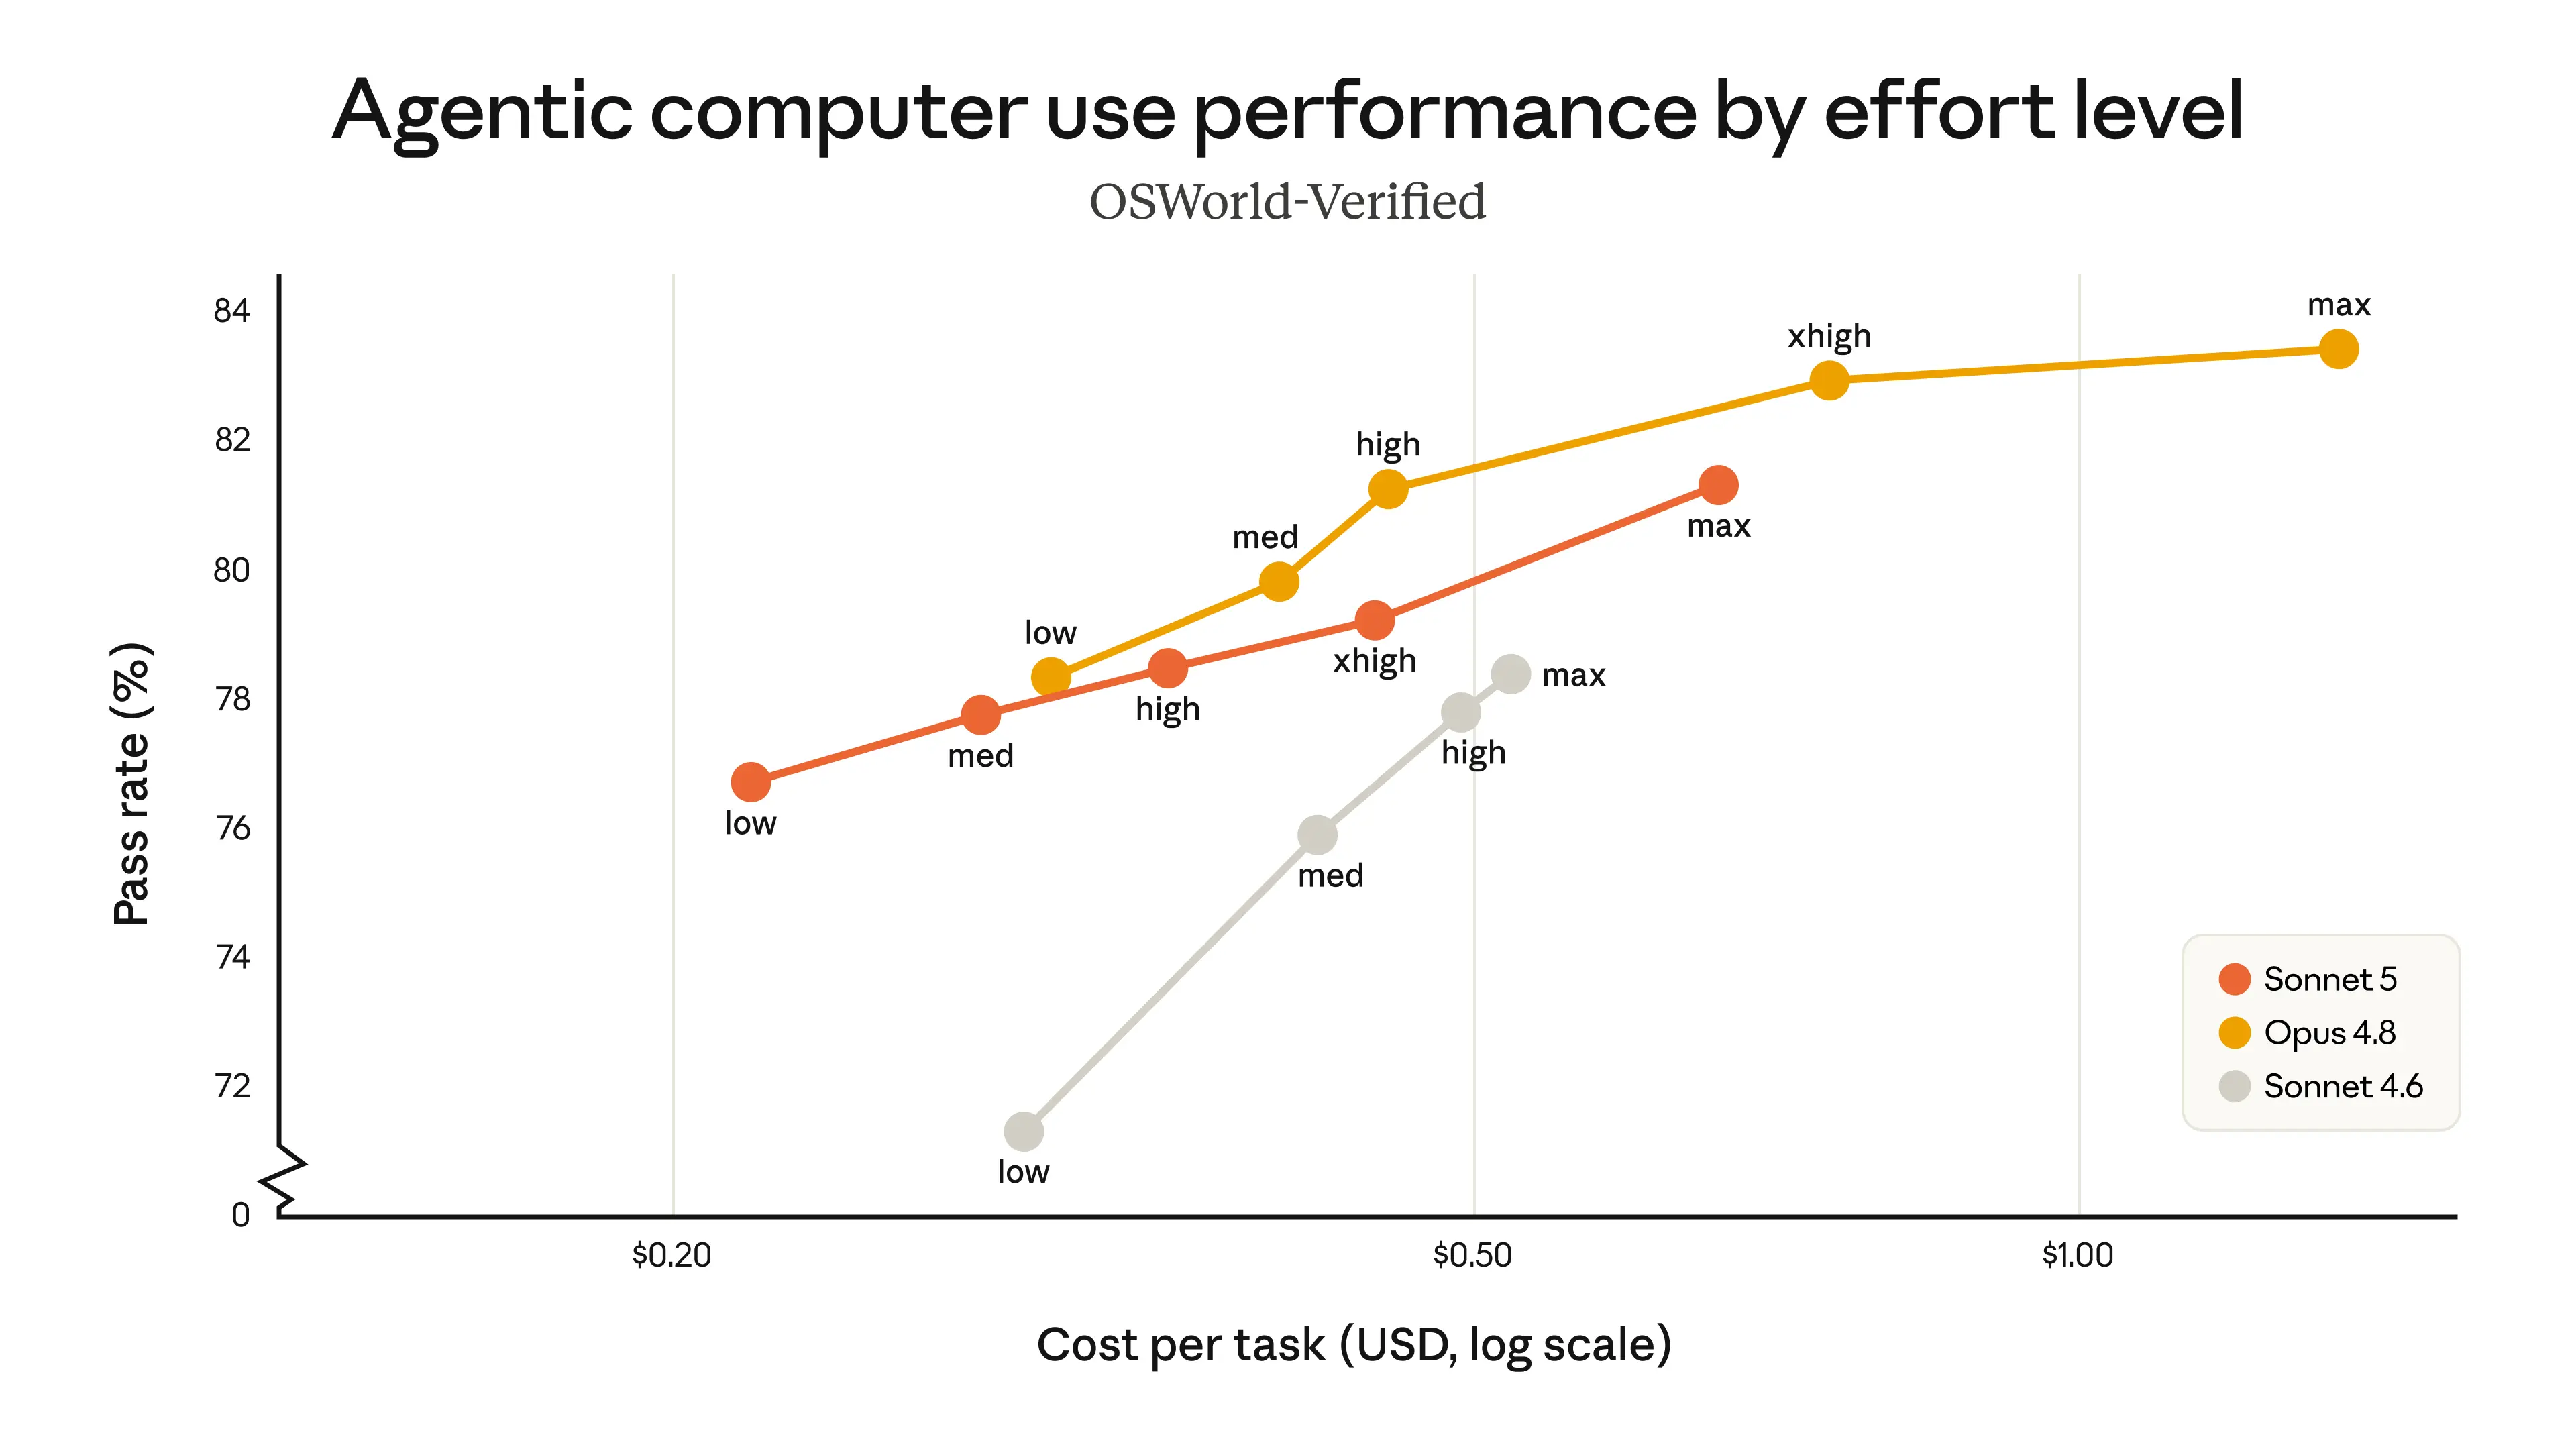
The charts below compare the performance of Sonnet 5 with Sonnet 4.6 and Opus 4.8 at different effort levels on the agentic search evaluation BrowseComp and the computer use evaluation OSWorld-Verified. Sonnet 5 (orange line) is a strict improvement over Sonnet 4.6 (gray line) and covers a much wider range of cost-performance options than Opus 4.8 (yellow line). It provides substantially improved cost efficiency at medium effort; its higher-effort performance can match Opus 4.8 on some tasks. Between Sonnet 5 and Opus 4.8, users can adjust the effort level to find the right balance of cost and performance.
Agentic searchAgentic computer use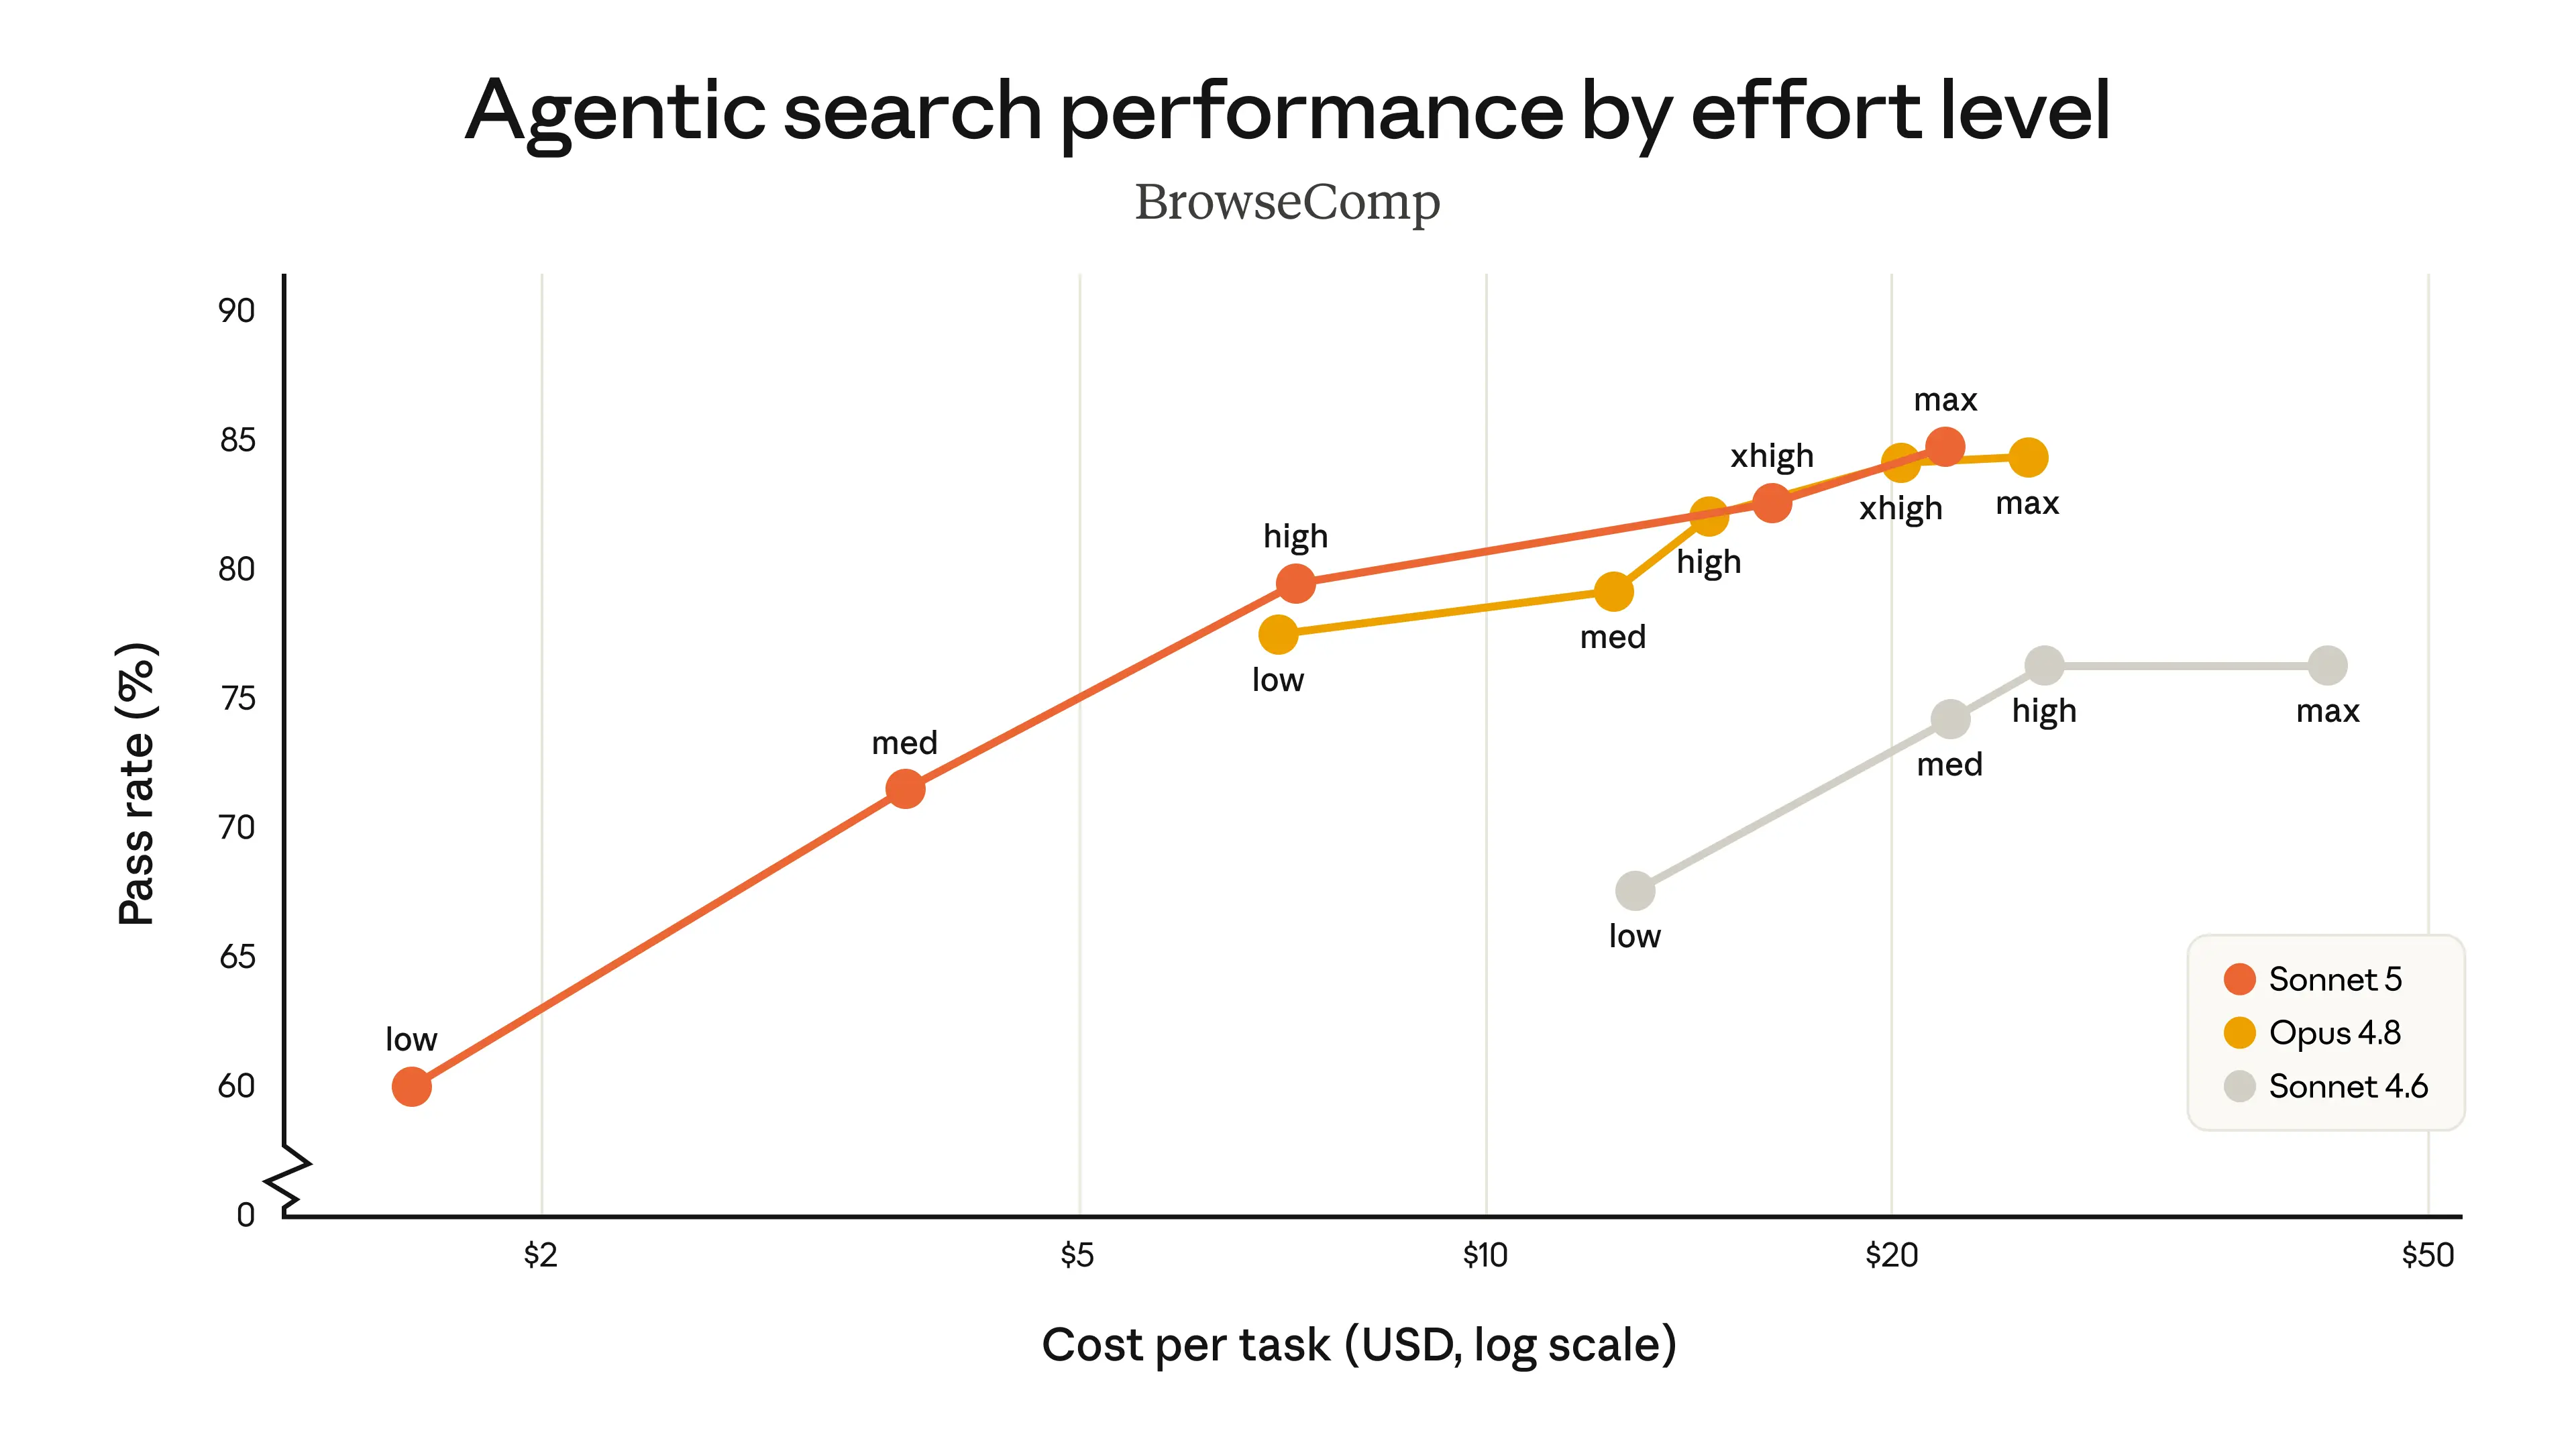
Feedback from our early access partners has been consistent: Sonnet 5 is much more agentic than its predecessors. Testers described how it finishes complex tasks where previous Sonnet models would stop short, how it checks its own output without explicitly being asked, and how it does all this agentic work at an attractive price point:

Claude Sonnet 5 gives our agents a strong execution layer for multi-step software engineering work. It handles sustained coding, tool use, and debugging well across messy technical contexts, and has been especially useful for workflows where follow-through and technical grounding matter.Zimu Li
Member of Technical Staff

We handed Claude Sonnet 5 a two-part job—update Salesforce account tiers, send a launch announcement to enterprise contacts—and it finished end to end. That used to stall halfway. For day-to-day automation, it’s a no-brainer.Daniel Shepard
Senior Engineer

Claude Sonnet 5 gets more done with less. Same output quality, fewer steps to get there. It refuses unsafe requests cleanly and consistently, too. At Lovable, we’re putting powerful tools in the hands of millions of builders. A model that knows when to say no is just as important as one that knows how to build.Fabian Hedin
Co-founder

We ran Claude Sonnet 5 against dozens of our most challenging real pull requests, and it carried each one through to a tested, verified result on its own — freeing our engineers to focus on the judgment, the decision, and the final sign-off.Yusuke Kaji
GM, AI for Business

I asked Claude Sonnet 5 to investigate a bug. Unprompted, it wrote a reproducing test, implemented the fix, then stashed it to confirm the bug came back without the change. All in a single pass.Neel Chotai
Rust Engineer and Software Engineer

With Claude Sonnet 5, agents stay on plan, follow our conventions, and ship clean multi-step changes, all at an efficient cost.Sualeh Asif
Co-founder

Claude Sonnet 5 is at its best on brownfield code—race conditions, hidden tests, the parts nobody wants to touch. It traces a failure to its actual root cause and ships a durable fix instead of patching the symptom.Dominic Elm
Founding Engineer

Claude Sonnet 5 sits on the Pareto frontier for Eve’s plaintiff-law tasks. We see the clearest gains in legal research and analysis, at a price-to-performance ratio that made the choice to migrate easy.Mauricio Wulfovich
Staff ML Engineer

ClickHouse agents explore live data and produce insights on the fly, so time-to-insight matters when testing new models. Claude Sonnet 5 reasons in tighter steps and gets our users to answers noticeably faster. That speed is a difference our customers feel.Ryadh Dahimene
Director PM AI/ML

At Pace, our computer-use agents run insurance workflows—submission intake, FNOL, loss runs—on the systems our operations teams already use. Claude Sonnet 5 consistently takes the right action and does it quickly, which is what real insurance work demands.Eric He
Member of Technical Staff

For enterprise teams managing high-volume, complex workloads, Claude Sonnet 5 represents a genuine step forward — strong performance where it counts, with the speed and cost profile that makes scaling practical. On several complex tasks it exceeds the current frontier, while delivering fast responses at low costs. For enterprises running at scale, that's a real operational win.Ben Kus
Chief Technology Officer

Claude Sonnet 5 handled the full range of coding tasks we tested it on, while resolving more issues. It's a meaningful improvement to both quality and efficiency.Manav Khurana
CPMO

Claude Sonnet 5 is a strong agentic-coding model, delivering top-tier accuracy comparable to Opus-class models and a clear step-function improvement over Sonnet 4.6. It conducts thorough explorations and sustains focus noticeably longer on complex tasks.Deepak Singh01 / 13
VP, Kiro
Safety evaluations
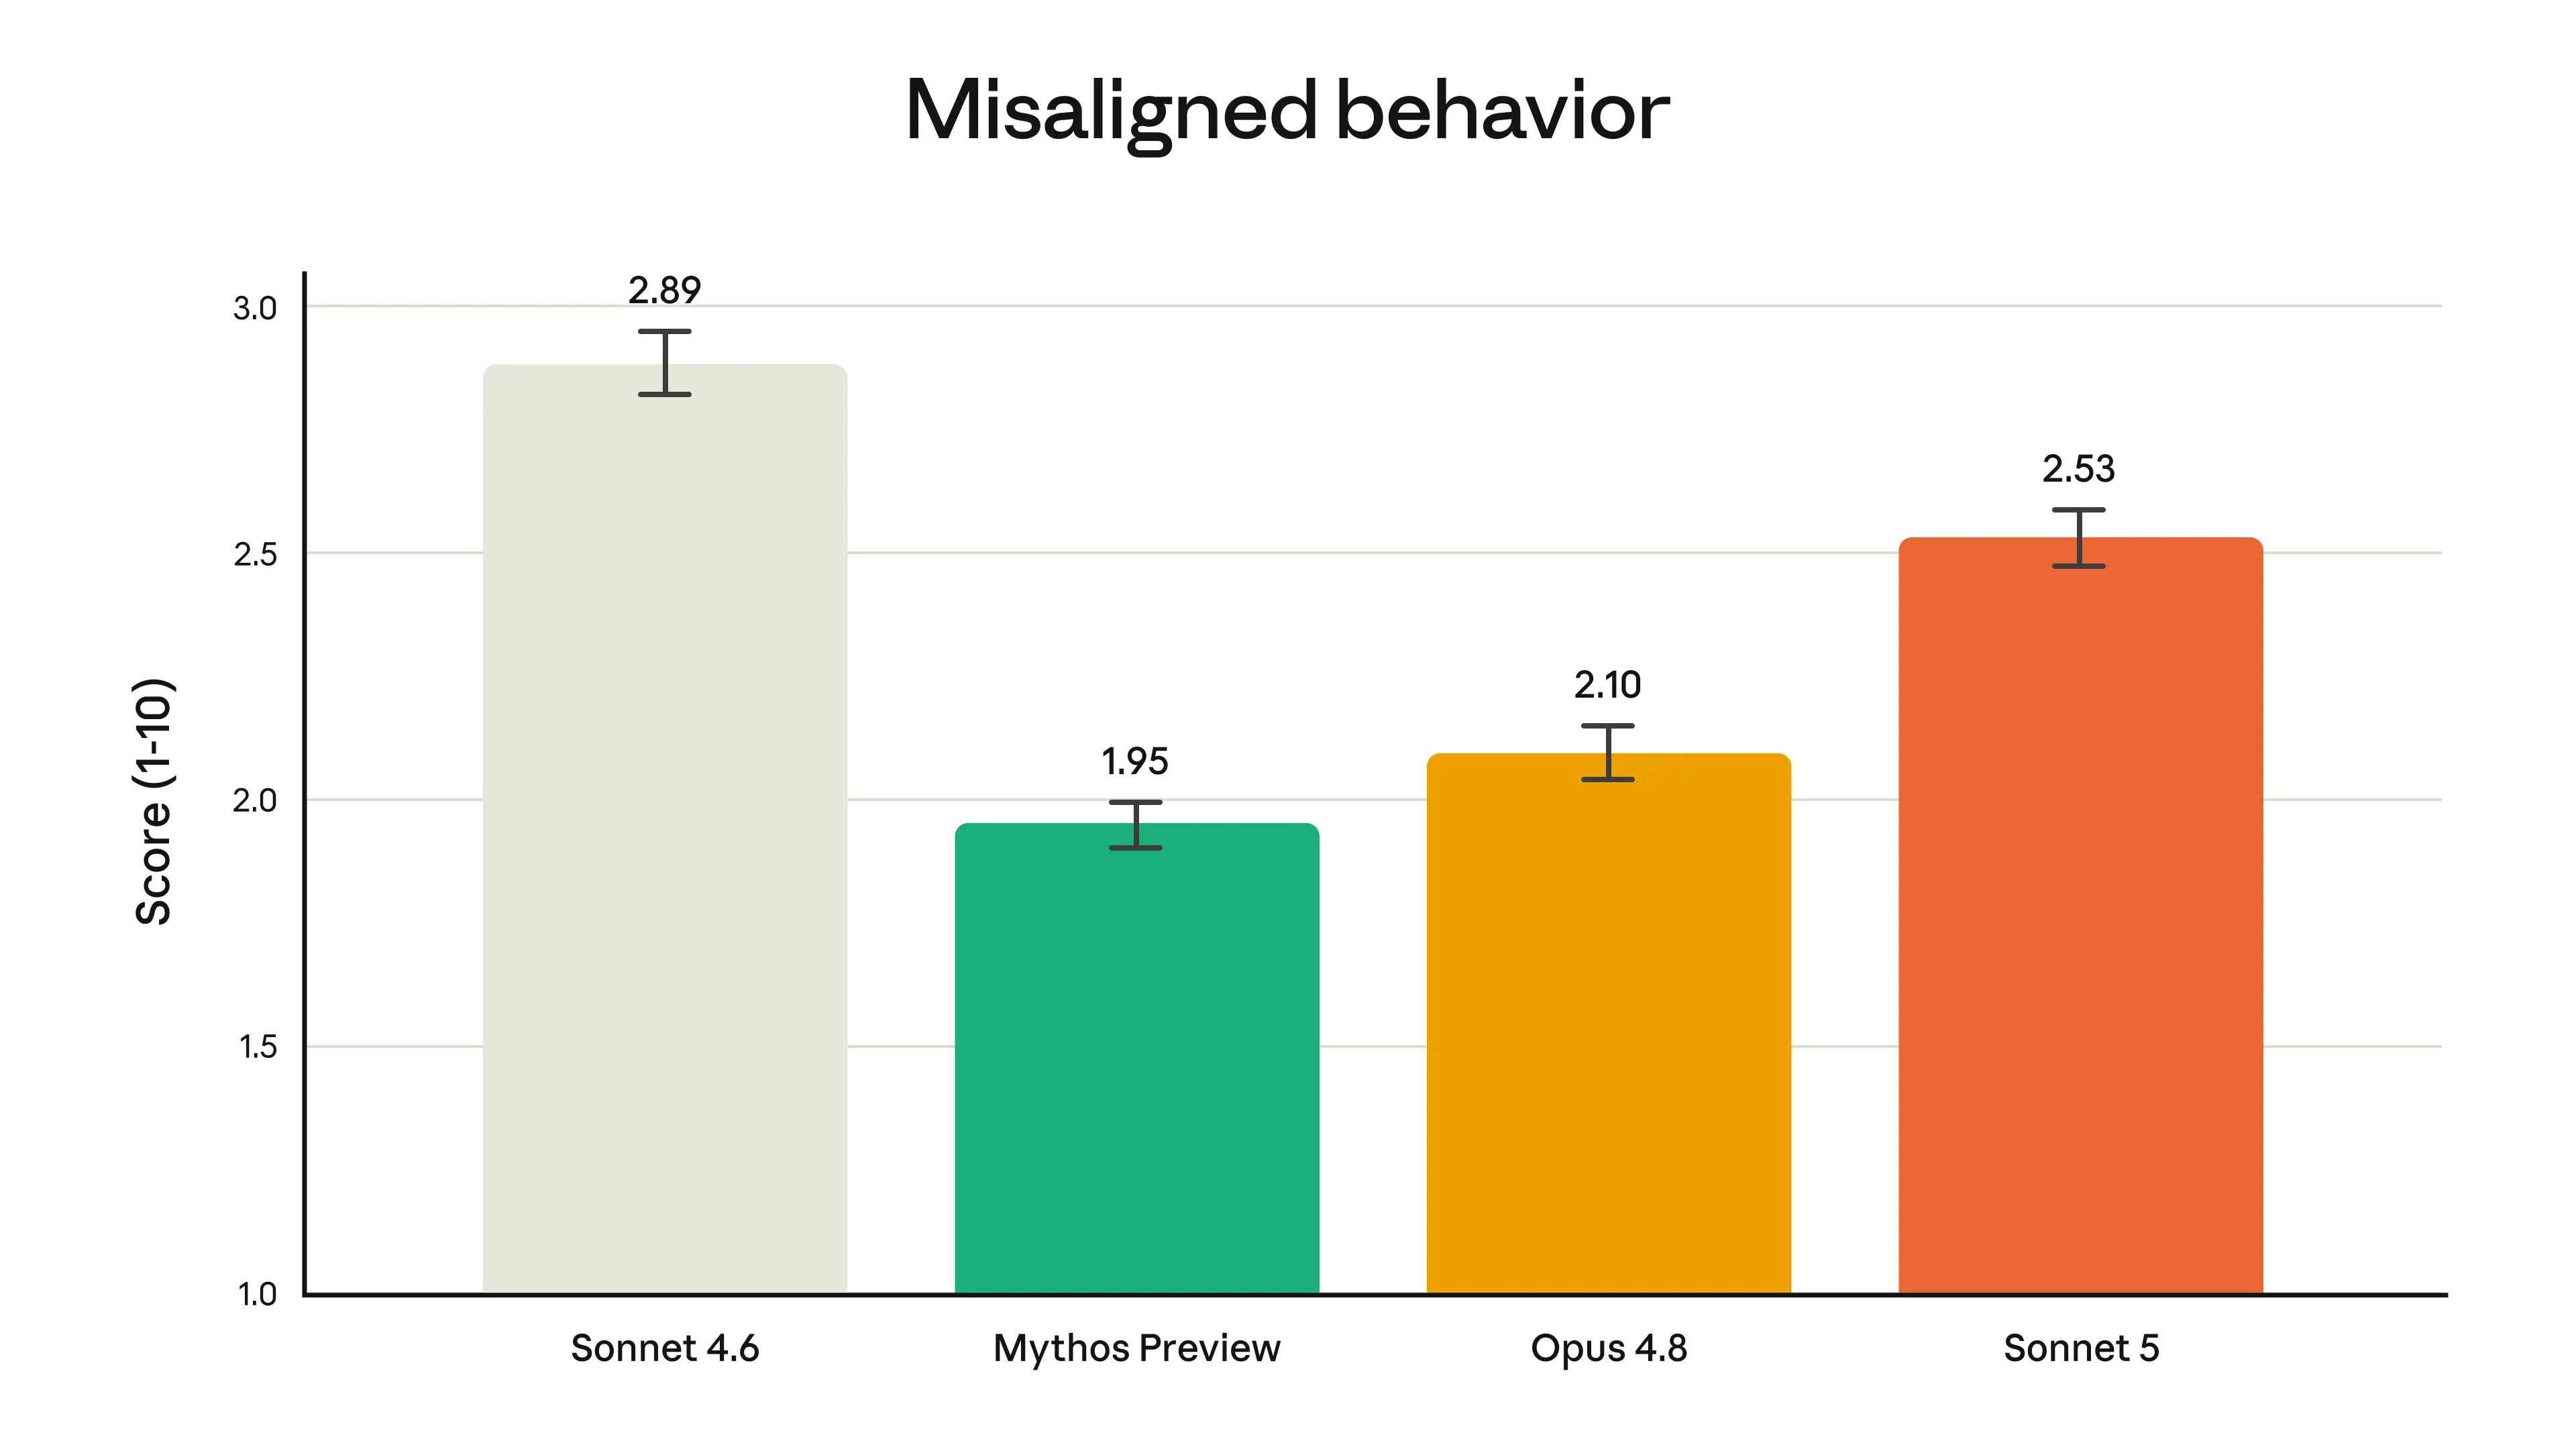
Our pre-deployment safety evaluations found that Sonnet 5 was overall an improvement on Sonnet 4.6. On agentic safety, the model is better at refusing malicious requests and resisting hijack attempts in prompt injection attacks. The model shows lower rates of hallucination and sycophancy than Sonnet 4.6. On our automated behavioral audit, which tests a wide range of misaligned behaviors such as cooperation with misuse and deception, Sonnet 5 scored lower (that is, safer) overall. However, it did show somewhat higher rates of misaligned behavior on this assessment compared to the more capable Opus 4.8 and Claude Mythos Preview.
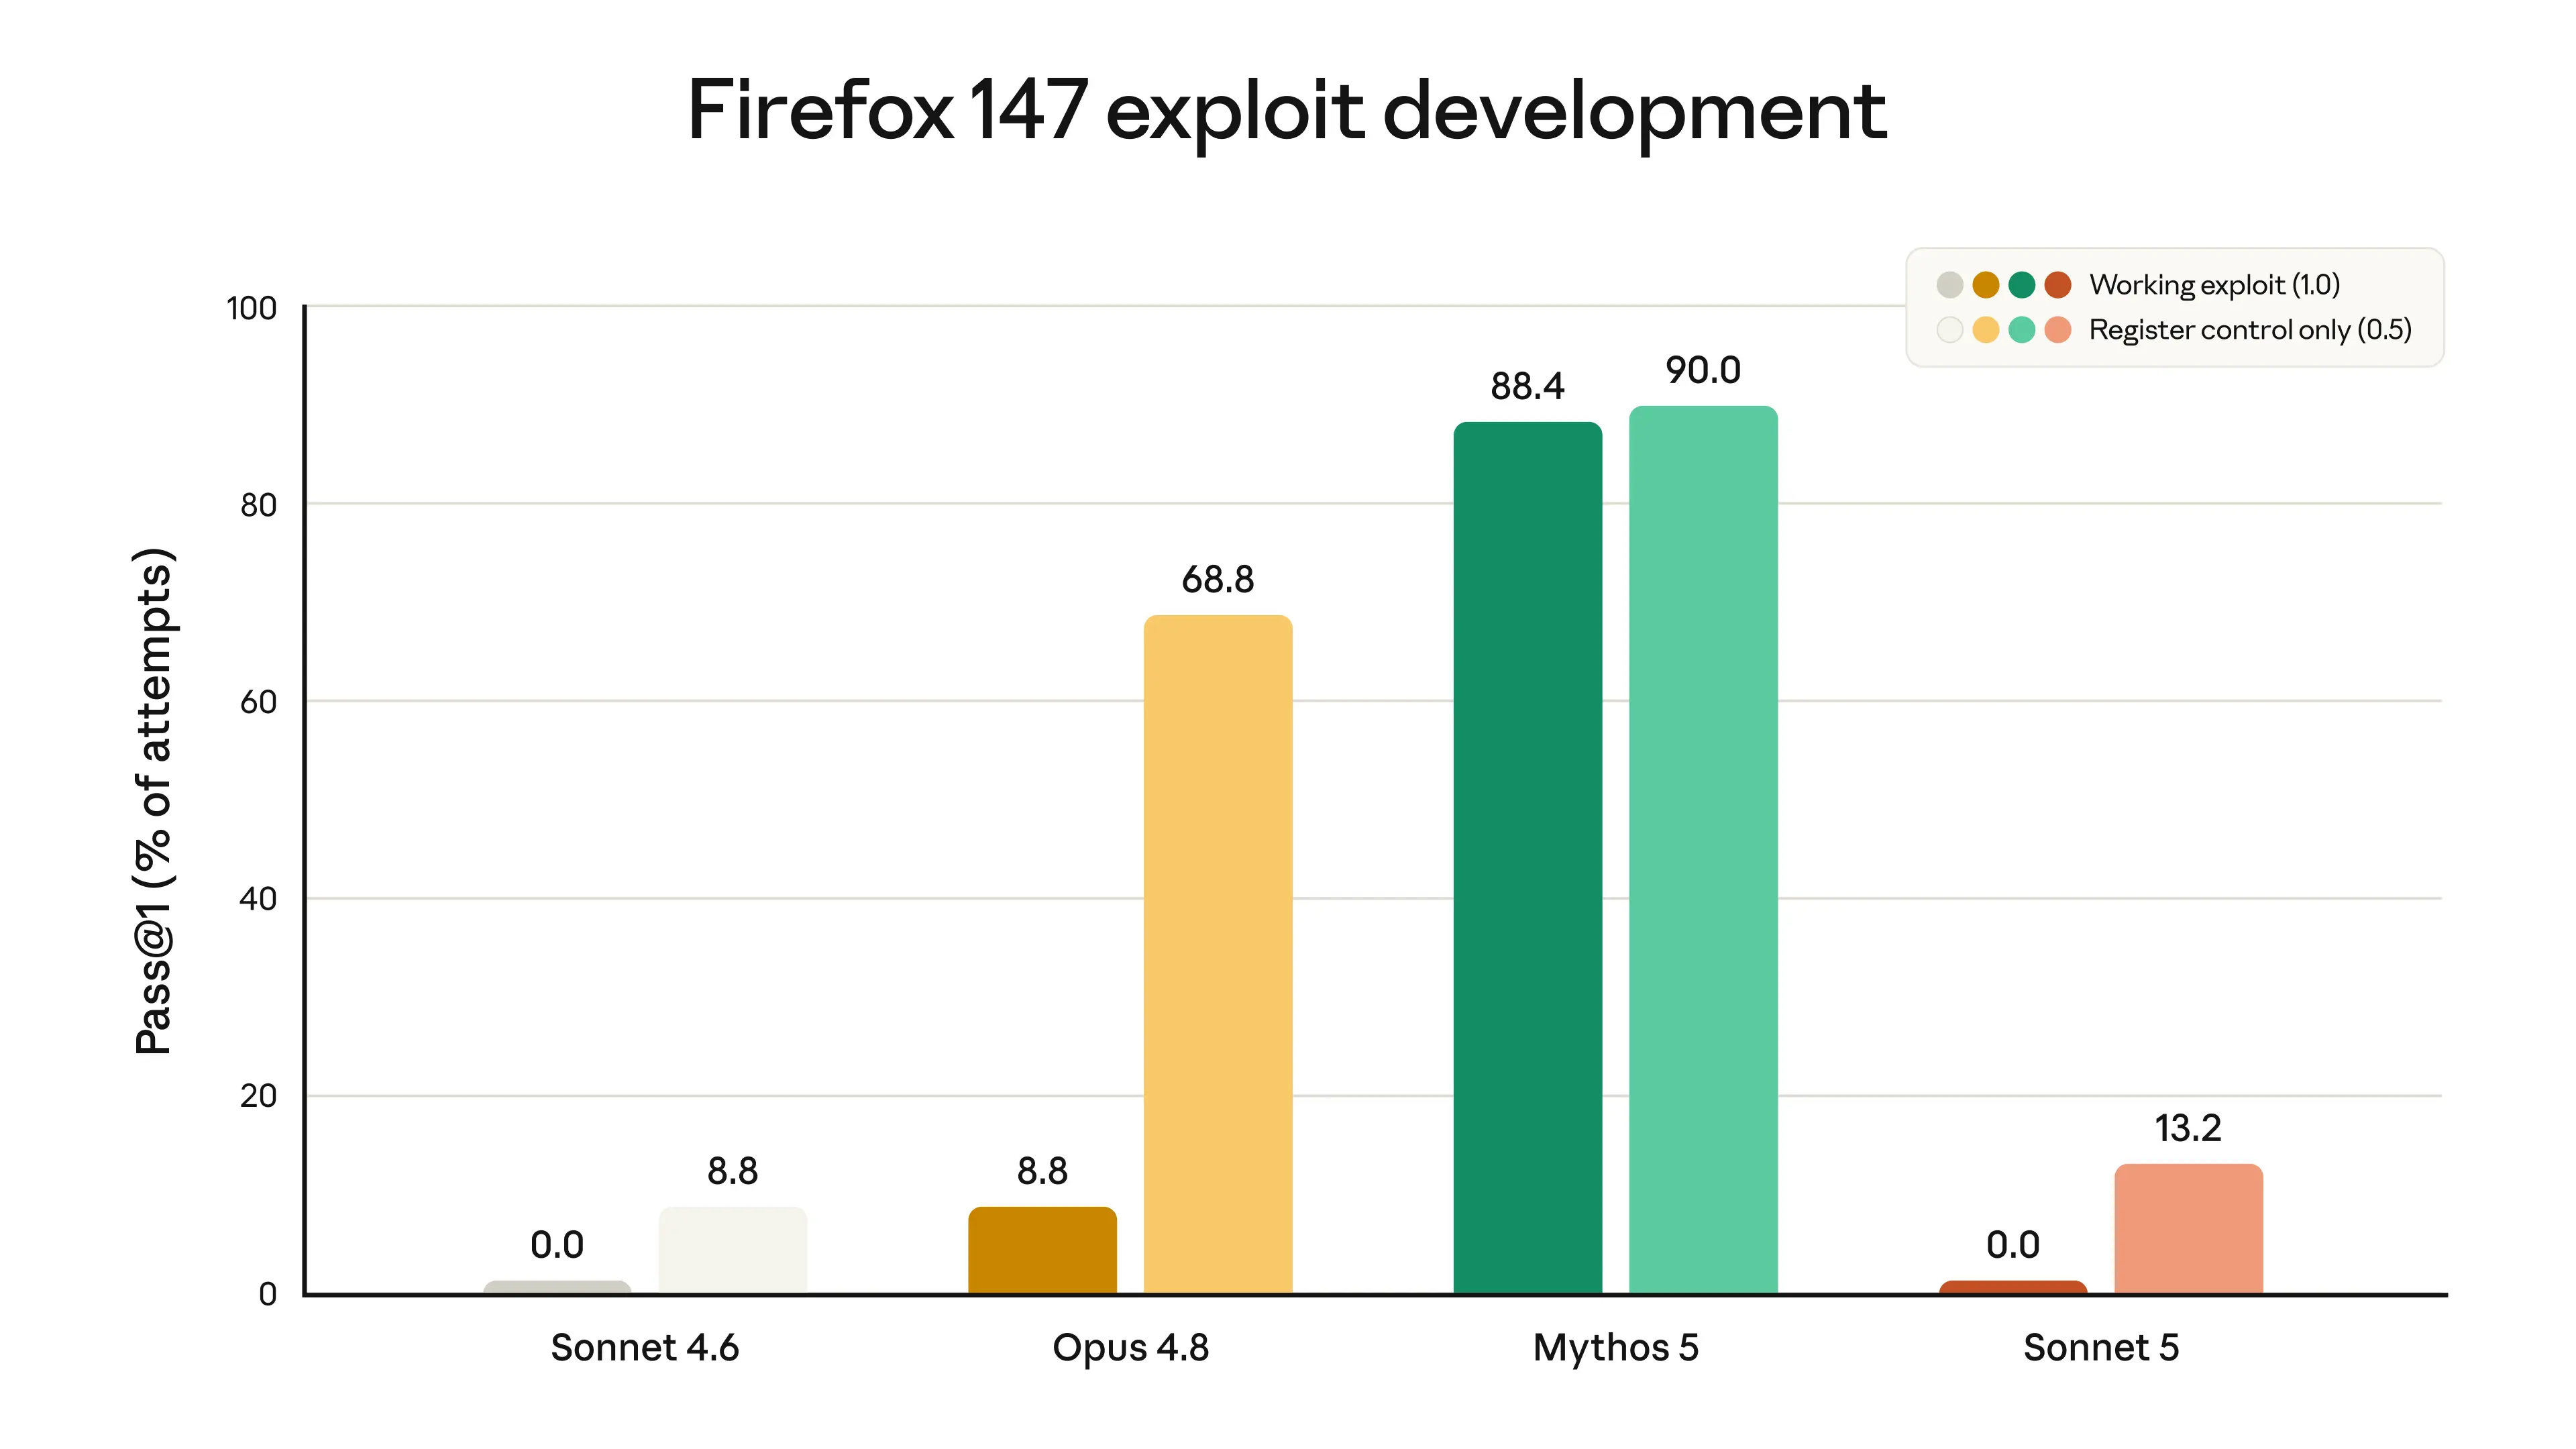
We did not deliberately train Sonnet 5 on cybersecurity tasks. It can perform some routine, non-harmful cyber tasks, but on evaluations testing potentially dangerous cyber skills, such as developing software exploits, it shows substantially poorer performance than models such as Opus 4.8 and Mythos 5. Scores from one evaluation, which tested models’ ability to develop exploits for vulnerabilities in the Firefox browser, are shown in the chart below. Sonnet 5 was never able to develop a full working exploit, but it does show a slightly higher rate of partial success than Sonnet 4.6. This latter change is likely due to improvements in general intelligence rather than specific training.
Since Sonnet 5 is somewhat stronger than its predecessor on these tasks, we’ve launched it with cyber safeguards enabled by default. These safeguards—which detect and block dangerous cyber usage in real time—are the same as those present in Claude Opus 4.7 and 4.8 (because we judged that the overall level of cybersecurity risk from Sonnet 5 was low, the safeguards are less strict than those launched with Fable 5, which block a much wider range of cybersecurity tasks).1
Our full assessment of Sonnet 5 across many safety and capability evaluations is reported in the Claude Sonnet 5 System Card.
Availability and pricing
Claude Sonnet 5 is available everywhere today at an introductory price of $2 per million input tokens and $10 per million output tokens through August 31, 2026. It then moves to standard pricing at $3 per million input tokens and $15 per million output tokens.2 We’ve increased rate limits across Chat, Cowork, Claude Code, and the Claude Platform3 to accommodate the higher token usage of higher effort levels; users can select whichever level makes sense for their particular project.
Changelog
Edit June 30, 2026: In the original version of this post, we included a cost-performance chart for the BrowseComp evaluation that was based on data from a simpler methodology that did not reflect the standard methodology we use for agentic search evaluations. This had the result of underestimating Sonnet 5's performance on the evaluation.
We have now updated the chart so that it matches the methodology that we used and discussed in the Sonnet 5 system card (which used a 10M token budget with compaction and programmatic tool calling). We have also updated the surrounding text.
Footnotes
1 Sonnet 5 is part of our Cyber Verification Program, which is available today on the native Claude Platform, the Claude Platform on AWS, and Claude in Microsoft Foundry (hosted on Azure and Anthropic), and coming soon on Claude in Google Vertex. Organizations that are already enrolled in the Cyber Verification Program automatically have the same access on Sonnet 5, with no need to reapply. Overall, we recommend Claude Opus 4.8 for cybersecurity work that requires reduced guardrails.
2 Sonnet 5 is an upgrade to Sonnet 4.6, but it uses an updated tokenizer that changes how the model processes text to improve performance (this is similar to the tokenizer change we introduced with Claude Opus 4.7). The tradeoff is that the same input can map to more tokens: roughly 1.0–1.35× depending on the content type. The introductory pricing is set so that the transition to Sonnet 5 is roughly cost-neutral.
3 On April 26, 2026, we raised Sonnet and Haiku rate limits at every usage tier and simplified to three tiers (Start, Build, and Scale) on the native Claude Platform. You can view your tier and current limits in the Claude Console or read the documentation to learn more.
- Humanity’s Last Exam: We updated the grader model for Humanity’s Last Exam and have updated the Sonnet 4.6 score to 34.6% (no tools) and 46.8% (with tools). This is the reason the score differs from that reported in the Sonnet 4.6 launch blog.
- OSWorld-Verified: We made changes to how we run the OSWorld-Verified evaluation to more accurately reflect the model’s performance in the real world, and have updated the Sonnet 4.6 score to 78.5%. This is the reason the score differs from that reported in the Sonnet 4.6 launch blog.
Related content
More details on Fable 5’s cyber safeguards and our jailbreak framework
Read moreRedeploying Fable 5
Fable 5 returns globally July 1. We're also proposing an industry-wide framework for scoring jailbreak severity, together with Amazon, Microsoft, Google, and other Glasswing partners.
Read moreClaude Science, an AI workbench for scientists, is now available
Claude Science is a customizable app that integrates the tools and packages researchers most often use, produces auditable artifacts, and provides flexible access to computing resources.
Read moreOther reports on this story
- T1.5Claude Code:GitHub Releases(RSS)Claude Code v2.1.201 Release: Sonnet 5 Sessions Remove Mid-Conversation System Role Reminders07:50
- T2Simon Willison 博客(Atom)Claude Sonnet 5.506:07
- T2TechCrunch:AI(RSS)Anthropic Launches Claude Sonnet 5: A Cheaper Way to Run Agents02:00
Related items
FeaturedDeepSeek V4 Doubles Token Share on OpenRouter, Driven by Agentic Workloads
DeepSeek V4 在 OpenRouter 上的代币份额翻倍,智能体工作负载成主要驱动力
The rapid adoption of DeepSeek V4 signals a strong market preference for high-performance, low-cost inference models, especially as agentic use cases reshape AI deployment.
91
FeaturedEnabling Two Settings Triples ARC-AGI-3 Benchmark Scores
启用两项设置使ARC-AGI-3基准测试分数提升三倍
This finding is crucial! It shows that model performance depends not only on training but also on inference-time configuration. For AI engineers and researchers, this is a must-know optimization direction. Teams deploying models on resource-constrained devices in particular could find a low-cost way to boost capabilities.
91
FeaturedGPT-5.6: Fusing Frontier Intelligence with Frontier Efficiency
GPT-5.6:前沿智能与前沿效率的融合
This news is worth watching as it marks a shift from pure parameter scaling to efficiency competition. For AI developers and business decision-makers, GPT-5.6 means higher performance at lower cost, especially for long-context or agentic tasks previously hindered by inference expenses. OpenAI's move may redefine what 'frontier' means.
91
FeaturedLFM2.5-Encoders: New Models for Fast Long-Context Inference on CPU
LFM2.5-Encoder:面向CPU快速长上下文推理的新模型
This blog post catches my eye because it directly solves the pain point of running long-context LLMs on CPU. For teams or individual developers without high-end GPUs, the LFM2.5-Encoder series offers a ready-to-use open-source solution. Highly recommended for those working on RAG, document search, or code analysis—now a standard server can handle million-token documents.
91
FeaturedGPT-Red: OpenAI Automates Red Teaming via Self-Play to Boost Model Robustness
GPT-Red:OpenAI通过自我对弈实现AI红队自动化,提升模型鲁棒性
GPT-Red marks a milestone from human to automated red-teaming—essential for safety engineers and alignment researchers. While reducing cost, it also raises ethical questions about automated attacks, worth pondering for everyone in AI governance.
91
FeaturedOpenAI Launches GPT-5.5 Bio Bug Bounty Program
OpenAI推出GPT-5.5生物漏洞赏金计划
This program deserves attention as it pioneers the extension of AI bug bounty to biosecurity, offering a new research direction for the security community and a practical training ground for AI risk governance. It is particularly important for model safety researchers, biosecurity experts, and practitioners concerned about dual-use AI risks.
91
FeaturedvLLM Introduces Native-Speed Transformers Modeling Backend for Enhanced Inference Performance
vLLM推出原生速度Transformers建模后端,大幅提升推理性能
This update is critical for AI engineering teams: eliminating format conversion speeds up model iteration, and 2-5x speedup directly reduces GPU costs. If you're building LLM online services or batch inference, this is practically a must-read technical update.
90
FeaturedGoogle DeepMind Introduces SL2T, a Sign Language-to-Text Model for Deaf Users
Google DeepMind 发布手语转文本模型 SL2T,助力聋人用户
This news matters not only as a technical breakthrough but also as a sign that AI is beginning to address the needs of marginalized groups. For developers, the architecture and technical approach of SL2T merit deep study; for accessibility advocates, it's a key case for advancing industry standards.