Meta Introduces Muse Glimmer, an Open-Weight 30B Model for Agentic Task Completion
Score
79独家介绍新发布的 Muse Glimmer 并提供第一手实测细节,信息增量高。
包含模型定位、基准表现和实际运行案例,内容扎实但缺少体系化评估。
给出量化体积、内存需求和本地运行工具链,对开发者有直接操作参考价值。
报道紧贴模型发布当天,具有很强时效性。
Simon Willison 是知名开发者博主,信源可靠,但属于个人博客而非官方发布。
Base 88 × T2 Source weight ×0.9 = 79
Curation line 70Selected
Why selected
Timely coverage of a new model release with hands-on testing by a prominent developer blogger, though it lacks direct benchmark comparisons against existing models.
AI commentary
「What excites me most here isn't the parameter count—it's the combination of Apache 2.0 licensing and local runnability. That means developers can actually own their agent stack instead of being tied to a platform. If you're working on tool calling or long-horizon agentic workflows, Muse Glimmer is worth pulling down and testing right away.」
Quick overview
Meta has released Muse Glimmer, a brand-new 30B model under a clean Apache 2.0 license, marking a return to open weights. The model is optimized for end-to-end agentic task completion, achieving strong success rates on full-task benchmarks including DeepSearch QA, MCP-Atlas, Tau-Bench, and SWE-Bench. It emphasizes reliable tool use, multi-step reasoning over long horizons, and vision capabilities. Simon Willison tested the 18.16 GB quantized version in LM Studio, noting it runs comfortably on machines with 32GB RAM or more, and demonstrated its ability to explore a codebase and describe images in natural language.
- Muse Glimmer is a brand-new 30B open-weight model under Apache 2.0, a step up from earlier Llama licenses.
- Optimized for end-to-end agentic task completion, with strong results on DeepSearch QA, MCP-Atlas, Tau-Bench, and SWE-Bench.
- Features reliable tool use, long-horizon multi-step reasoning, and vision-language capabilities for local agents.
- The 18.16 GB quantized version runs on machines with 32GB RAM or more; the author tested it with LM Studio and his llm-coding-agent plugin.
Full text
Showing the source text; the full translation is being generated.
They claim to have optimized it for exactly the kind of things I'm looking for in a local model:
- End-to-end Agentic Task Completion. Muse Glimmer achieves strong success rates on full-task benchmarks including DeepSearch QA, MCP-Atlas, 𝛕-Bench and SWE-Bench, which measure its ability to work within scaffolds, write and debug code, and resolve multi-turn requests from start to finish.
- Reliable Tool Use. The model handles a wide range of function calls, invoking tools with precise schemas throughout extended workflows.
- Multi-Step Reasoning. Muse Glimmer chains reasoning over long horizons, sustaining coherent plans across complex, extended workflows. [...]
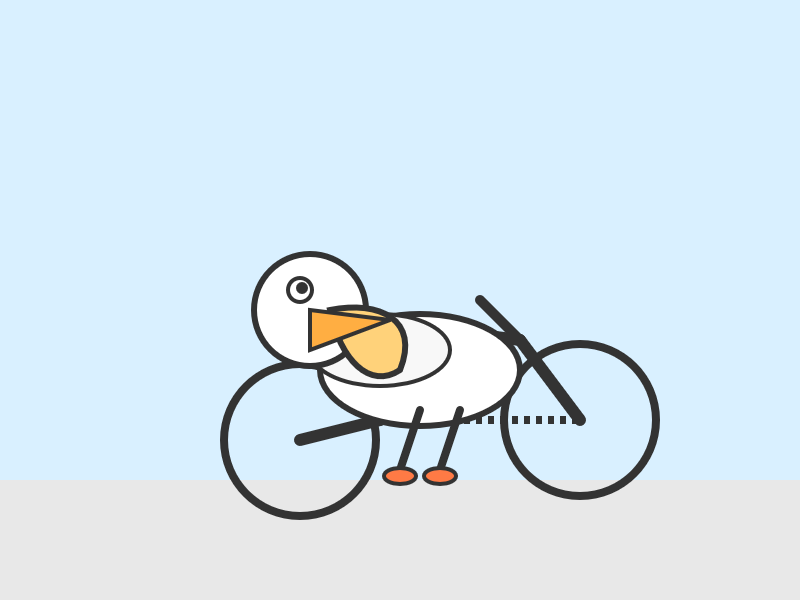
Here's a pelican which I generated using LM Studio's 18.16 GB version of the model:
I also tried it out with my llm-coding-agent plugin, running against a fresh checkout of Datasette with the prompt:
how does auth work?
Here's the response, at the end of a long transcript showing all of the tool calls it made to explore the codebase. I ran this using llm-lmstudio with this patch applied to upgrade it for compatibility with LLM 0.32.
I really like this size of model, because if a machine has 32 GB of RAM or more (mine has 128GB) it leaves plenty of space for running other applications at the same time.
Glimmer is a vision model, so I asked it to describe this image:
llm -m lmstudio/meta/muse-glimmer -a https://static.inaturalist.org/photos/714731804/large.jpg 'describe image'
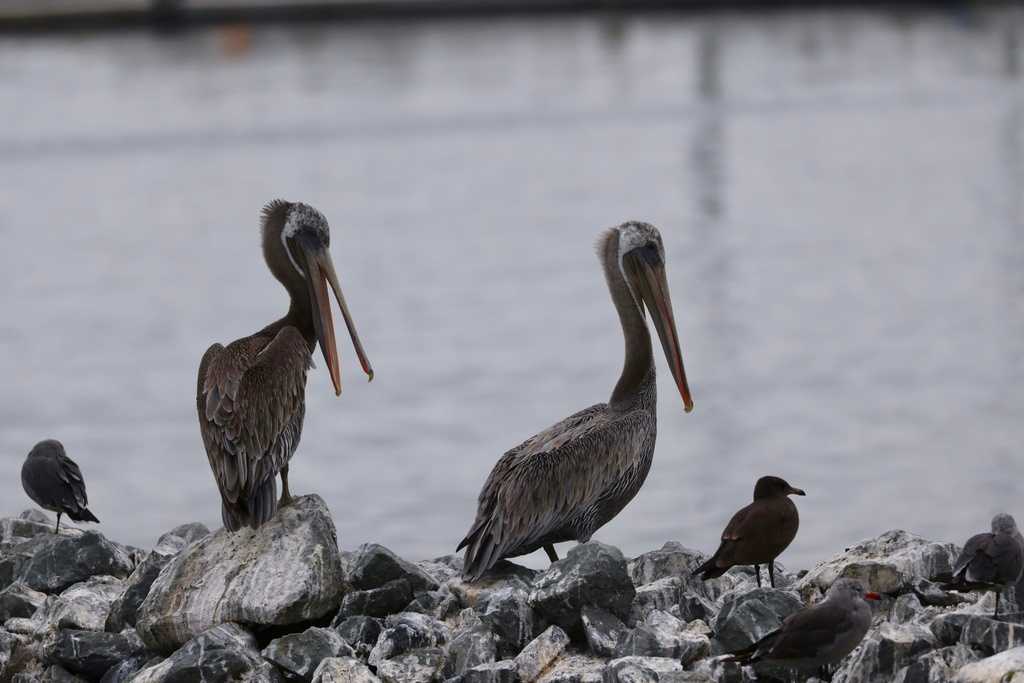
Here's what I got back:
The photograph shows a rocky, breakwater-style shoreline on an overcast day with a smooth, gray body of water and a faint dock/pier line in the soft-focused background.
In the foreground two large brown pelicans, Pelecanus occidentalis, are perched on the jumbled gray-white stones. They have the species’ characteristic long, down-curved yellow-orange bills with a large throat pouch, long slender necks and mottled brown-gray plumage on the back and wings. The pelican on the left is turned slightly toward the camera and appears to be preening or resting its bill against its chest; a pale, whitish patch is visible on the crown and nape and a small crest of feathers is raised. The pelican on the right faces mostly forward/right, its head up, bill pointing down and to the right, with the same pale head markings and the barred, darker wing feathers clearly visible.
Scattered among the rocks around the two pelicans are several much smaller dark birds — gulls/tern-like birds in muted brown-gray plumage. One dark bird sits on the far left on a rock, another brownish bird stands to the right of the right-hand pelican, a grayish bird with a reddish bill is in the lower right foreground, and a further small dark bird is at the extreme right edge of the frame.
The overall light is flat and diffused, giving the water and sky a muted, almost monochromatic palette that contrasts with the textured rock and the detailed feathering of the pelicans. The composition places the two big birds as the dominant subjects, framed against the calm water and the low, rocky perch.
Via Hacker News
Tags: ai, generative-ai, llama, local-llms, llms, llm, vision-llms, meta, llm-release
Other reports on this story
- T2TechCrunch:AI(RSS)Meta's open-weight Muse Glimmer model hints at Zuckerberg's personal superintelligence vision00:20
Related items
FeaturedDeepSeek V4 Doubles Token Share on OpenRouter, Driven by Agentic Workloads
DeepSeek V4 在 OpenRouter 上的代币份额翻倍,智能体工作负载成主要驱动力
The rapid adoption of DeepSeek V4 signals a strong market preference for high-performance, low-cost inference models, especially as agentic use cases reshape AI deployment.
91
FeaturedEnabling Two Settings Triples ARC-AGI-3 Benchmark Scores
启用两项设置使ARC-AGI-3基准测试分数提升三倍
This finding is crucial! It shows that model performance depends not only on training but also on inference-time configuration. For AI engineers and researchers, this is a must-know optimization direction. Teams deploying models on resource-constrained devices in particular could find a low-cost way to boost capabilities.
91
FeaturedGPT-5.6: Fusing Frontier Intelligence with Frontier Efficiency
GPT-5.6:前沿智能与前沿效率的融合
This news is worth watching as it marks a shift from pure parameter scaling to efficiency competition. For AI developers and business decision-makers, GPT-5.6 means higher performance at lower cost, especially for long-context or agentic tasks previously hindered by inference expenses. OpenAI's move may redefine what 'frontier' means.
91
FeaturedLFM2.5-Encoders: New Models for Fast Long-Context Inference on CPU
LFM2.5-Encoder:面向CPU快速长上下文推理的新模型
This blog post catches my eye because it directly solves the pain point of running long-context LLMs on CPU. For teams or individual developers without high-end GPUs, the LFM2.5-Encoder series offers a ready-to-use open-source solution. Highly recommended for those working on RAG, document search, or code analysis—now a standard server can handle million-token documents.
91
FeaturedGPT-Red: OpenAI Automates Red Teaming via Self-Play to Boost Model Robustness
GPT-Red:OpenAI通过自我对弈实现AI红队自动化,提升模型鲁棒性
GPT-Red marks a milestone from human to automated red-teaming—essential for safety engineers and alignment researchers. While reducing cost, it also raises ethical questions about automated attacks, worth pondering for everyone in AI governance.
91
FeaturedOpenAI Launches GPT-5.5 Bio Bug Bounty Program
OpenAI推出GPT-5.5生物漏洞赏金计划
This program deserves attention as it pioneers the extension of AI bug bounty to biosecurity, offering a new research direction for the security community and a practical training ground for AI risk governance. It is particularly important for model safety researchers, biosecurity experts, and practitioners concerned about dual-use AI risks.
91
FeaturedvLLM Introduces Native-Speed Transformers Modeling Backend for Enhanced Inference Performance
vLLM推出原生速度Transformers建模后端,大幅提升推理性能
This update is critical for AI engineering teams: eliminating format conversion speeds up model iteration, and 2-5x speedup directly reduces GPU costs. If you're building LLM online services or batch inference, this is practically a must-read technical update.
90
FeaturedGoogle DeepMind Introduces SL2T, a Sign Language-to-Text Model for Deaf Users
Google DeepMind 发布手语转文本模型 SL2T,助力聋人用户
This news matters not only as a technical breakthrough but also as a sign that AI is beginning to address the needs of marginalized groups. For developers, the architecture and technical approach of SL2T merit deep study; for accessibility advocates, it's a key case for advancing industry standards.