Moonshot AI Releases Kimi K3: 2.8 Trillion Parameter Open-Weight Model Outperforming Most Competitors
Score
76提供了 K3 详细参数、定价、基准对比及实际测试结果,信息增量较高
作者基于第一手测试和第三方评测,分析深入且客观
对开发者选型有参考价值,但鹈鹕测试的意义有限
发布时间与博客日期一致,为最新动态
Simon Willison 是权威的 AI 技术博客作者,信源可信度高
Base 84.5 × T2 Source weight ×0.9 = 76
Curation line 70Selected
Why selected
Based on first-hand testing and third-party analysis, providing detailed and practical insights
AI commentary
「Kimi K3's release marks a breakthrough for Chinese AI labs in large open-weight models, with 2.8T parameters and a promised open-source date. For developers, pricing is key—$3/$15 per million tokens is expensive compared to earlier Kimi models but still half of Opus 4.8. However, the heavy reasoning token usage revealed by real-world testing could drive up long-term costs. Its top ranking on Arena.ai's Frontend Code arena suggests a unique strength in code generation worth exploring.」
Quick overview
Moonshot AI announced Kimi K3 on July 16, 2026, claiming 2.8 trillion parameters, making it the largest open-weight model to date. It beats Claude Opus 4.8 and GPT-5.5 on most benchmarks, trailing only Claude Fable 5 and GPT-5.6 Sol. Pricing is $3/M input tokens and $15/M output tokens, higher than K2.6 but still below Opus 4.8. Simon Willison's 'pelican on a bicycle' test reveals heavy reasoning token usage (13,241 tokens) costing $0.25 per generation, though vision capability is strong. Open-weight release is promised by July 27, 2026.
- 2.8 trillion parameters, largest open-weight model, open-source promised by July 27
- Self-reported benchmarks beat Claude Opus 4.8 and GPT-5.5, behind only Fable 5 and Sol
- Pricing at $3/$15 per million tokens, higher than K2.6 but half the cost of Opus 4.8
- Real-world test shows massive reasoning usage (13k+ tokens), single pelican SVG cost $0.25
Full text
Showing the source text; the full translation is being generated.
Chinese AI lab Moonshot AI announced Kimi K3 this morning, describing it as their "most capable model to date, with 2.8 trillion parameters". It's currently available via their website and API, but an open weight release is promised "by July 27, 2026".
Moonshot are calling this the first "open 3T-class model" (I guess they're rounding 2.8 trillion up to 3 trillion), taking the crown from DeepSeek's 1.6T v4 Pro. Their self-reported benchmarks have K3 mostly beating Claude Opus 4.8 max and GPT-5.5 high, while losing out to Claude Fable 5 and GPT-5.6 Sol.
A few highlights from the Artificial Analysis report on the model:
- "On our private long-horizon knowledge work evaluation, Kimi K3 reaches an overall Elo of 1547, +732 points from Kimi K2.6 and behind only Claude Fable 5."
- "Cost per task ($0.94) is similar to GPT-5.6 Sol ($1.04), ~1/2 the price of Opus 4.8 ($1.80) and higher than open weights peers"
- "Kimi K3’s token usage on the Artificial Analysis Intelligence Index decreased significantly, using 21% fewer output tokens than K2.6."
The model is also now the leading model on Arena.ai's Frontend Code arena, surpassing even Claude Fable 5.
The new model is notable for the pricing: $3/million input tokens and $15/million output tokens, putting it at the same level as Anthropic's Claude Sonnet series and making it the most expensive model released by a Chinese AI lab to date. This is a significant increase on their earlier models such as Kimi K2.6 at $0.95/$4. 2.8 trillion parameters is also more than twice the size of that 1T model.
But how does it pelican?
I used OpenRouter (to avoid signing up for a Moonshot API key) with the llm-openrouter plugin to generate an SVG of a pelican riding a bicycle:
llm -m openrouter/moonshotai/kimi-k3 'Generate an SVG of a pelican riding a bicycle'
Here's the transcript. It looks like this:
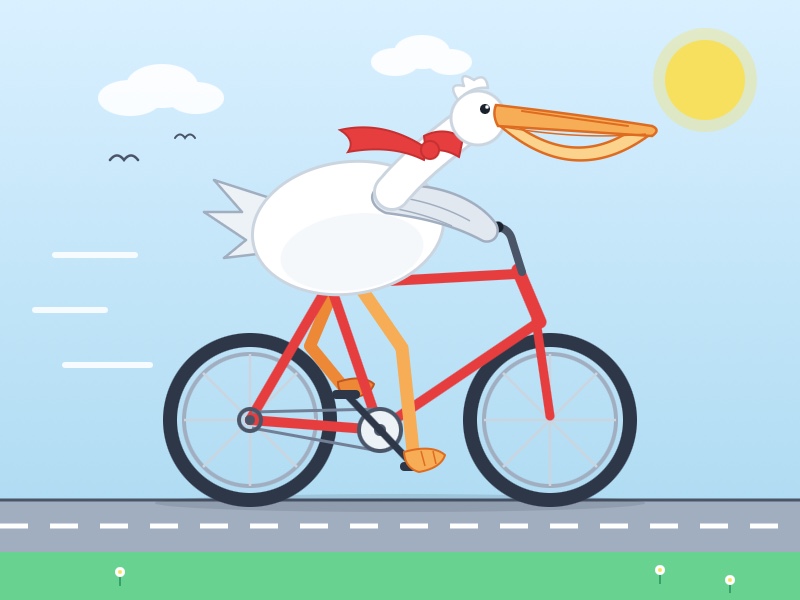
That pelican took 95 input tokens and 16,658 output tokens (13,241 were reasoning tokens), for a total cost of 25 cents!
Since K3 accepts image input I ran it against that rendered SVG above (with my alt text prompt) and got back (for 0.6 cents):
Cartoon illustration of a white pelican wearing a red scarf, riding a red bicycle along a gray road with white dashed lines; the pelican has a large orange beak and webbed orange feet pedaling, with white motion lines behind it; the background shows a light blue sky with white clouds, a yellow sun, two small black birds in flight, and green grass with tiny white flowers in the foreground
What can we learn from the pelican?
My Generate an SVG of a pelican riding a bicycle test is 21 months old now. It was never a particularly great benchmark. It started out as a joke on how absurdly difficult it is to compare these models, but then for the first year it turned out to have a surprising correlation to how good the models actually were.
That connection has been mostly severed now. The GPT-5.6 and Claude Fable 5 pelicans are outclassed by GLM-5.2, and much as I love GLM I don't think that's a Fable-class model.
(I'm still not convinced that labs are training for the benchmark - if they were, I'd expect much better results. There's a chance that Gemini has optimized for any combination of an animal on a vehicle though!)
The biggest limitation of the pelican is that it doesn't touch at all on the thing that matters most for today's model: agentic tool calling and the ability to operate tools reliably as conversations grow in length.
So don't go using pelicans to compare models!
All of that said, I still get a decent amount of value out of running the benchmark myself.
Firstly, it's a forcing function for actually trying the model. If I show you a pelican, that means I've managed to run a prompt through it. If the model has an official API I'll use that, if it's open weight (and small enough to fit a 128GB M5 MacBook Pro) I'll try running it on my own machine, usually via llama.cpp or LM Studio or Ollama. I'll frequently use OpenRouter since that usually provides a proxy to an official API without me needing a new API key.
Most of my pelicans are generated using my LLM CLI tool, which helps encourage me to ensure the latest models are supported by that (via one of its plugins).
More importantly though, even the act of a single prompt to "Generate an SVG of a pelican riding a bicycle" can reveal interesting model characteristics.
Consider the result for Kimi K3 today. Running those simple prompts helped emphasize several points about the model.
- It only has one reasoning effort right now, "max" - and it shows. The model consumed 13,241 reasoning tokens to output 3,417 tokens of response. This is expensive - the pelican cost 25 cents!
- How does the prompt "Generate an SVG of a pelican riding a bicycle" add up to 95 input tokens? OpenAI's tokenizer counts 10, Anthropic's counts 10 for Opus 4.6, 30 for Opus 4.7 and 25 for Sonnet 5/Fable 5. Prompting "hi" to Kimi K3 counted 86 tokens, suggesting there may be an 85 token hidden system prompt. It refused to leak it though.
- Vision works well: the alt text it generated is very good.
K3 currently only has one thinking effort level, but I've been deriving quite a bit of value recently from running the same pelican prompt through different effort levels to get a quick idea for what impact those have. Here's my matrix for the GPT-5.6 model family, for example.
Really though the main things I gain from the pelican test are:
- It's a "hello world" exercise for prompting a model
- A rough cost and reasoning estimate for a simple task
- Confirmation that the model can output valid SVG and has a basic idea of geometry and spatial awareness. This is a much bigger deal for the smaller models that run on my laptop.
- It's still interesting to compare pelicans between releases in the same model family. K3's pelican is a notable improvement from Kimi 2.5.
- It's something I can share that demonstrates I've tried it. Plus a comment with a pelican in it is kind of a tradition on Hacker News at this point, any time I'm late I get comments asking where it is!
Tags: ai, generative-ai, llms, llm-pricing, pelican-riding-a-bicycle, llm-release, ai-in-china, artificial-analysis, moonshot, kimi
Other reports on this story
- T2TechCrunch:AI(RSS)Moonshot's Kimi 3 Expected to Reach 2-3 Trillion Parameters, Closing Gap with Anthropic's Opus 4.822:26
Related items
FeaturedDeepSeek V4 Doubles Token Share on OpenRouter, Driven by Agentic Workloads
DeepSeek V4 在 OpenRouter 上的代币份额翻倍,智能体工作负载成主要驱动力
The rapid adoption of DeepSeek V4 signals a strong market preference for high-performance, low-cost inference models, especially as agentic use cases reshape AI deployment.
91
FeaturedEnabling Two Settings Triples ARC-AGI-3 Benchmark Scores
启用两项设置使ARC-AGI-3基准测试分数提升三倍
This finding is crucial! It shows that model performance depends not only on training but also on inference-time configuration. For AI engineers and researchers, this is a must-know optimization direction. Teams deploying models on resource-constrained devices in particular could find a low-cost way to boost capabilities.
91
FeaturedGPT-5.6: Fusing Frontier Intelligence with Frontier Efficiency
GPT-5.6:前沿智能与前沿效率的融合
This news is worth watching as it marks a shift from pure parameter scaling to efficiency competition. For AI developers and business decision-makers, GPT-5.6 means higher performance at lower cost, especially for long-context or agentic tasks previously hindered by inference expenses. OpenAI's move may redefine what 'frontier' means.
91
FeaturedLFM2.5-Encoders: New Models for Fast Long-Context Inference on CPU
LFM2.5-Encoder:面向CPU快速长上下文推理的新模型
This blog post catches my eye because it directly solves the pain point of running long-context LLMs on CPU. For teams or individual developers without high-end GPUs, the LFM2.5-Encoder series offers a ready-to-use open-source solution. Highly recommended for those working on RAG, document search, or code analysis—now a standard server can handle million-token documents.
91
FeaturedGPT-Red: OpenAI Automates Red Teaming via Self-Play to Boost Model Robustness
GPT-Red:OpenAI通过自我对弈实现AI红队自动化,提升模型鲁棒性
GPT-Red marks a milestone from human to automated red-teaming—essential for safety engineers and alignment researchers. While reducing cost, it also raises ethical questions about automated attacks, worth pondering for everyone in AI governance.
91
FeaturedOpenAI Launches GPT-5.5 Bio Bug Bounty Program
OpenAI推出GPT-5.5生物漏洞赏金计划
This program deserves attention as it pioneers the extension of AI bug bounty to biosecurity, offering a new research direction for the security community and a practical training ground for AI risk governance. It is particularly important for model safety researchers, biosecurity experts, and practitioners concerned about dual-use AI risks.
91
FeaturedvLLM Introduces Native-Speed Transformers Modeling Backend for Enhanced Inference Performance
vLLM推出原生速度Transformers建模后端,大幅提升推理性能
This update is critical for AI engineering teams: eliminating format conversion speeds up model iteration, and 2-5x speedup directly reduces GPU costs. If you're building LLM online services or batch inference, this is practically a must-read technical update.
90
FeaturedGoogle DeepMind Introduces SL2T, a Sign Language-to-Text Model for Deaf Users
Google DeepMind 发布手语转文本模型 SL2T,助力聋人用户
This news matters not only as a technical breakthrough but also as a sign that AI is beginning to address the needs of marginalized groups. For developers, the architecture and technical approach of SL2T merit deep study; for accessibility advocates, it's a key case for advancing industry standards.